Spark X2.6 4B personal-agent test: thinking mode helps tools but adds latency
The author re-benchmarks Spark X2.5/X2.6 and Qwen 3.5 4B on personal-admin tasks, finding reasoning improves tool reliability but slows responses, and X2.6 loops on one agent-context test.
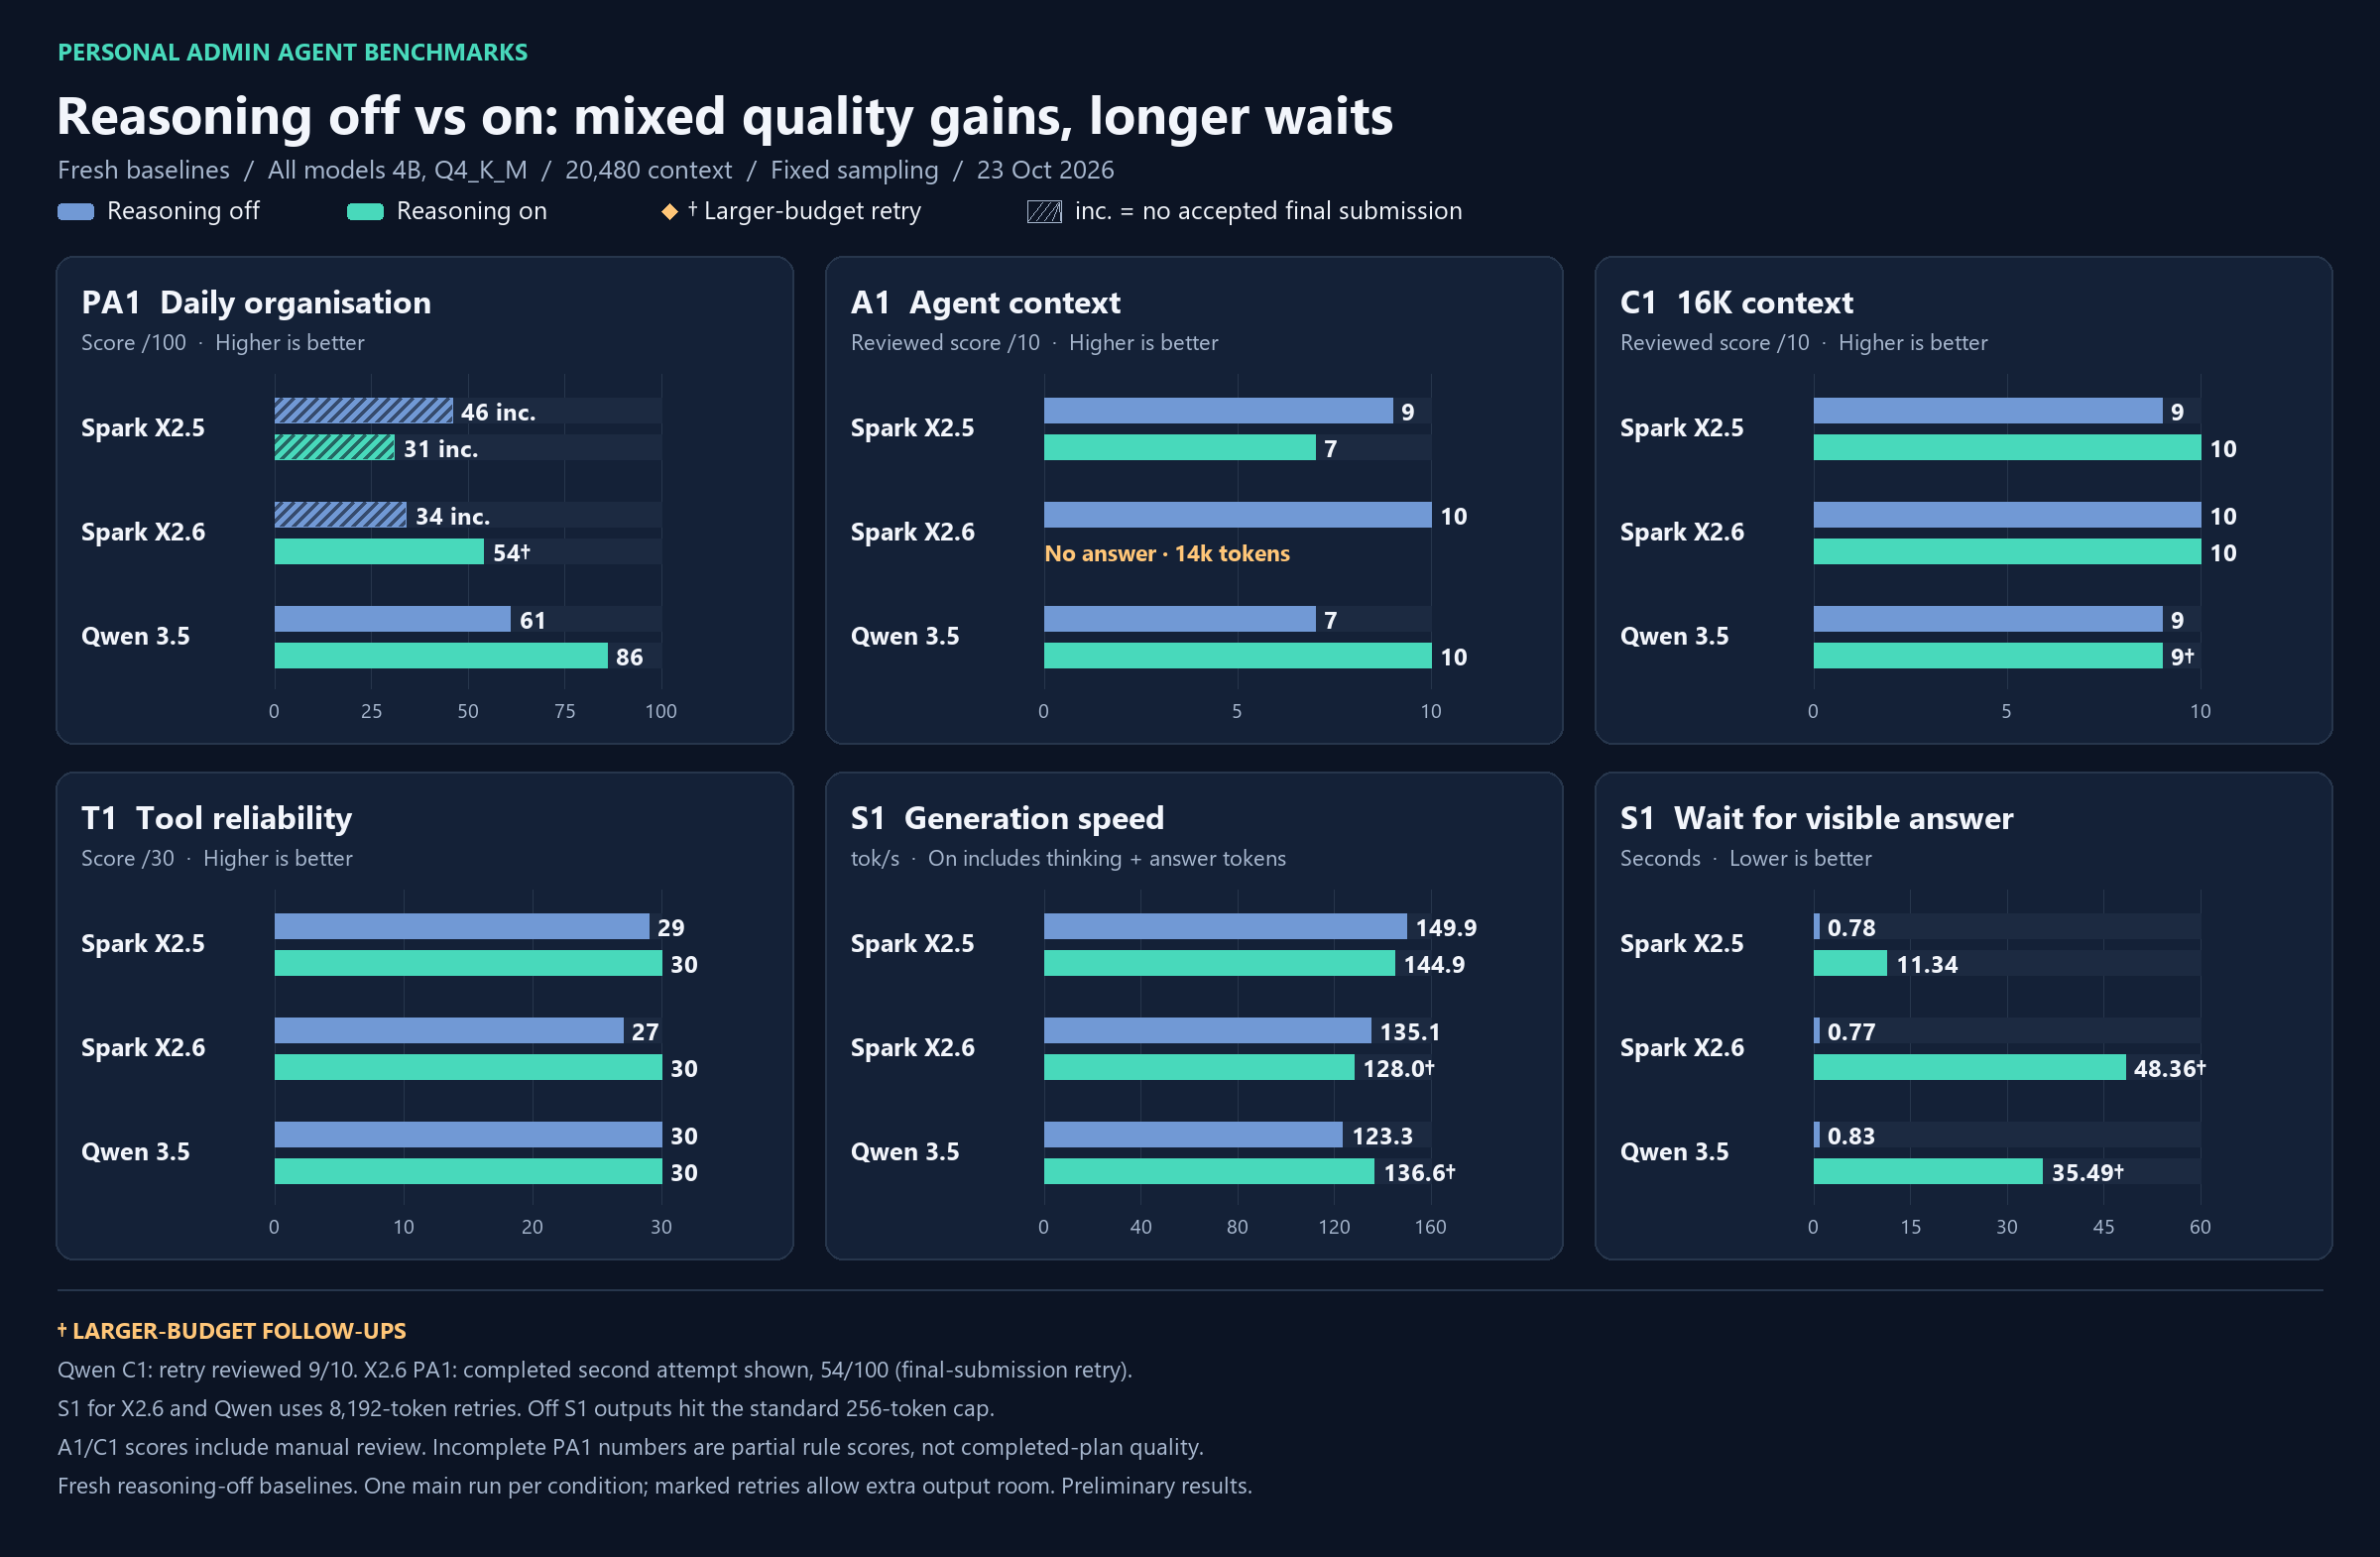
My thanks to @Tylerwtzhang from the @SparkLLM team who reached out with some advice about this. Specifically- Spark X2.6 4B is built to work better with thinking mode on. And, it is mostly improved. I re-baselined my personal agent testing (X2.5 vs X2.6, thinking off and on), and also comparing them to an incumbent (Qwen 3.5 4B). Some thoughts: - Reasoning improved some personal-admin capabilities, but it was not a consistent upgrade, and importantly, substantially increases waiting time (this is partially why my testing and interest in how good models are with thinking off, because it makes them much more responsive. - Enabling reasoning improved tool reliability for both Spark models and improved Qwen’s context handling and daily organization. Other outcomes regressed or failed to complete: Spark X2.5 introduced scope errors, while X2.6 entered a reasoning loop on the A1 agent-context test (@Tylerwtzhang I'll share more diagnosis about this offline if interested, will DM you). For a personal admin/assistant agent, the trade-off is therefore task-dependent: extra thinking sometimes delivers a better result, but it also brings longer waits and a completion failure with one case.
This post quotes another post: x.com/paulgugai/status/2113445300782166308