DeepSeek harness lifts V4.1 Flash scores 2–3 points at 80% higher cost
On the same benchmark, the DeepSeek harness scores 42.7 at max versus 39.1 with Claude Code, beating Opus 5.5's 41.7 and trailing GPT-6 Astra's 45.
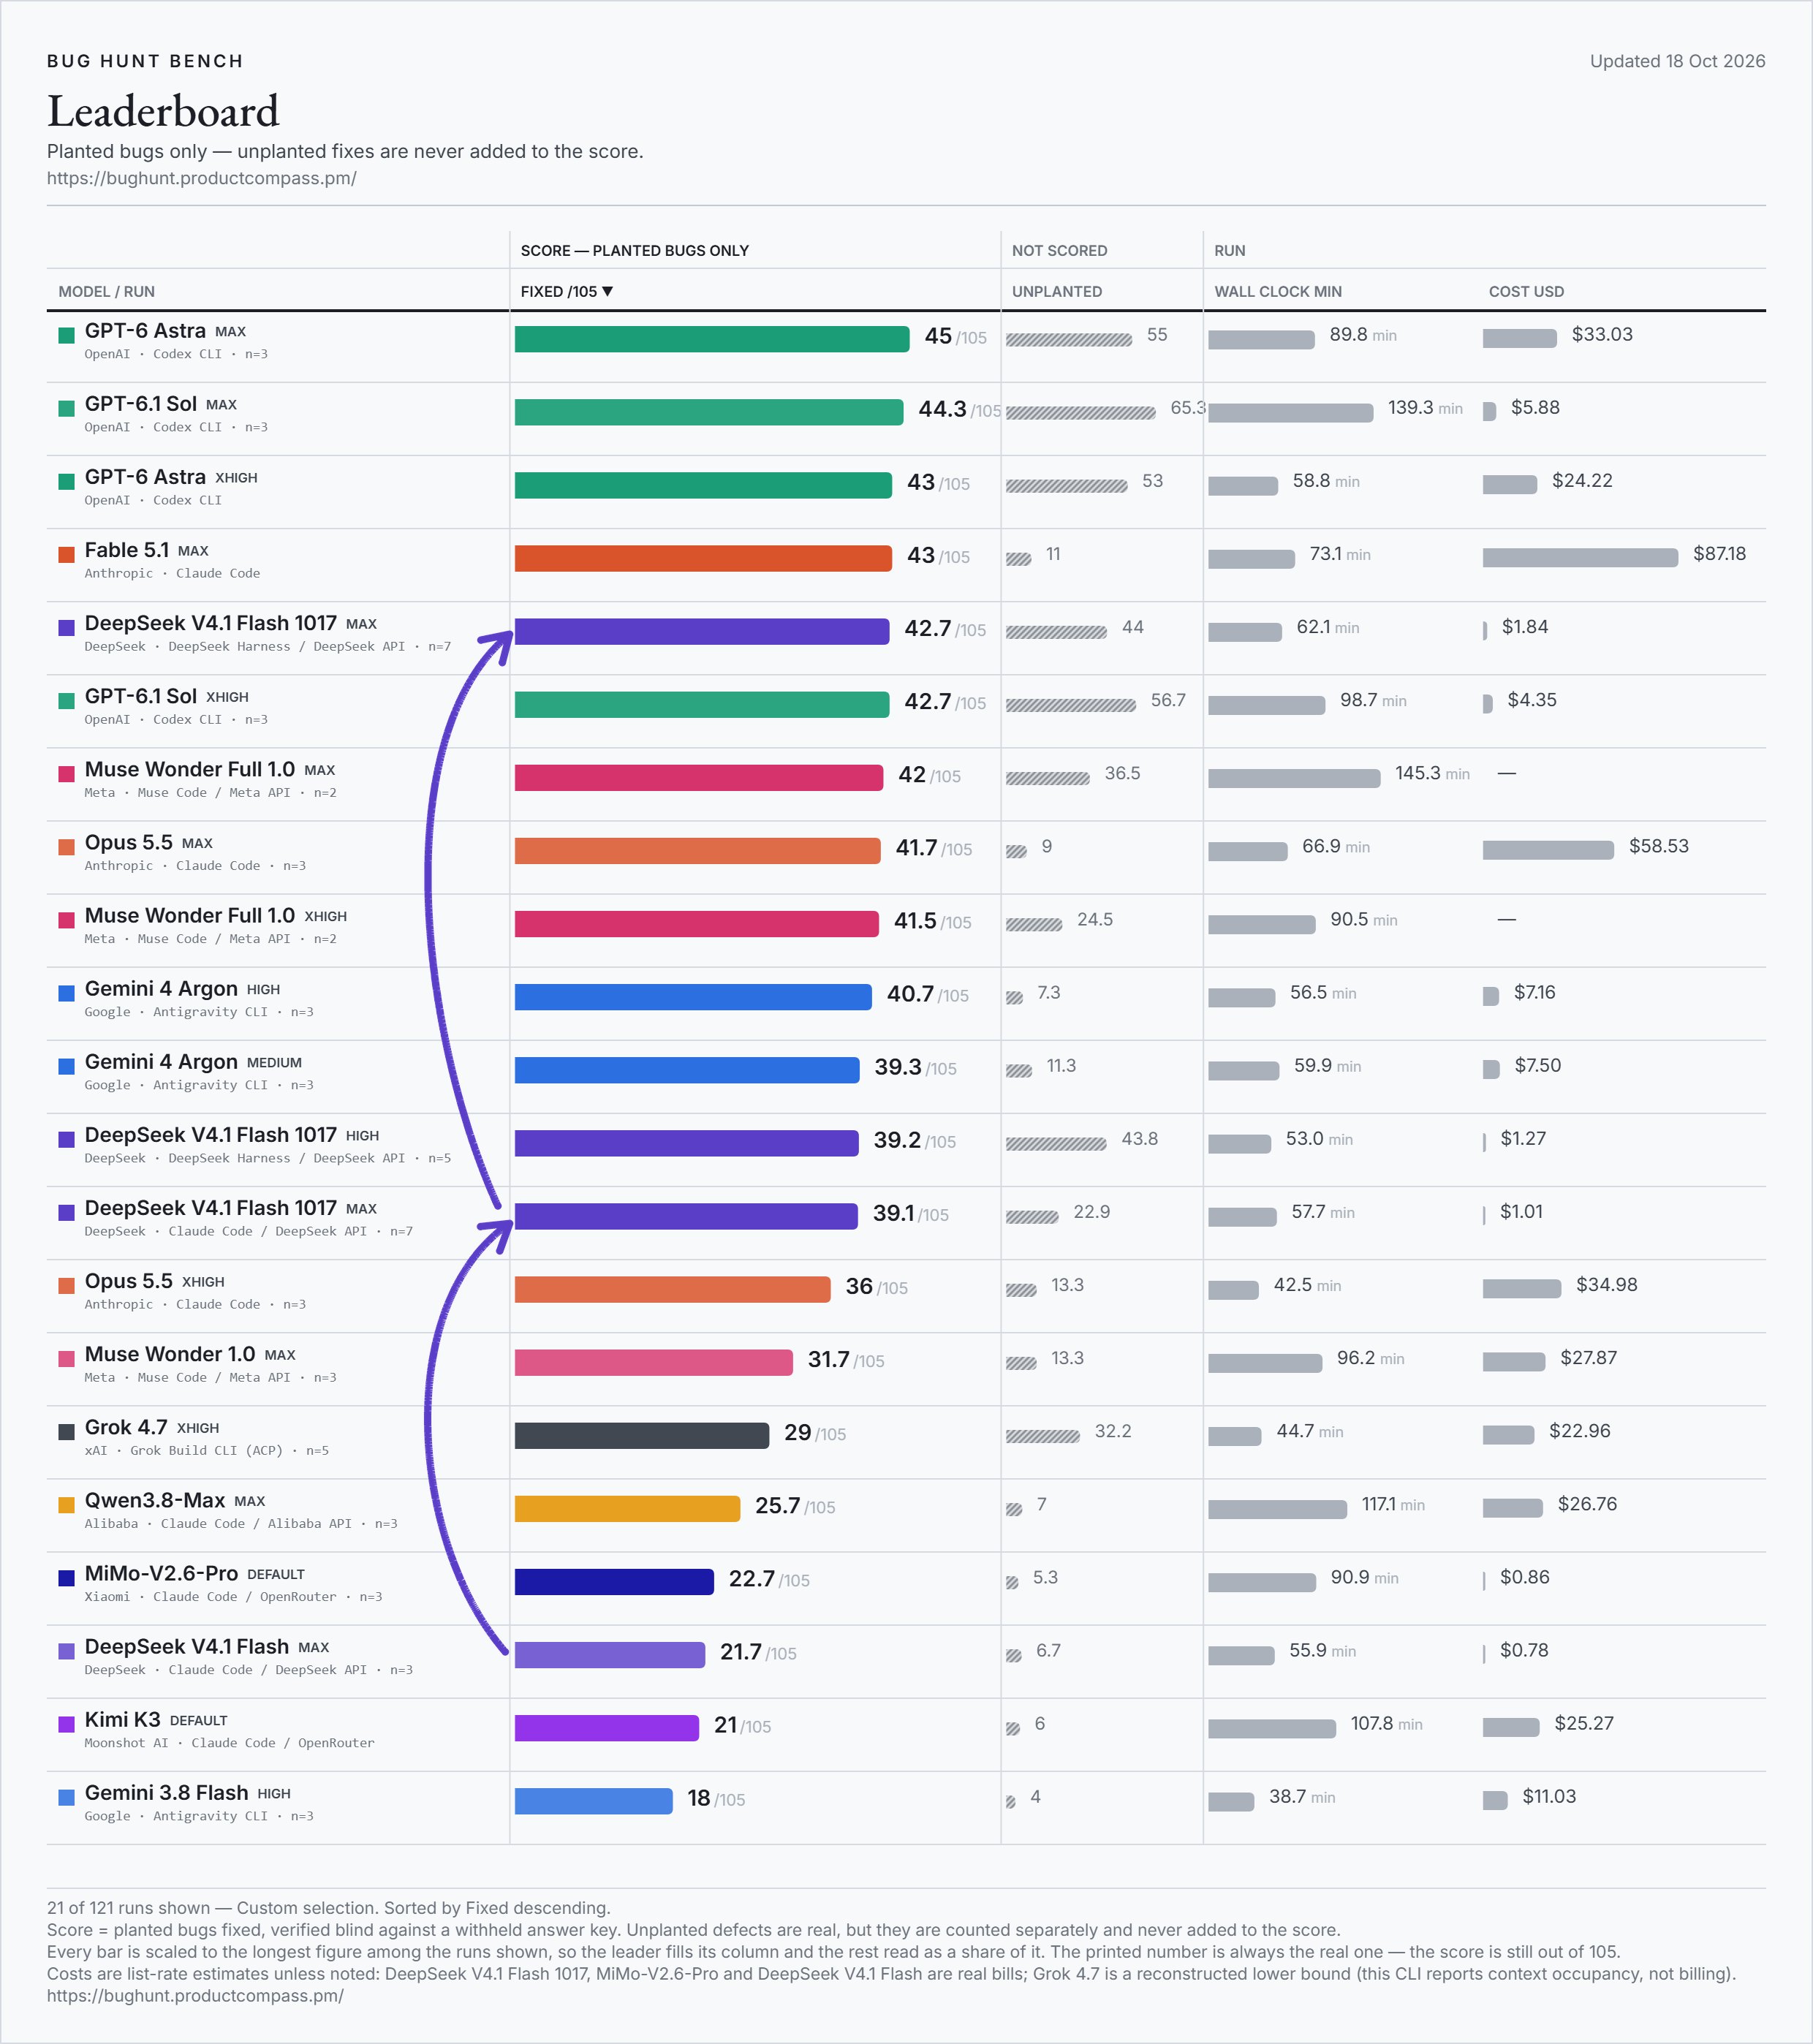
Turns out DeepSeek harness improves the score of DeepSeek V4.1 Flash by 2-3 points on average. It also costs 80% more due to subagents and more output tokens. New results: DeepSeek V4.1 Flash 1017 + Claude Code harness: - max, mean of 7: 39.1 - high, mean of 5: 36.4 - low, mean of 5: 34.4 DeepSeek V4.1 Flash 1017 + DeepSeek harness: - max, mean of 7: 42.7 - high, mean of 5: 39.2 - low, mean of 5: 34.8 For comparison: GPT-6 Astra, max: 45 Opus 5.5, max: 41.7 Muse Wonder Full 1.0, max: 42 It's a crazy model, and the only one catched cheating. All the results are available on the benchmark website.
This post quotes another post: “Multi-model benchmark: Gemini 4 Argon scores 40.7, third behind Muse Wonder and Opus 5.5”