模型发布IMAGE
BottleCap ThinkingCap: ~38.5% fewer thinking tokens for Qwen3.8-Flash-Next
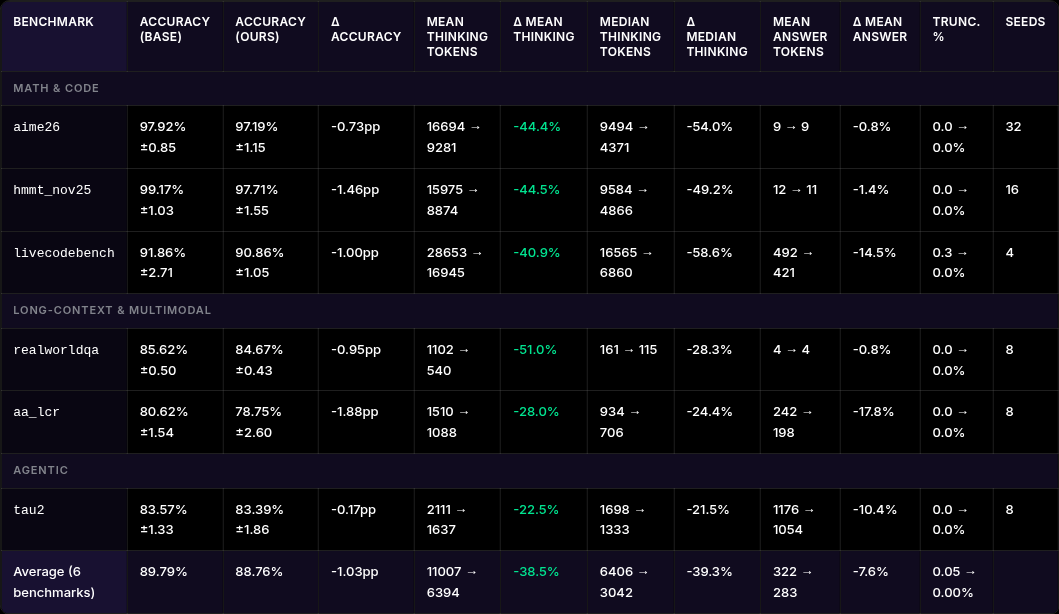
BottleCap shipped ThinkingCap, a drop-in method for Qwen3.8-Flash-Next that cuts thinking tokens by 38.5% on average across six benchmarks while accuracy drops about 1 point.
Qwen AI Fans
@QwenAIFansArchived 4 days agoOriginally posted 2026.10.24
Qwen AI Fans @QwenAIFansOriginally posted 2026.10.24
🚨 you don't need a full thinking budget to keep Qwen-level answers BottleCap just shipped ThinkingCap for Qwen3.8-Flash-Next — drop-in, same sampling, ~40% less thinking. Hard numbers (6 benches, same harness): • thinking tokens −38.5% avg (up to −51% on RealWorldQA) • accuracy 89.8% → 88.8% (−1.03pp) • AIME 2026: 16.7k → 9.3k thinking tokens (−44%) Caveat: bf16 still wants ~4×H200 (~360 GB). NVFP4 cuts that to ~132 GB. via BottleCap AI 👇 https://bottlecapai.com/post/thinkingcap-qwen3-8-flash-next/
x.com/qwenaifans/status/2113752533646909548Archived 2026.10.25 10:24