vLLM hits 954K tokens/s/GPU on DeepSeek V4.1 Flash in AgentX test
The vLLM team reports DeepSeek V4.1 Flash on SemiAnalysis AgentX reaching 954K tokens/s/GPU total throughput and 196 tok/s P90 per user, worth $38.96/GPU-hour at DeepSeek off-peak pricing.
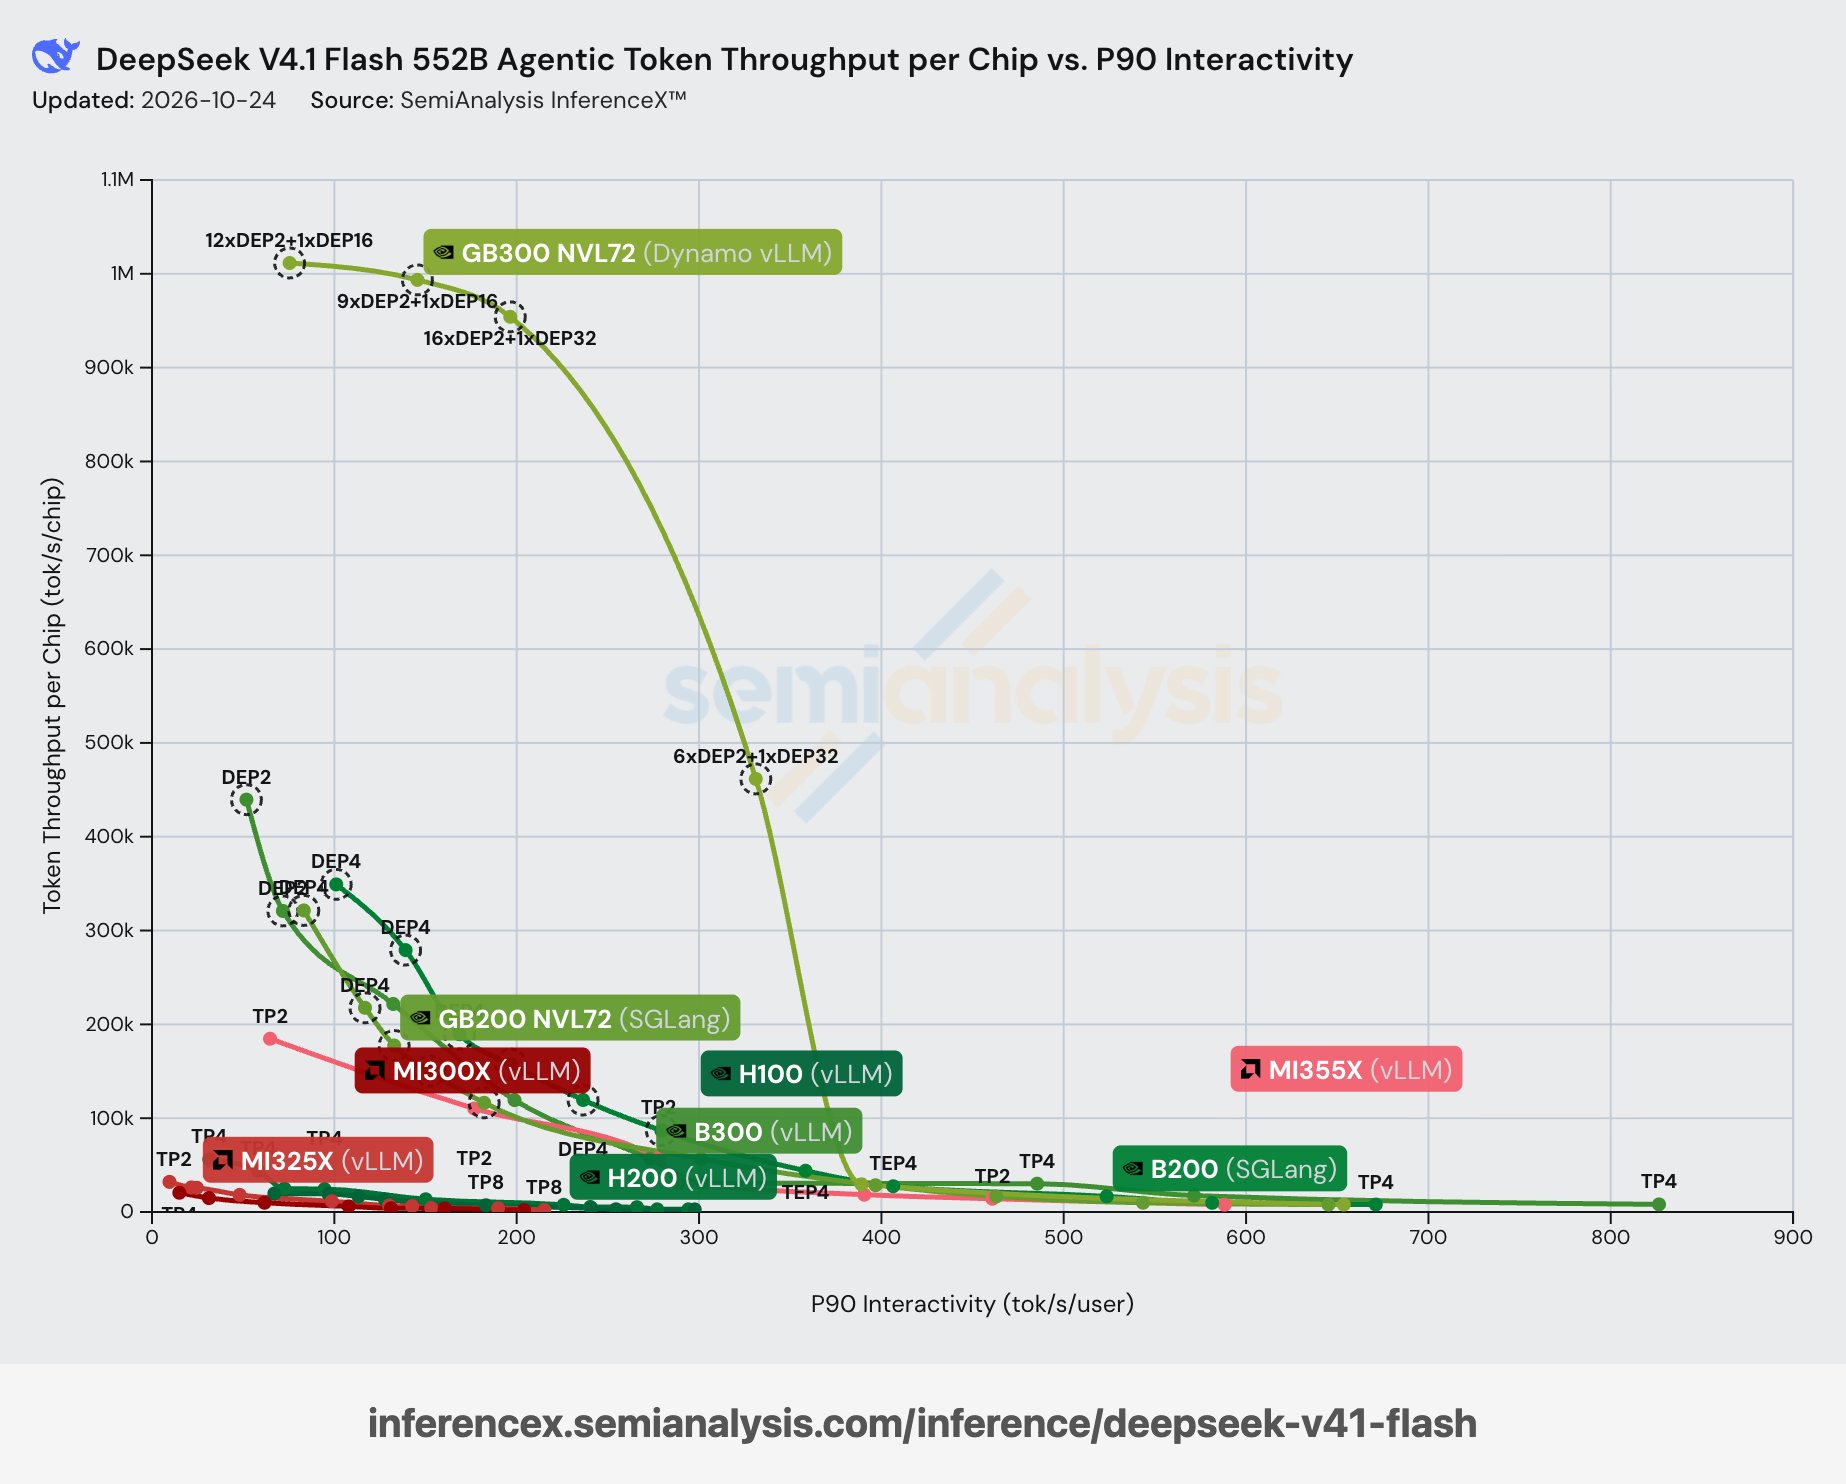
Beyond matching DeepInfer's performance, we also put vLLM to the test on @SemiAnalysis_ AgentX with real-world agentic workloads. At DeepSeek's off-peak pricing, vLLM delivers $38.96/GPU-hour revenue, with 954K tokens/s/GPU total throughput (cached+input+output) at 196 tokens/s P90 per user. This is the best DeepSeek-V4.1-Flash result on AgentX ever, powered by recent advancement in vLLM! Check out our blog for the full optimization story and how to reproduce the results 👇 Enjoy the read.
This post quotes another post: “vLLM serves DeepSeek V4.1 Flash on GB300 NVL72 at 954K tokens/s per GPU”