Inference team defends DeepSeek V4.1 Flash benchmarks as using real input distributions
The author says their DeepSeek-V4.1-Flash benchmarks use real input distributions, realistic expert routing and the same serving configs validated on SemiAnalysis AgentX, and were online Oct 20 before DeepInfer shipped.
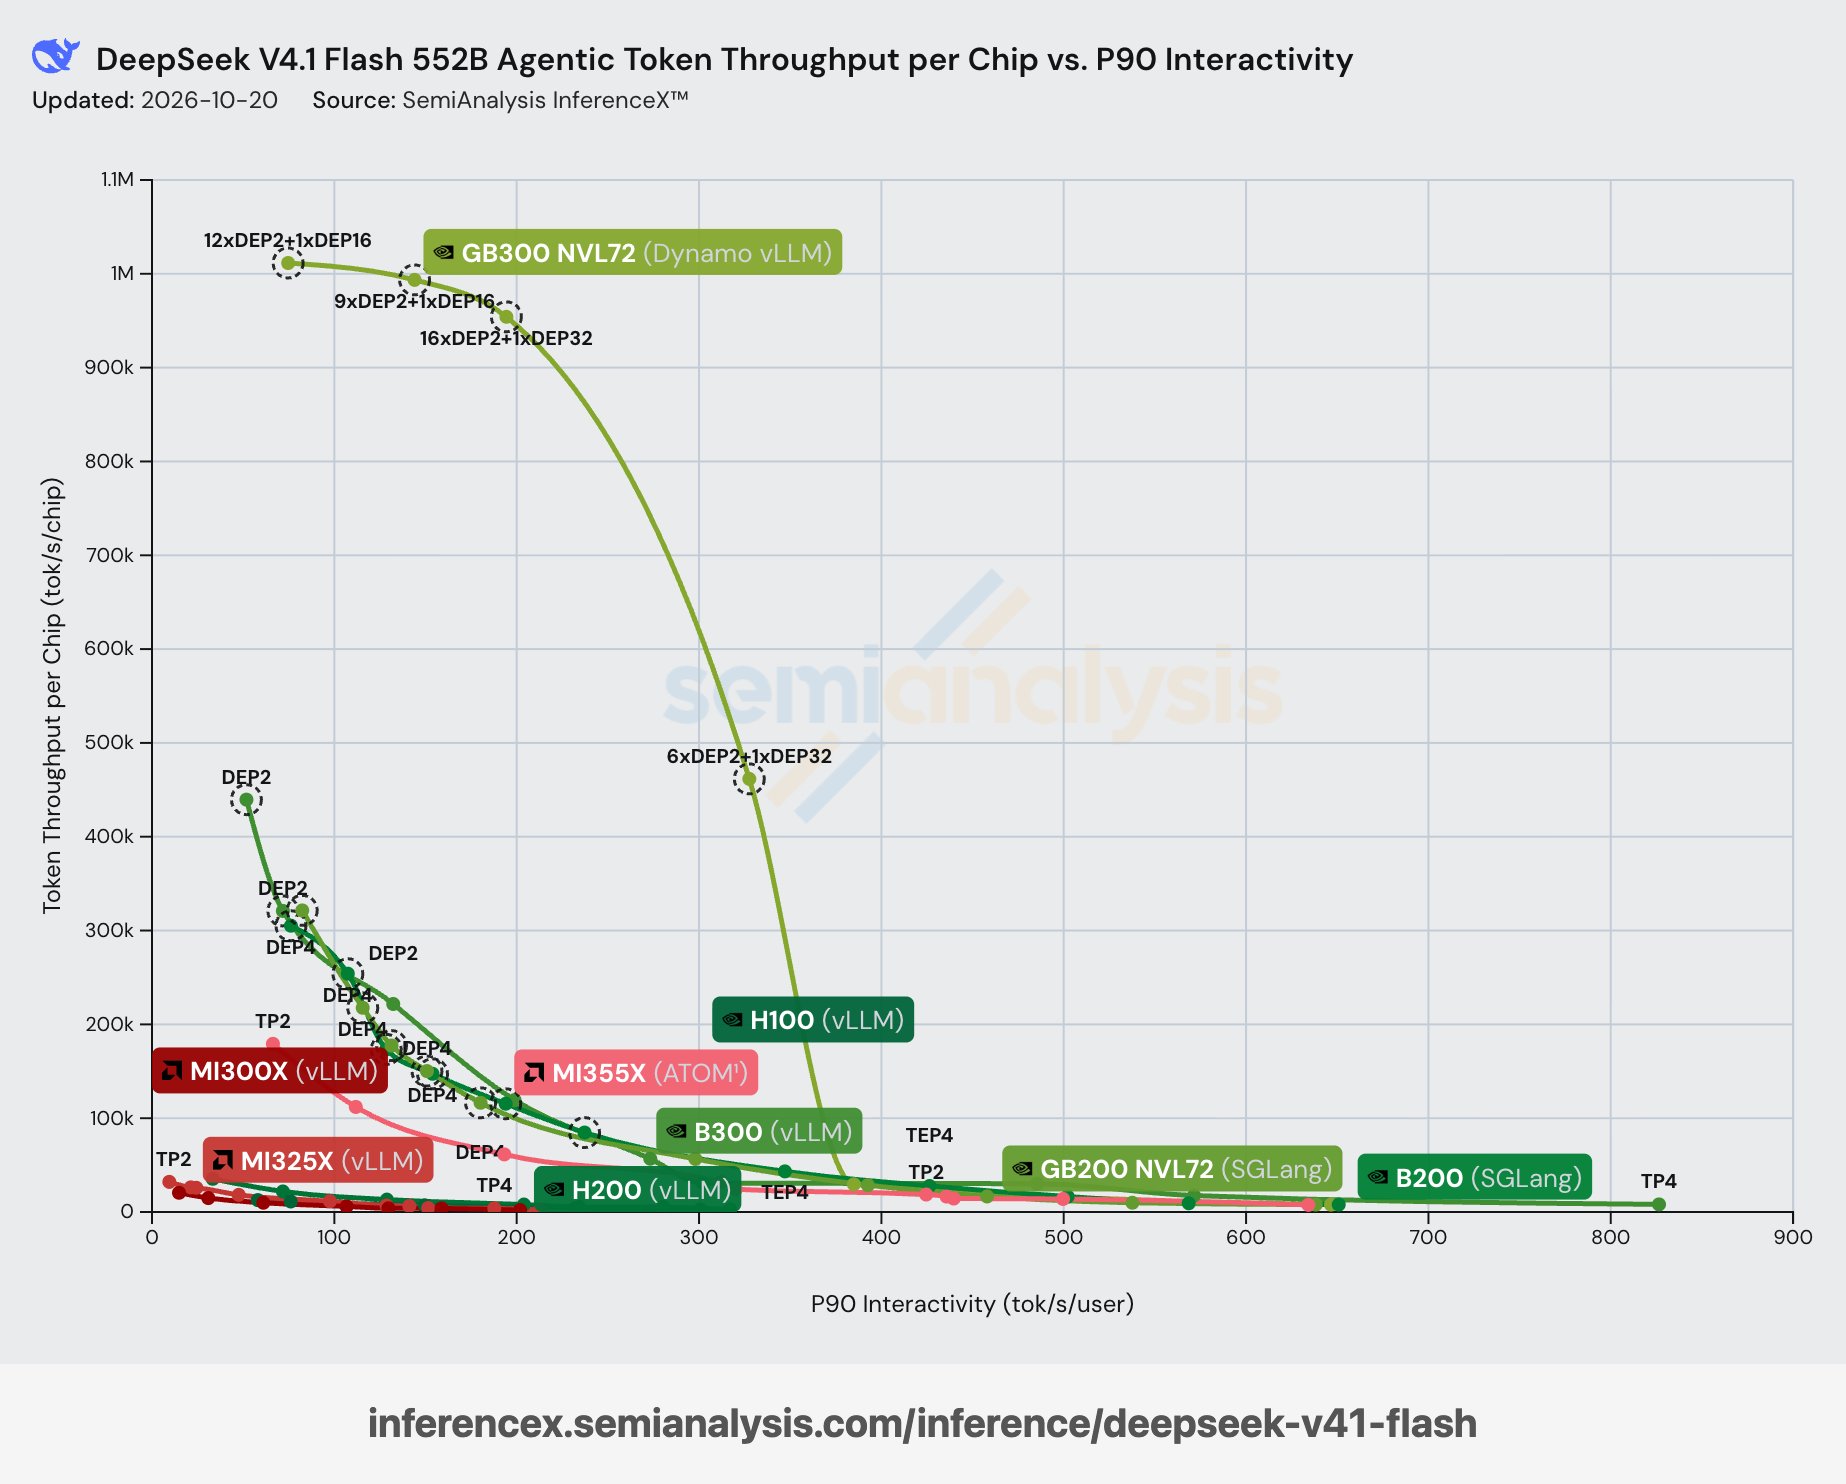
It's easy to make inference benchmarks look impressive with random inputs and idealized expert routing. The harder part is making those numbers hold up on real workloads. Our DeepSeek-V4.1-Flash benchmarks use real input distributions, realistic expert routing, and the same serving configurations validated on @SemiAnalysis_ AgentX. Fun fact: our results have been online since Oct. 20, even before DeepInfer's release. And we'll deliver even more speedups! Synthetic benchmarks have their place, but let's be clear about what they actually measure. Check out our blog for the full optimization story and benchmarking methodology!
This post quotes another post: “vLLM serves DeepSeek V4.1 Flash on GB300 NVL72 at 954K tokens/s per GPU”