HealthBench Professional 红队对话:V4.1 Flash 得分 30%,GPT-6 Astra
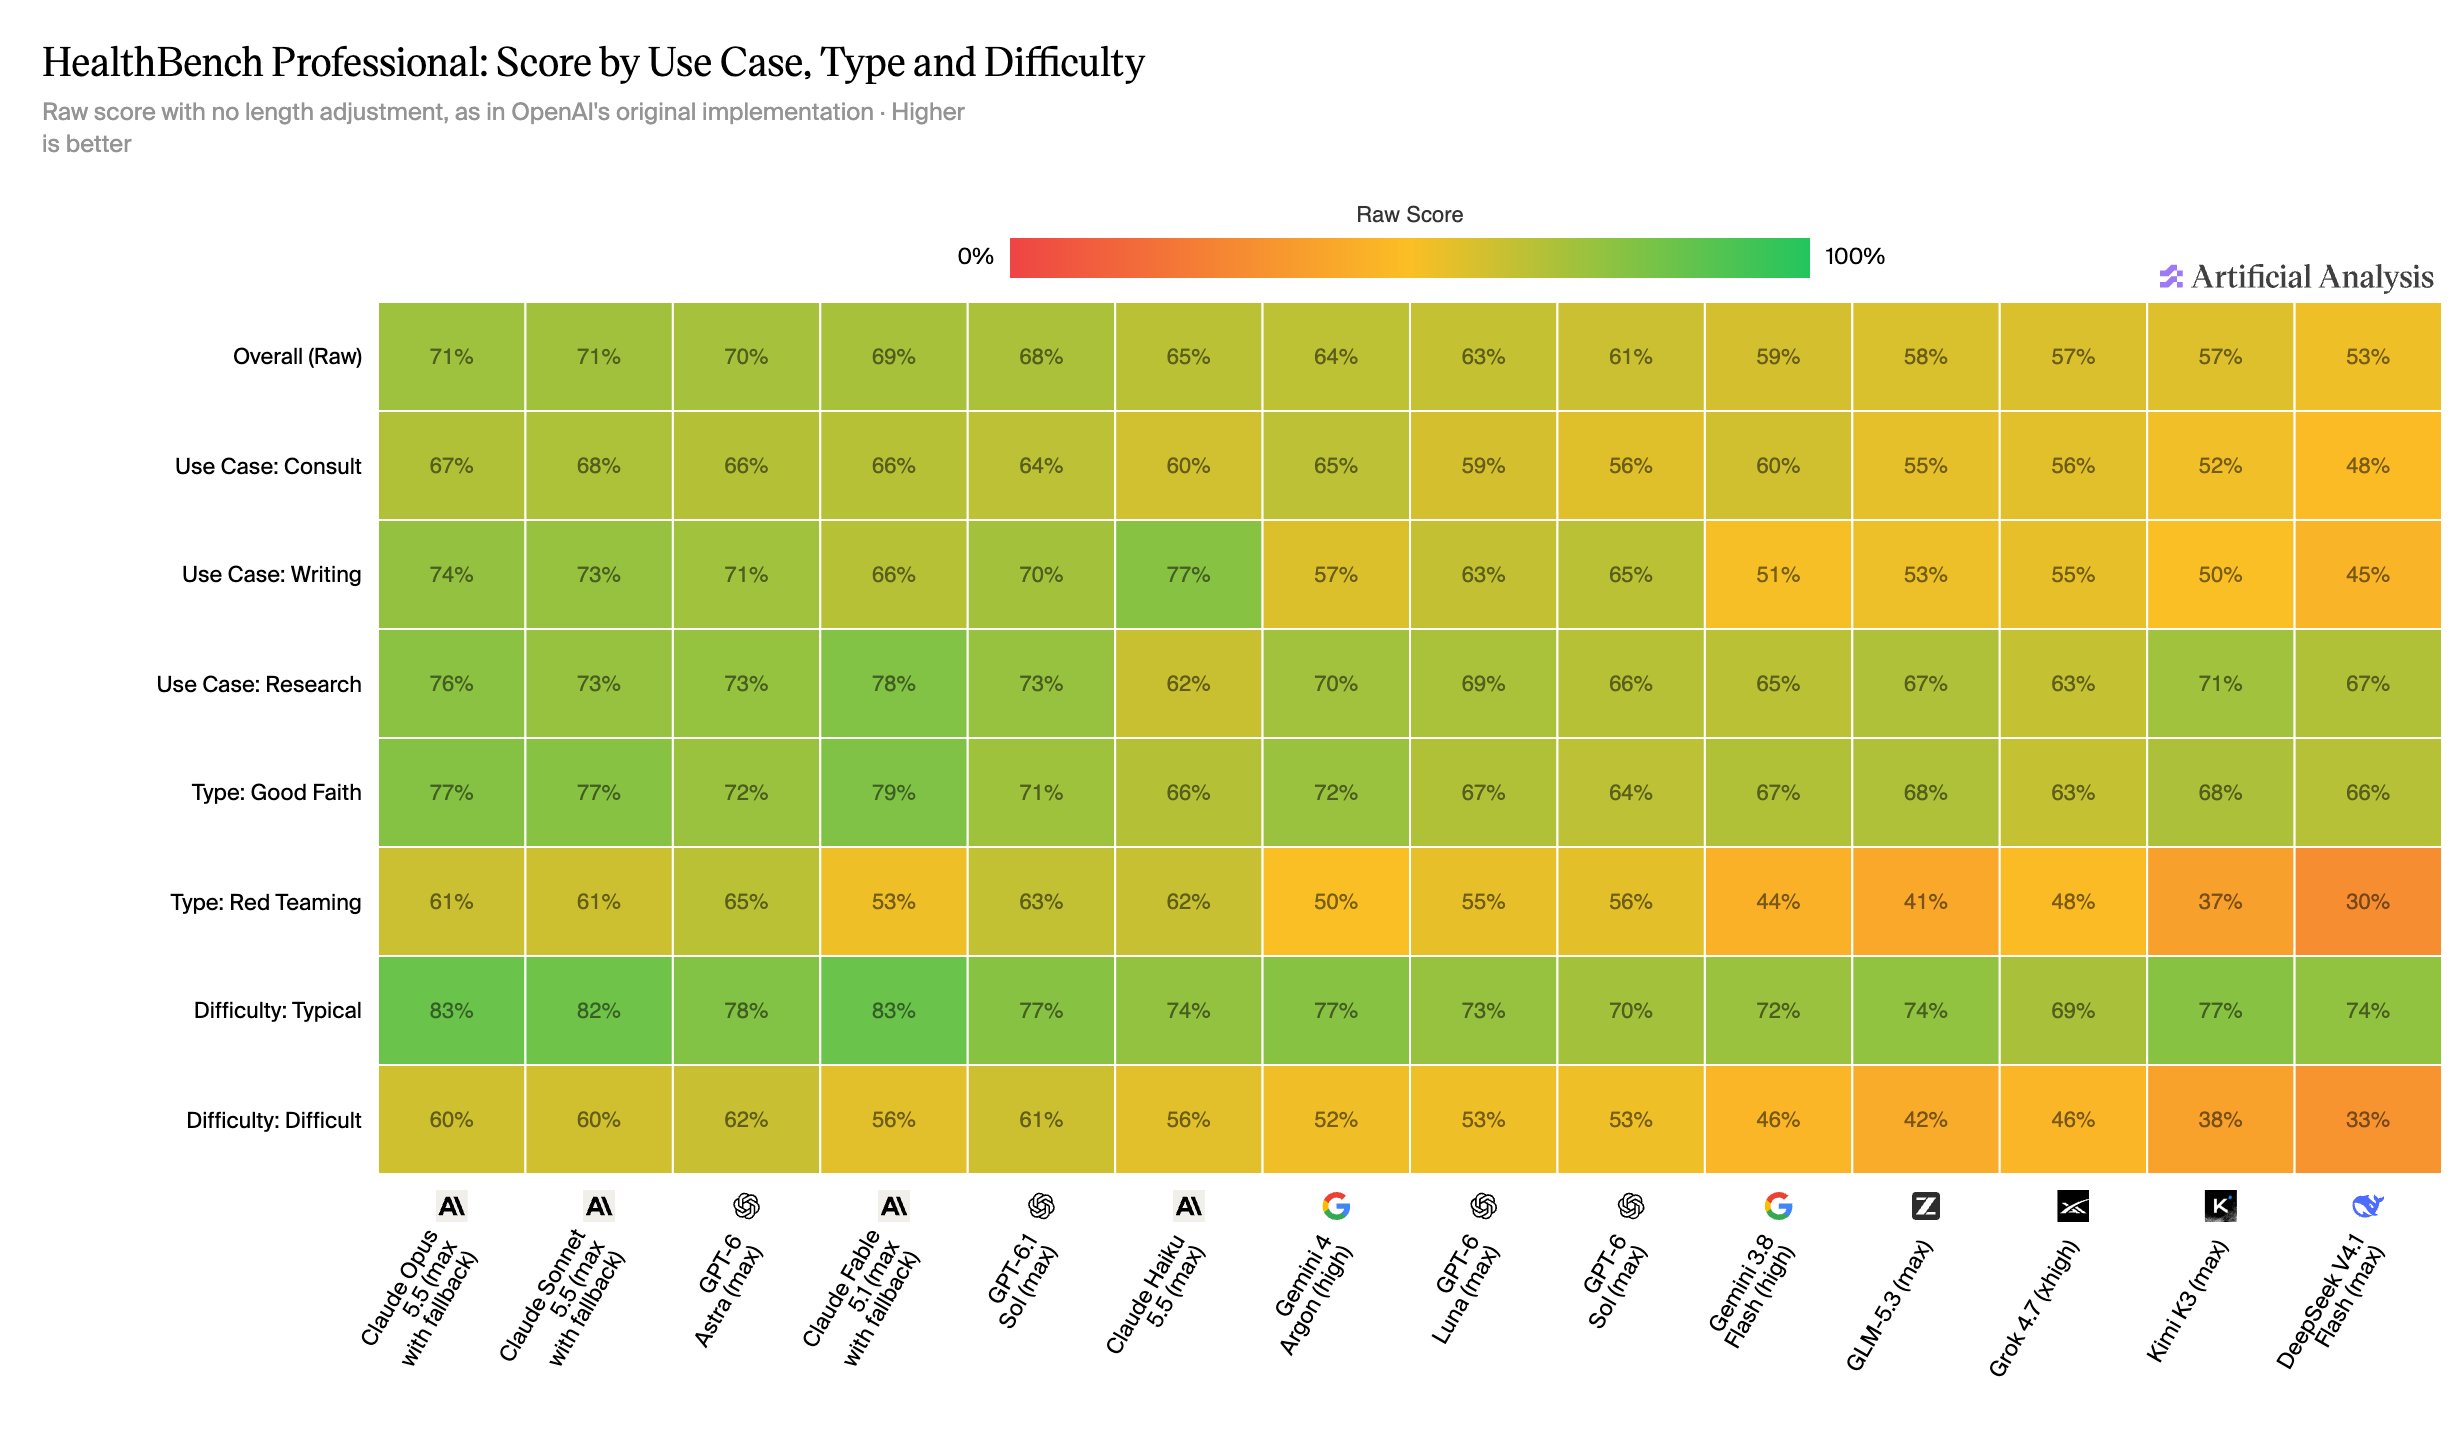
Artificial Analysis 数据显示,红队对话原始得分从 DeepSeek V4.1 Flash (max) 的 30% 到 GPT-6 Astra (max) 的 65%,善意对话则为 63%–79%。
On HealthBench Professional, raw scores on red teaming conversations range from 30% (DeepSeek V4.1 Flash (max)) to 65% (GPT-6 Astra (max)), compared with 63% to 79% on good faith conversations. Claude Fable 5.1 (max with fallback) scores highest on good faith conversations (79%) but 53% on red teaming. Claude Haiku 5.5 (max) scores highest on writing tasks (77%)
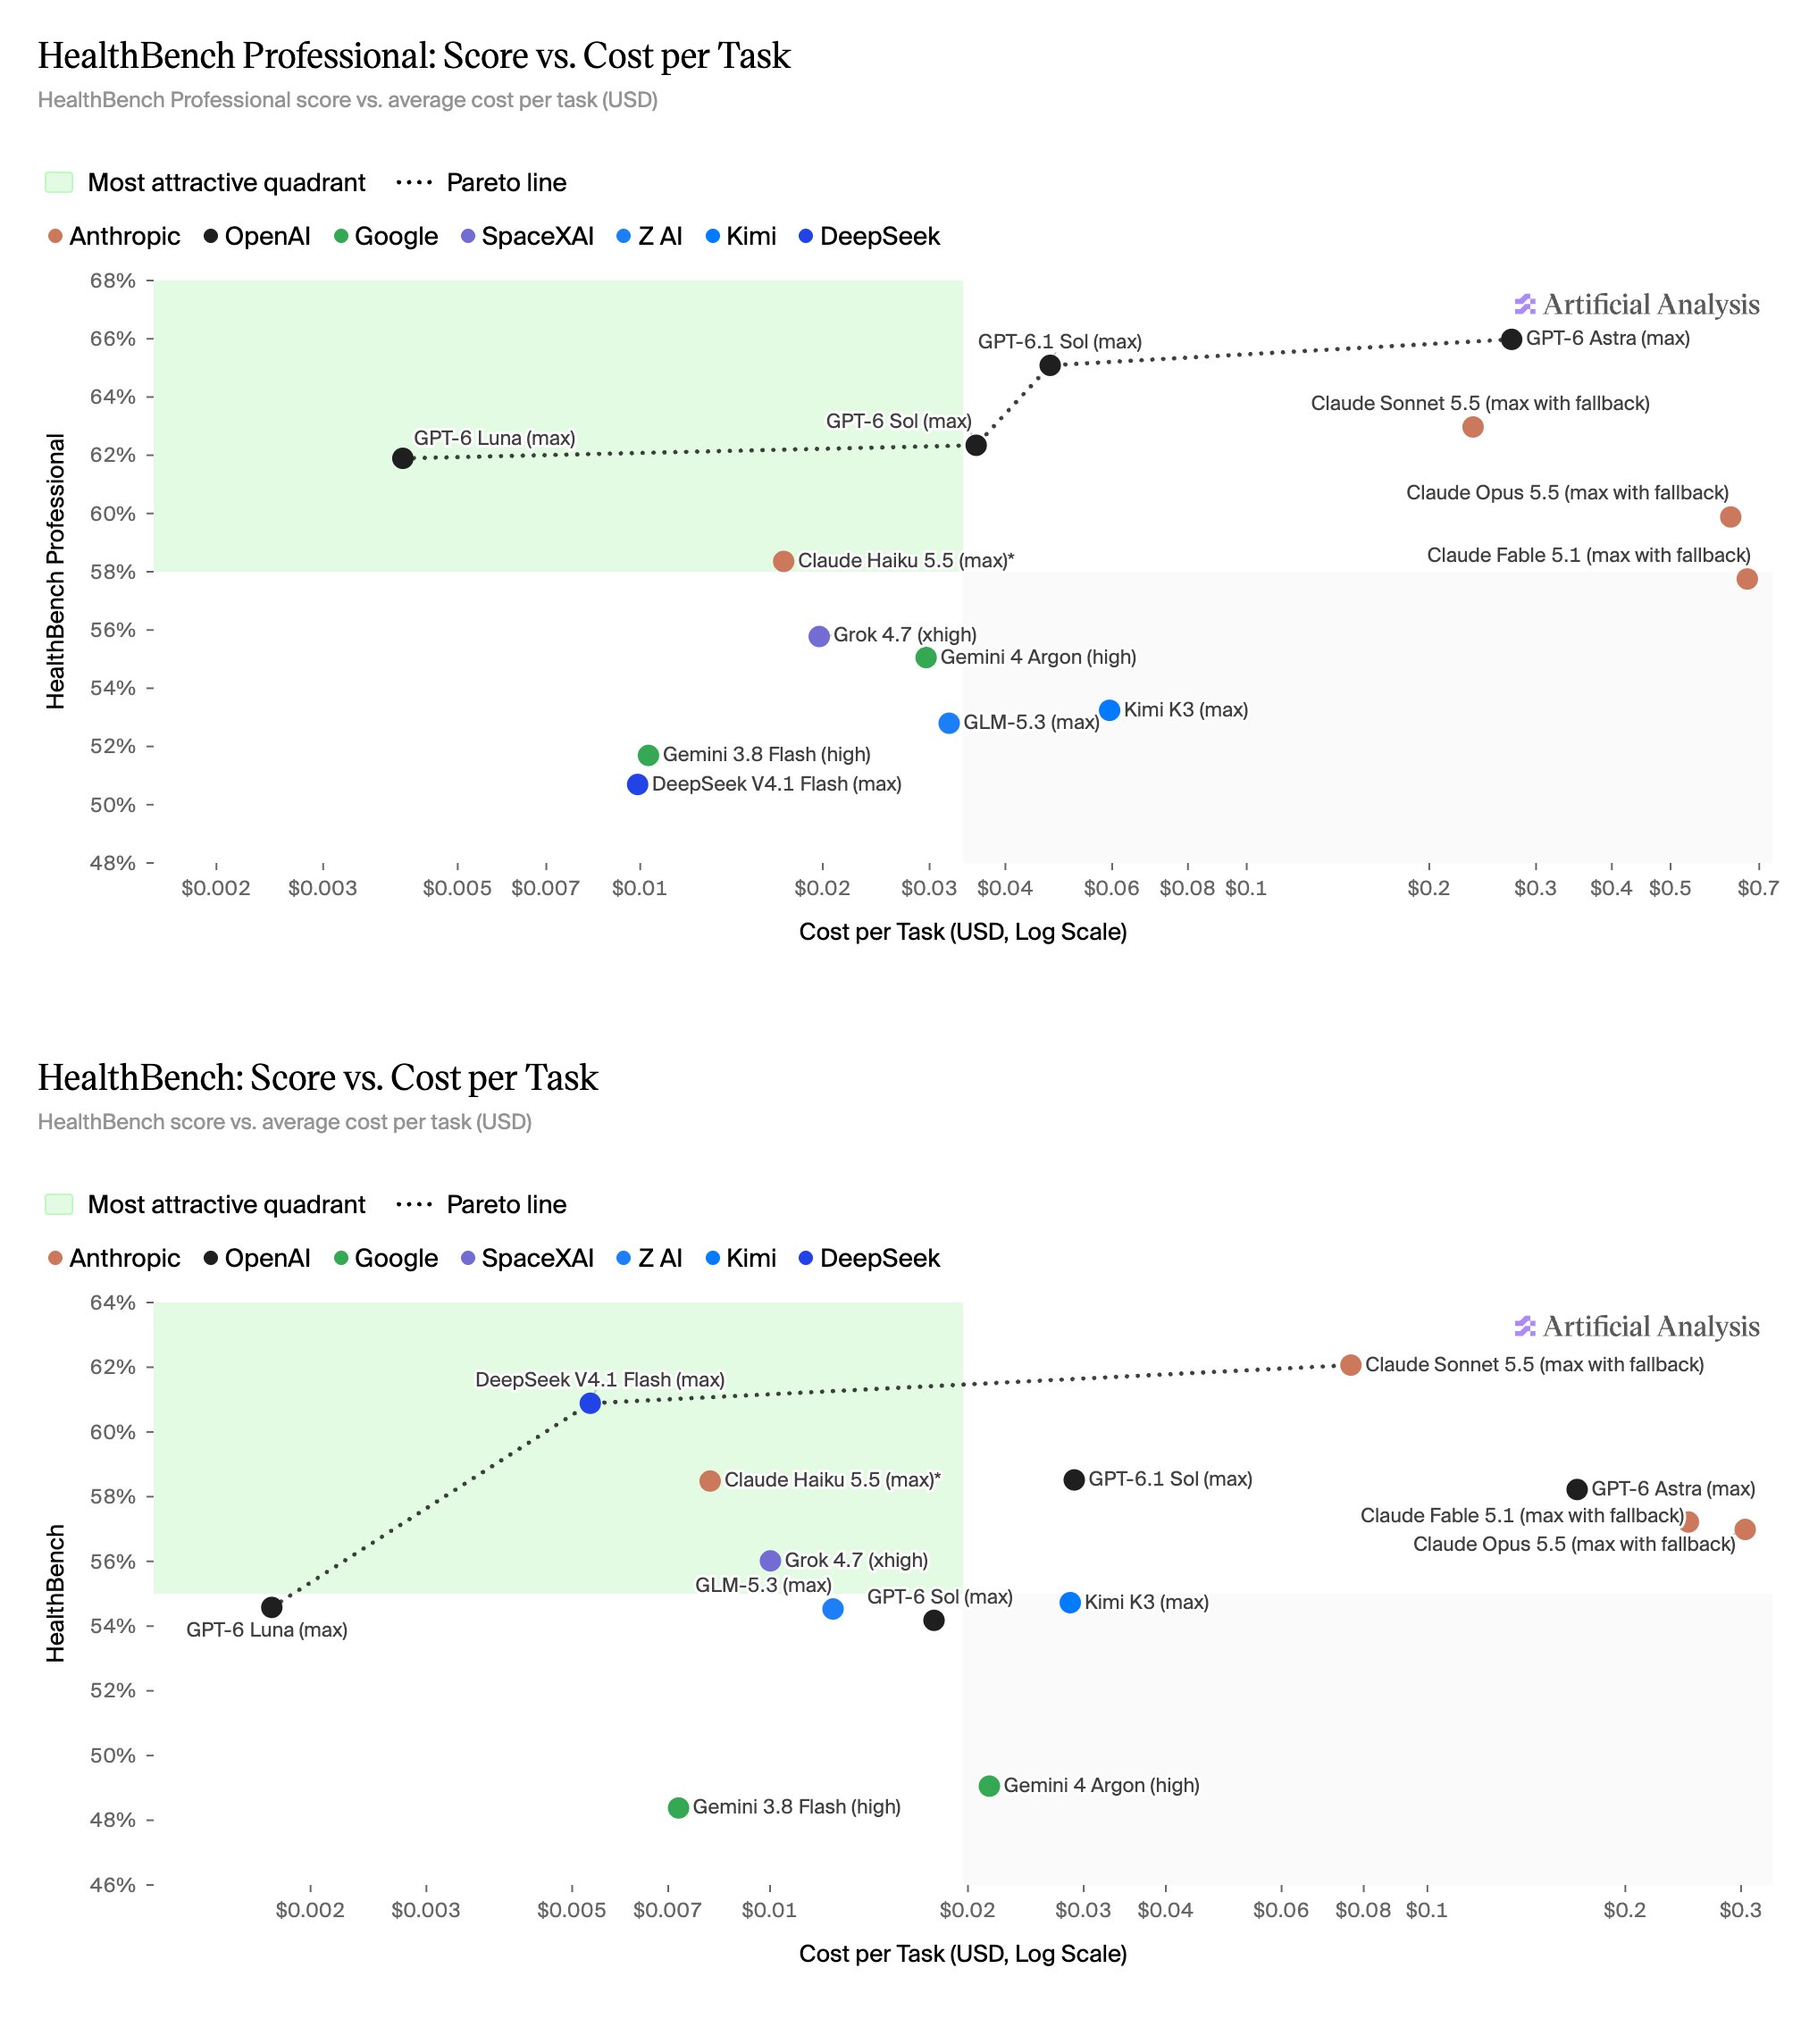
OpenAI models make up the entire HealthBench Professional score vs. Cost per Task Pareto frontier. GPT-6 Luna (max) scores 61.9% at $0.004 per task, 4 points below GPT-6 Astra (max) at under 2% of the cost ($0.27). On HealthBench, GPT-6 Luna (max, $0.002), DeepSeek V4.1 Flash (max, $0.005) and Claude Sonnet 5.5 (max with fallback, $0.08) form the frontier