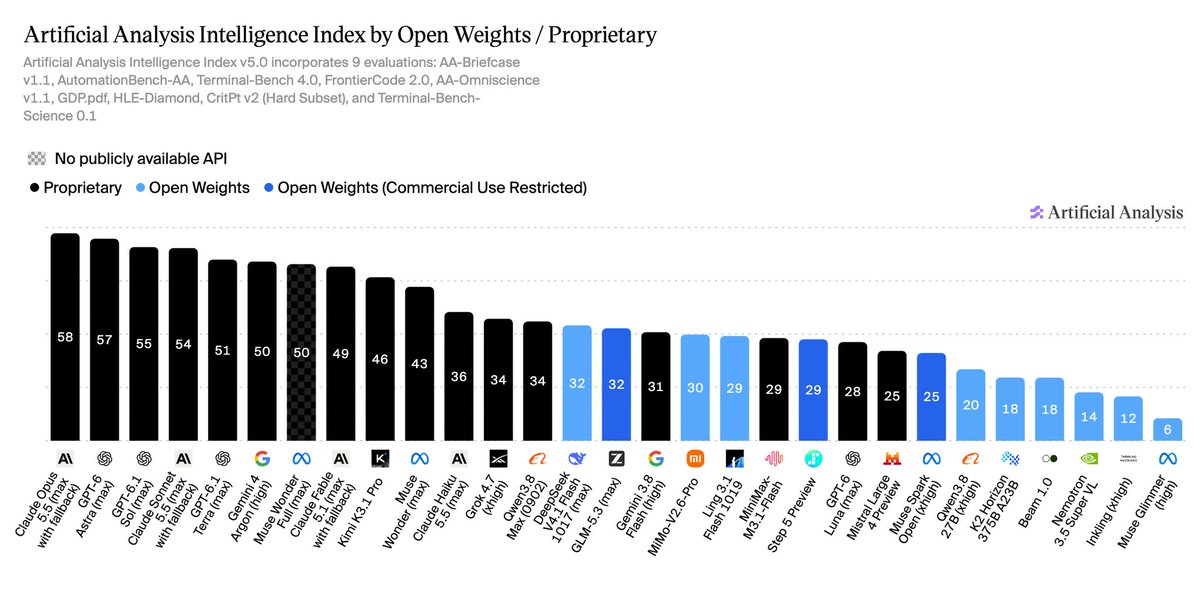
开源权重榜:V4.1 Flash 与 GLM-5.3 并列 32 分
Artificial Analysis v5 榜单显示开源权重模型落后扩大:已开源模型中 DeepSeek V4.1 Flash 1017 (max) 与 GLM-5.3 (max) 以 32 分并列最高,仍低于 Claude Haiku 5.5。
Open weights models fall further behind in v5. The leader, Kimi K3.1 Pro (weights not yet released), scores 46, 12 points behind the leader, compared with a 3-point gap in v4.3. Of models with released weights, DeepSeek V4.1 Flash 1017 (max) and GLM-5.3 (max) score highest at 32, and Claude Haiku 5.5 (max) outscores all of them. The gap is widest on HLE-Diamond and Terminal-Bench-Science, where Kimi K3.1 Pro scores 37% and 34%, compared with 68% for Claude Opus 5.5 (max) and 63% for GPT-6 Astra (max).
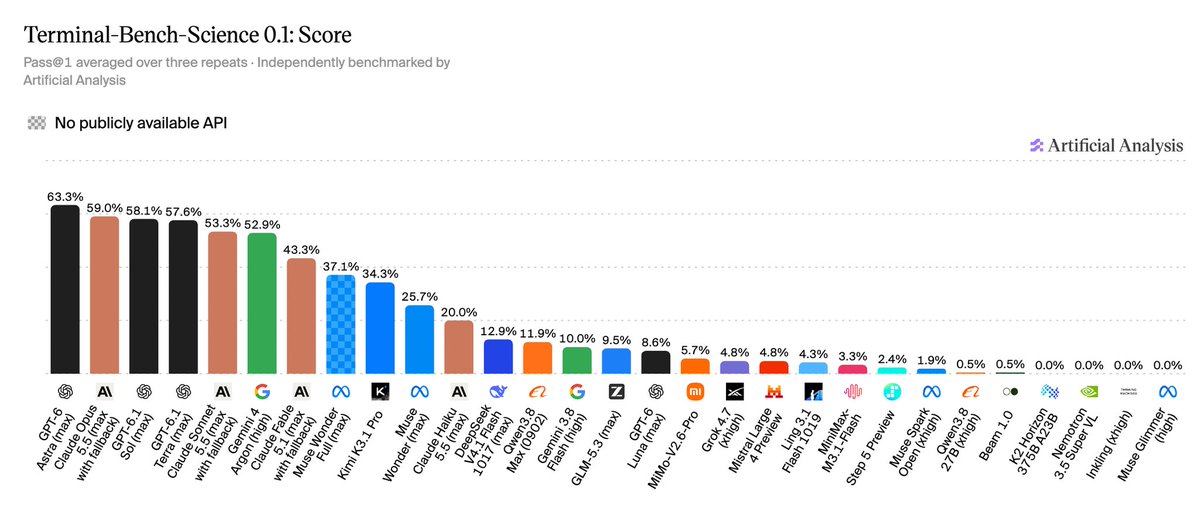
Terminal-Bench-Science tests whether agents can carry out scientific research workflows in a terminal. Experts curate and review each task, and a task passes only if every one of its tests passes. GPT-6 Astra (max) leads at 63%, followed by Claude Opus 5.5 (max) at 59% and GPT-6.1 Sol (max) at 58%. Scores drop off sharply below the leaders: the best open weights model, Kimi K3.1 Pro (weights not yet released), scores 34%, and Claude Haiku 5.5 (max) scores 20%. The best open weights model with released weights, DeepSeek V4.1 Flash 1017 (max), scores 13%, and most open weights models we benchmarked score under 10%.
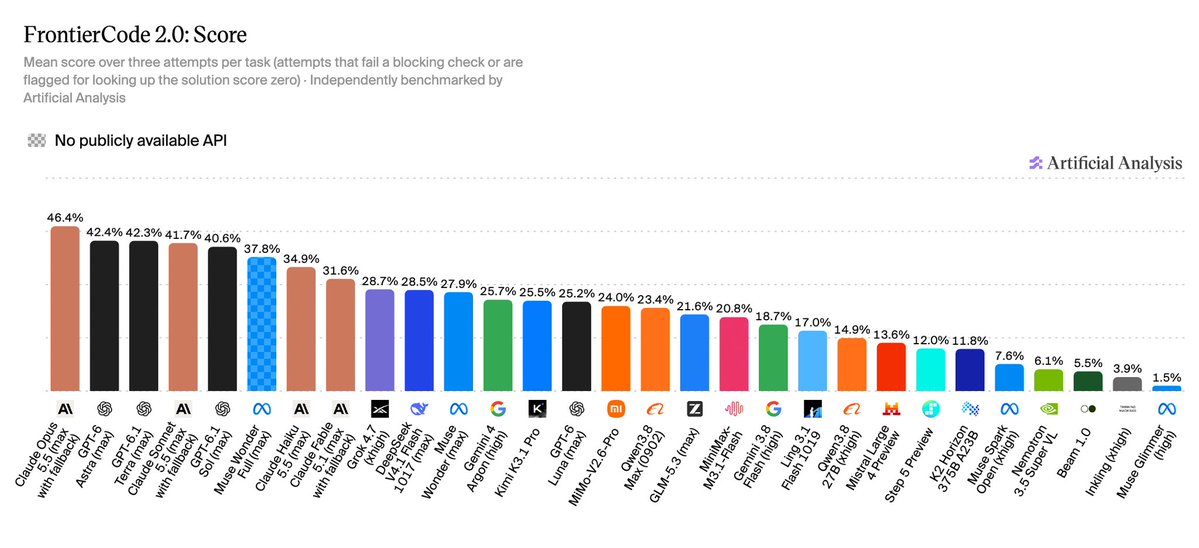
FrontierCode 2.0 is the latest update of @cognition's private coding benchmark. Launched earlier today, it comprises 132 tasks in real open-source repositories, graded on whether a maintainer would merge the agent's change. An attempt that fails any blocking check scores 0, and the tasks stay private to avoid contamination. We run every task three times in Stirrup, our agentic harness. Claude Opus 5.5 (max) leads at 46%, followed by GPT-6 Astra (max), GPT-6.1 Terra (max) and Claude Sonnet 5.5 (max), all at 42%. DeepSeek V4.1 Flash 1017 (max) is the highest-scoring open weights model at 28%, 18 points behind the leader.