CMP 170HX 上 V4.1 Flash 1017 内核优化:代码 +16%、散文 +23%
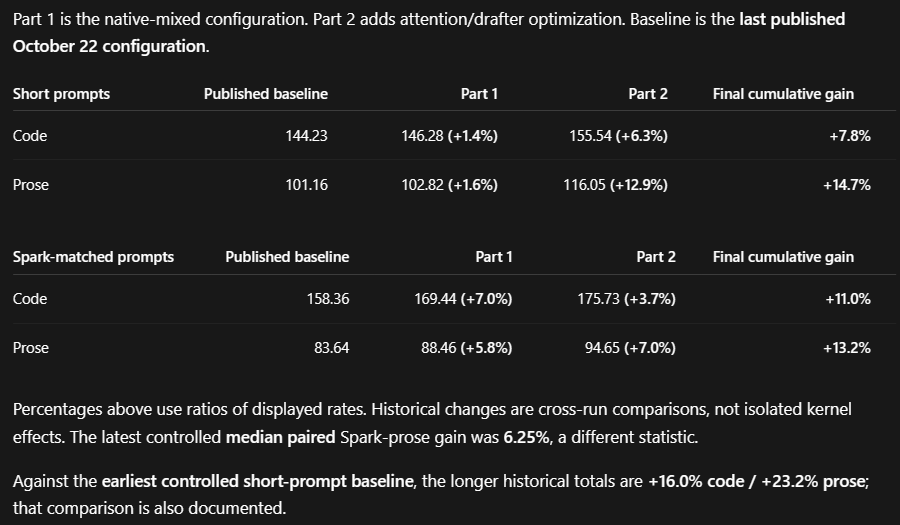
作者在 4 张 CMP 170HX 上为新 attention 与 drafter 做内核优化,代码约提速 16%、散文约 23%,另有约 9% 的 bit-exact 累积改进,附基准仓库。
New DeepSeek v4.1 1017 Flash 4x CMP 170HX Optimizations Real-world optimizations - Optimizations proven on prose, code, and real-world agentic Hermes at kernel level. New bit-exact kernel improvements stack on my previous work: ~9% cumulative from baseline, 2% latest New attention + drafter ~16% code and 23% prose - Not bit-exact but passed extensive A/B testing. Warrants additional quality confirmation and testing from community. Additionally, we don't claim a gain in concurrency needs additional testing. Apply partial or both. My machine is slower Broadwell: so will not match EPYC topline numbers but optimizations should transfer to other builds. Do take what works but give proper credit. benchmarks and results 1017 https://github.com/CurtisAccelerate/DeepSeekv41-Flash-1017-EXL3-CMP170HX/blob/b02da8c46f0c4ba702284fe4f07afa29b6411304/benchmarks/2026-10-25/README.md base repo with kernel source and feature flags https://github.com/CurtisAccelerate/DeepSeekv41-Flash-EXL3-TC-MoE/tree/8a59fd5a0bfbe61c43e24b01737adff18e0025d9/experiments/ds1017-native-mixed-and-split
my bad, these are the better links to lead with: https://github.com/CurtisAccelerate/DeepSeekv41-Flash-EXL3-TC-MoE https://github.com/CurtisAccelerate/DeepSeekv41-Flash-1017-EXL3-CMP170HX/tree/main/benchmarks/2026-10-25