KernelBench 实测:Opus 5.5 领先,Astra 第二
性能工程师在 KernelBench-Mega 上实测,Opus 5.5 达 35.5 倍加速,GPT-6 Astra 以 24.8 倍排第二。
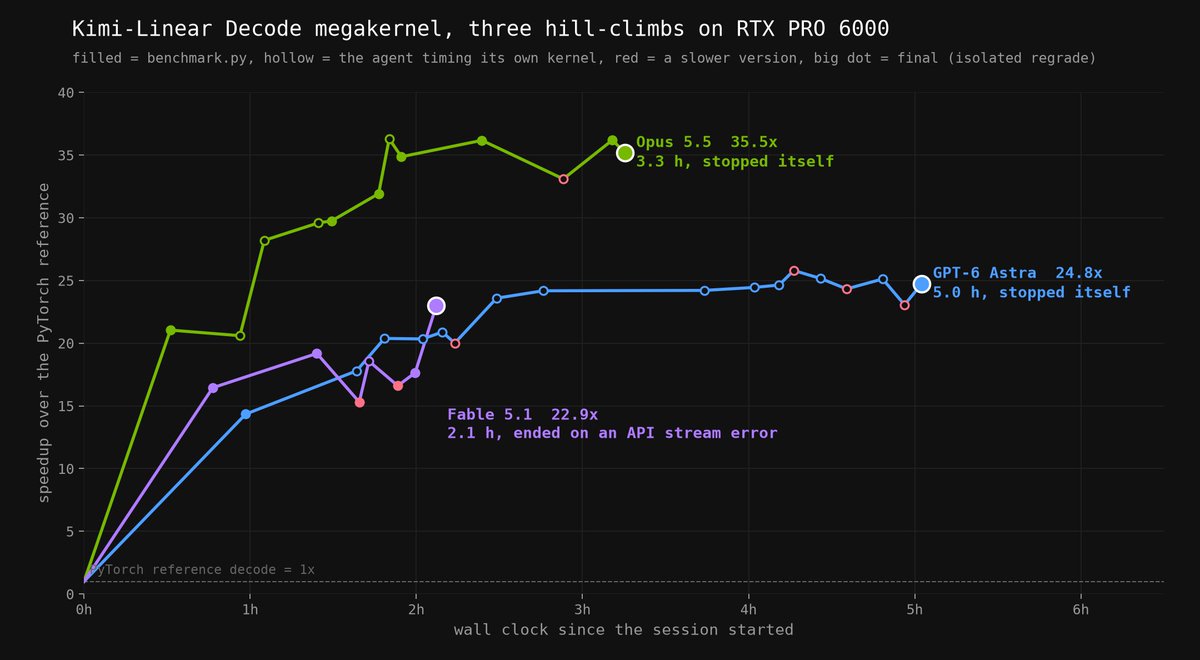
Claude Opus 5.5 [xhigh] on KernelBench-Mega: It made a Kimi-Linear Decode megakernel for RTX PRO 6000 at 35.5x the optimized PyTorch baseline! (the 2nd best was GPT-6 Astra at 24.8x) A few words from me (performance engineer): Before we get into the weeds here on how it hillclimbed, its clear to me this is a massive jump over fable and maybe astra too. They supposedly "nerfed" it on kernels but I suspect just TPU and/or Trainium rather than CUDA. The writing style increases my productivity a ton as I don't need that many seconds to understand the blocker or status its facing (im running 20 of these in parallel btw so human attention is scarce). It also takes agency rather than waiting for me. I think this is because at some deep level with mech interp/finetuning, they cracked how to understand the users intent so deeply that its fine executing on the task that the user would say "go" constantly. This means YOU can parallelize more as well. Oh also its cheap and fast and thats just great. S+ tier release imo. --- The climbs look different from the start. Opus 5.5's first working megakernel was already 21x at 31 minutes. Astra's first was 14x at one hour, and it spent the next four hours inching from 24 to 25. Fable 5.1 got to 23x in two hours before the session died on an API error. One session each on my RTX PRO 6000 rig, unlimited budget. The numbers are isolated regrades after a jsonl trace-level and submission-level reward-hack audit.