四台 DGX Spark 上六套 V4.1 Flash 部署方案横评:质量持平,差别在速度与并发
同一套四台 DGX Spark 上跑六个社区部署配方:六者都通过 75 项 qeval 中的 71 项、都能在 100 万 token 提示里找出全部暗语;单用户最快 77 tok/s,单用户编程最快 134 tok/s,vLLM 原权重可撑 32 并发、16 用户时 288 tok/s,SGLang 读 100 万
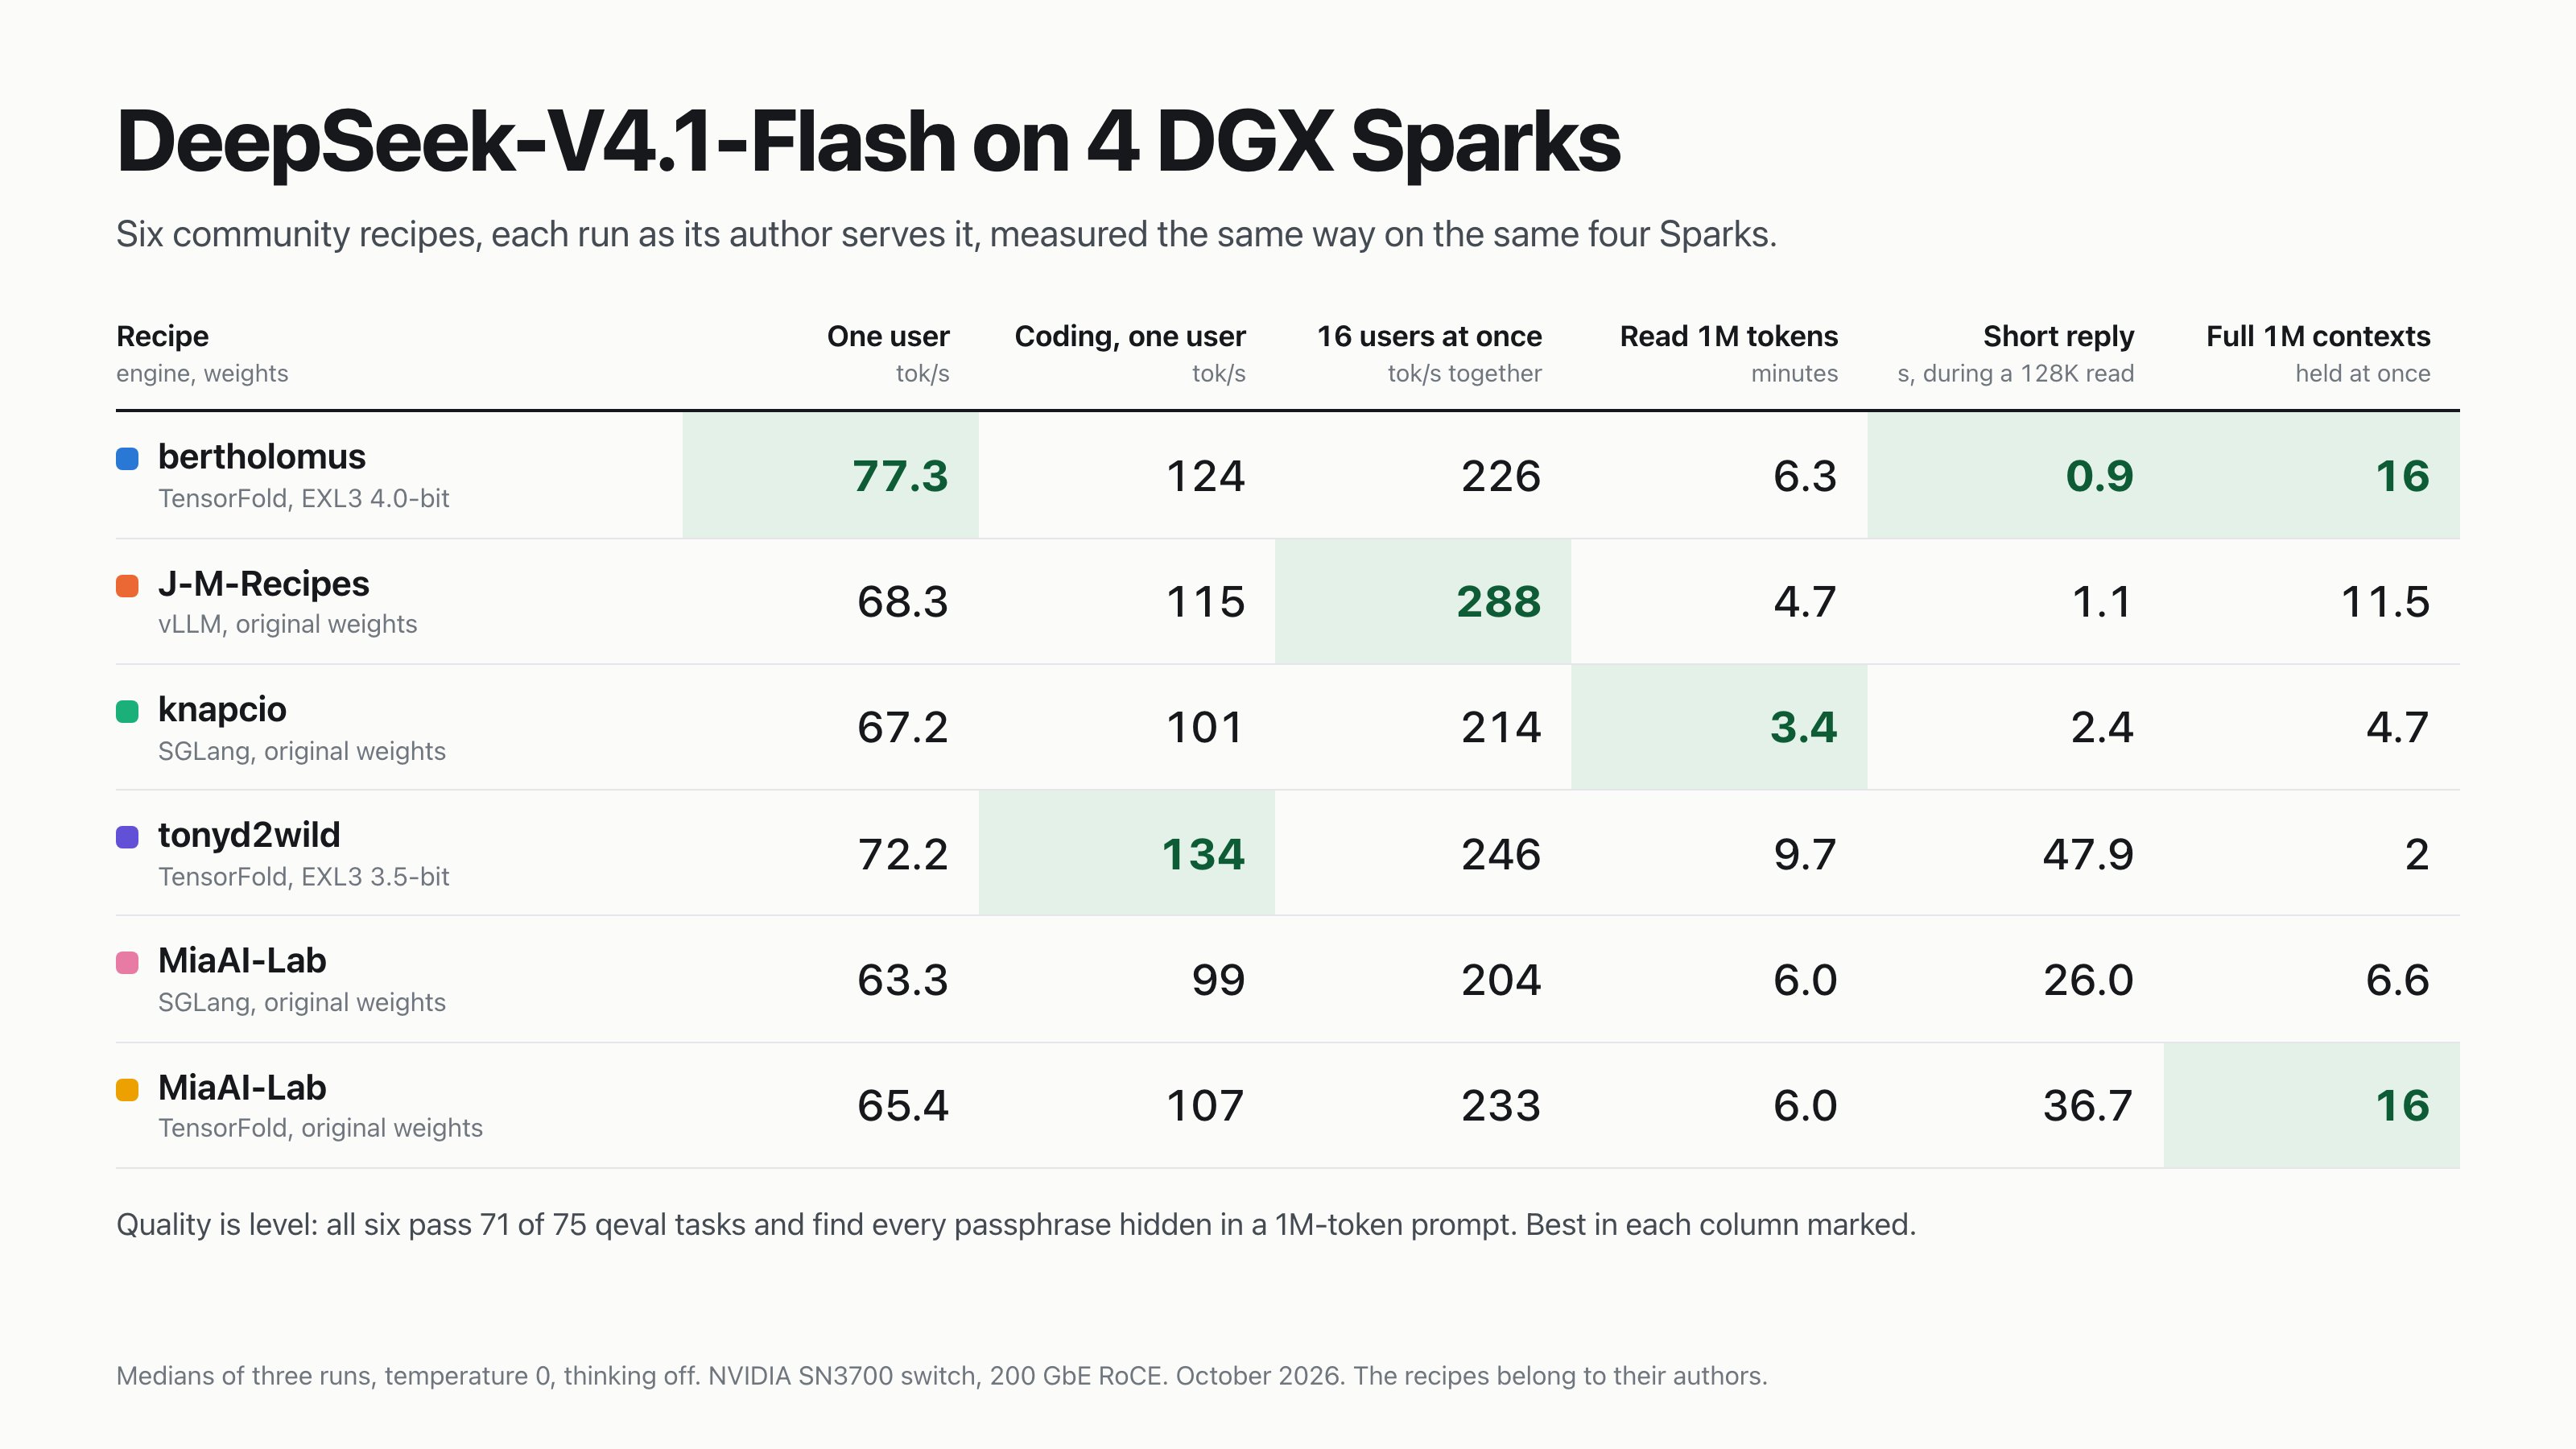
What’s the best way to run DeepSeek-V4.1-Flash on 4 DGX Sparks? As I see it, there isn’t one answer. It depends on what you need. One fast user/agent, or many at once? Huge documents? Long agentic sessions? Original weights, or compressed? We needed these answers to figure out the optimal stacks for our CVE pipelines. So we took six community recipes, ran each exactly as its author serves it on the same four Sparks, and measured them all the same way, to see what each one is best at. Quality first: on our tests it’s level. All six pass 71 of 75 qeval tasks and find every passphrase hidden in a 1M-token prompt, compressed weights included. So the choice comes down to how you use it: @bertholomusai (TensorFold, 4-bit EXL3): the fastest single user (77 tok/s), the quickest reply while someone else’s long prompt is being read (0.9 s), and 16 full 1M-token sessions at once. @Tech2Wild (TensorFold, 3.5-bit EXL3): the fastest coding for one user (134 tok/s), and the most memory left free on each node. J-M-Recipes, @JamesMeadlock (vLLM on @christopherowen’s fork, original weights): the most users at once (32 seats, 288 tok/s with 16 users), quick replies during long reads (1.1 s), and 11.5 full 1M sessions. In our long-session agent tests it started the next turn fastest. @majewskizby (SGLang, original weights): the fastest at reading huge documents, 1M tokens in 3.4 minutes. @MiaAI_lab (TensorFold, original weights): 16 full 1M sessions at once on the original weights. @MiaAI_lab (SGLang, original weights): the production line @majewskizby’s profile builds on. Medians of three runs, temperature 0, thinking off, on an NVIDIA SN3700 switch. All credit to the authors: these are their recipes, we only ran and measured them. Kudos for publishing them openly, with every setting, patch and number needed to reproduce them, and for the speed you ship at. Fun note: several of these releases are days old. You also share fixes with each other: tonyd2wild’s RDMA patch is what got bertholomus’s engine running on our network, and @majewskizby’s MTU fix landed in Mia’s recipe this morning. You’ve made a model this size practical to run on four desktop boxes, and our CVE work now runs on it - thank you!