M3 Ultra 本地跑 DeepSeek V4.1 Flash 1017:双机 prefill 最高 1193 t/s
ivanfioravanti 在 M3 Ultra 上优化 ds4 推理:Q4 双机 prefill 达 920–1193 t/s,decode 48.5 t/s;与官方 API 84 例 logprobs 对比误差在噪声内。
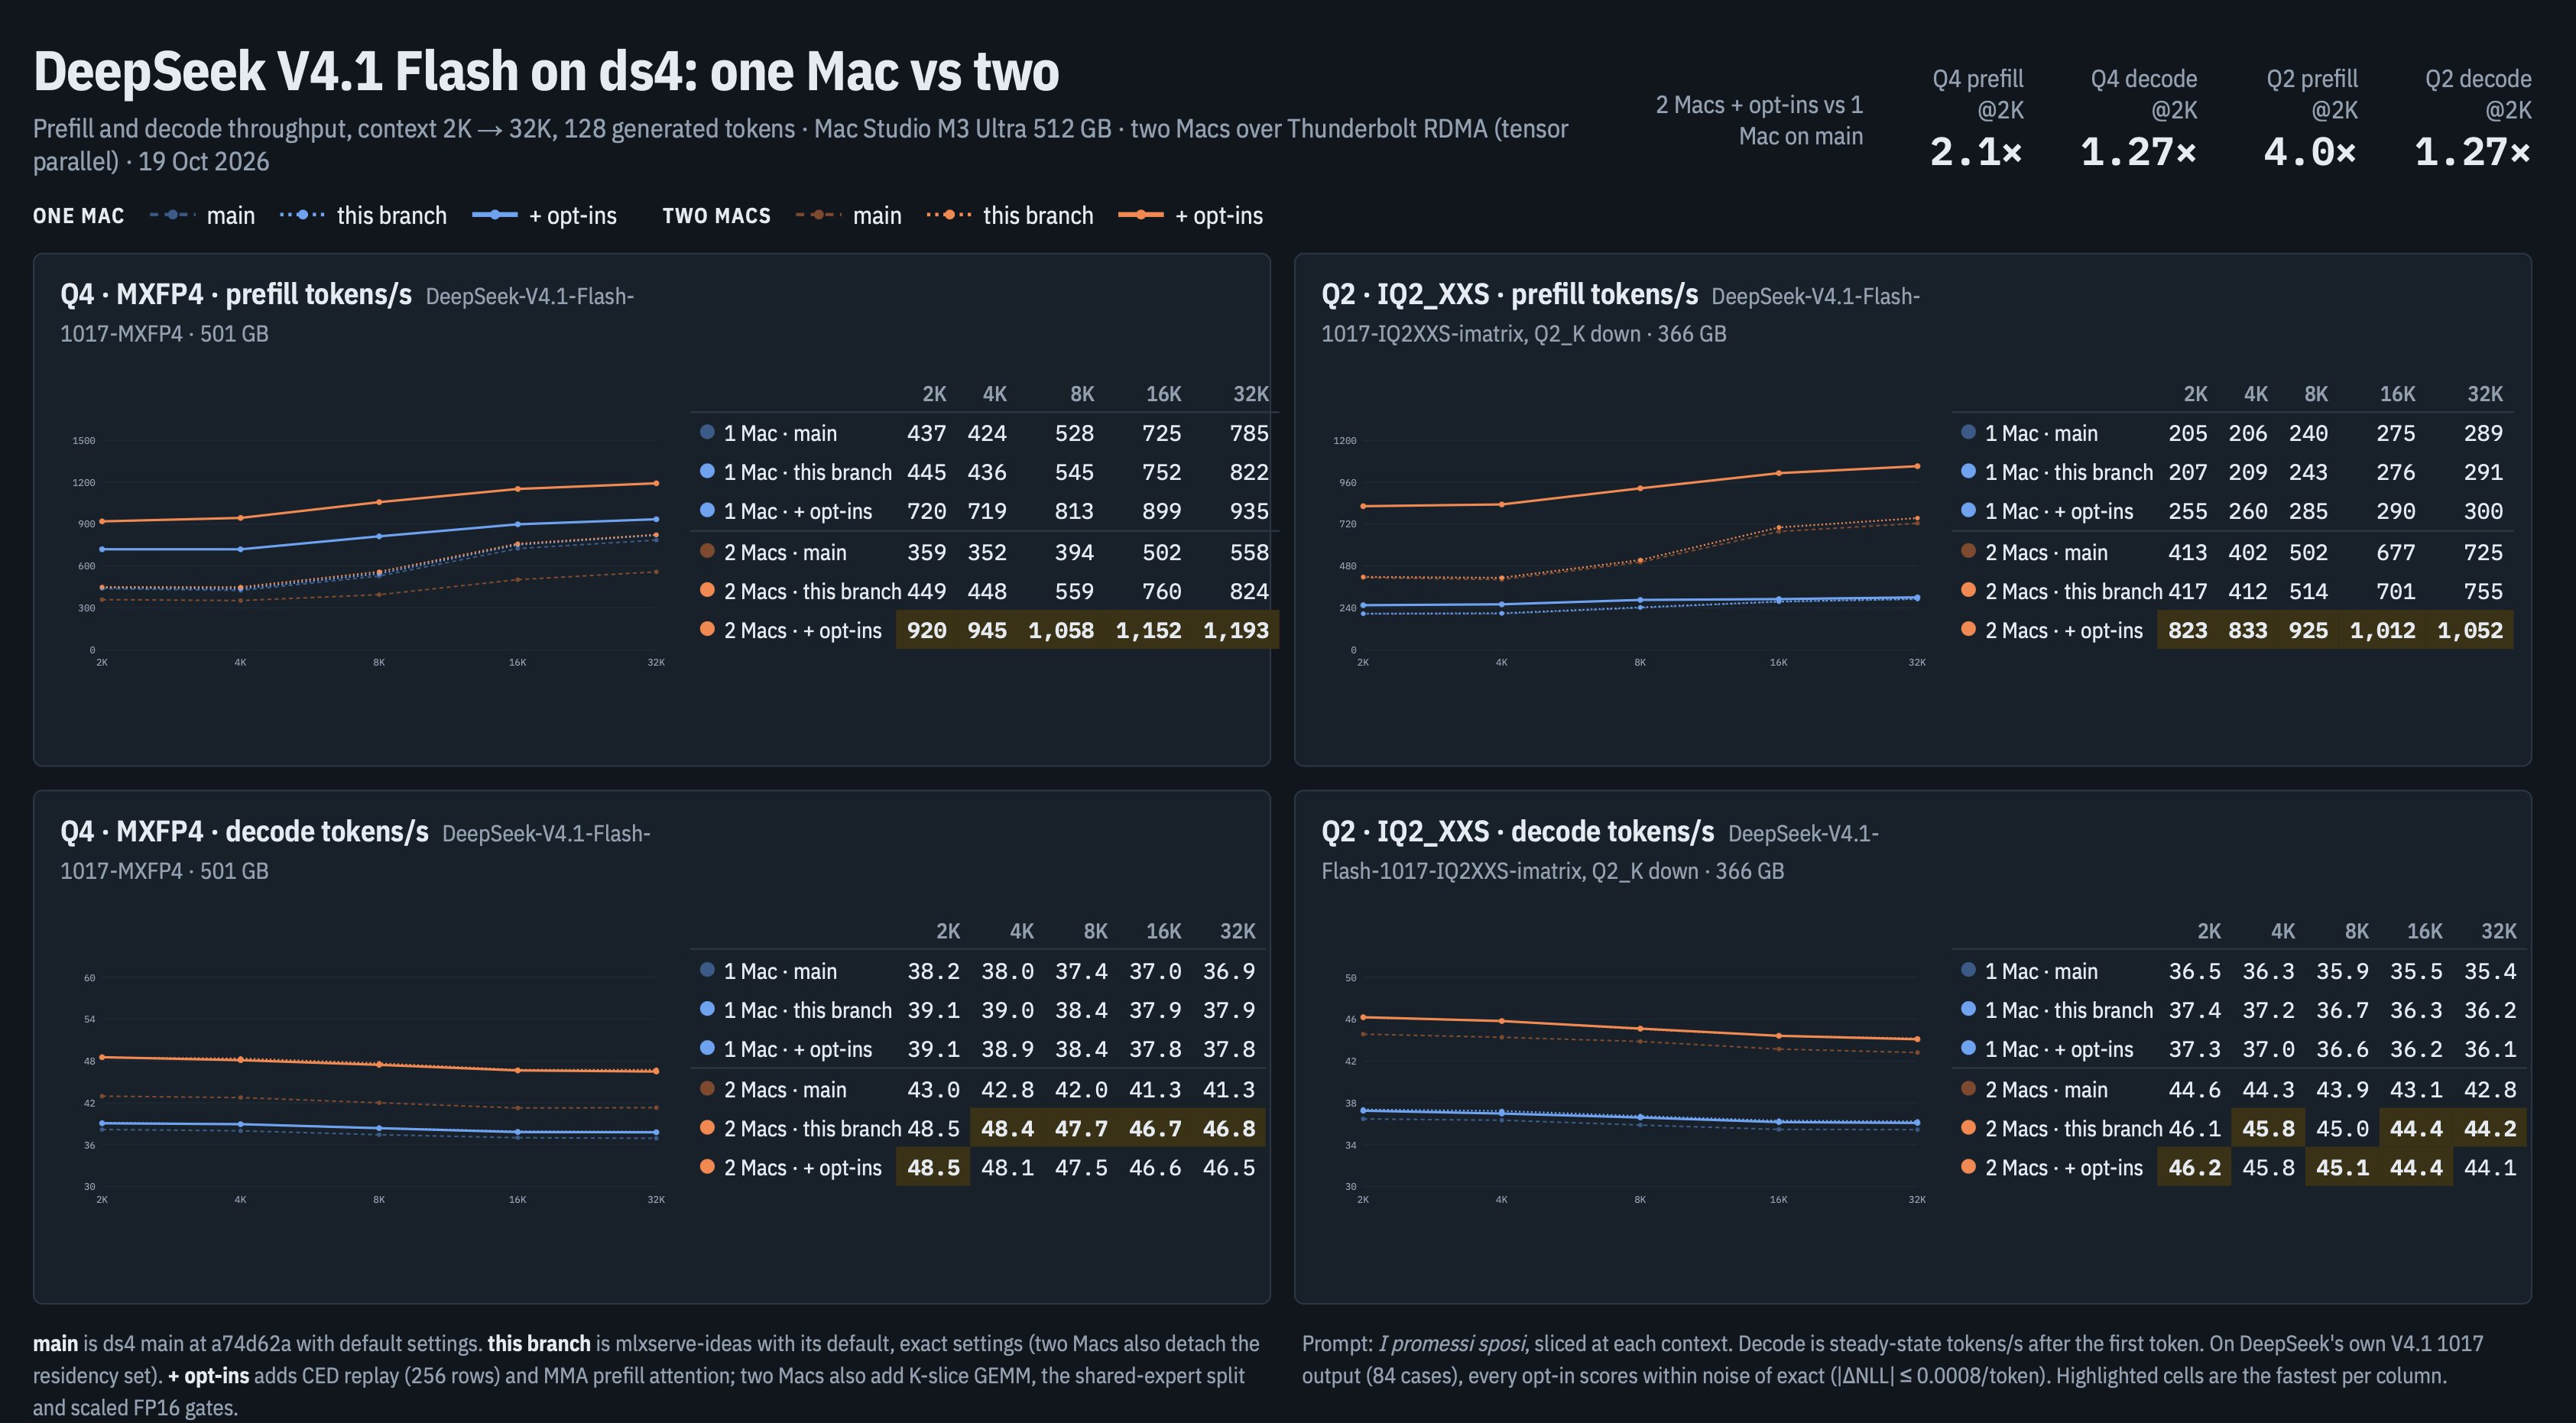
DeepSeek V4.1 Flash 1017 on M3 Ultra: new ds4 optimization round 🚀 Enough for today. Q4 (MXFP4) Prefill, 2K → 32K: • 1 Mac: 437-785 → 720-935 t/s • 2 Macs: 359-558 → 920-1,193 t/s (up to 2.6×) Decode 2K: • 1 Mac: 38.2 → 39.1 t/s • 2 Macs: 43.0 → 48.5 t/s (+13%) Q2 (IQ2_XXS) Prefill, 2K → 32K: • 1 Mac: 205-289 → 255-300 t/s • 2 Macs: 413-725 → 823-1,052 t/s Decode 2K: • 1 Mac: 36.5 → 37.4 t/s • 2 Macs: 44.6 → 46.2 t/s The biggest prefill arefrom opt-ins: switches that trade exact bit-for-bit for speed, staying within measured noise: - SWA bounded replay (CED): for long prompts, the upper decoder layers recompute only the last 256 tokens instead of the whole prompt. It's the trick from DeepSeek's paper; the model was post-trained for it. Up to +70% on 2K appends. - MMA prefill attention: a matrix-unit attention kernel, about 30% faster attention. - Two-Mac prefill: sliced output projections run as real matmuls, the shared expert is split across both Macs, gate exchanges use scaled FP16 (half the bytes), and the Metal residency stalls are removed. Quality check: I compared against logprobs from DeepSeek's official V4.1 1017 API (84 cases). Every opt-in is within noise of exact (ΔNLL ≈ ±0.001/token), and the needle tests gave 24/24 identical answers. Next: Q2 single-Mac prefill is much slower than it should be (its MoE prefill path); a fix is in progress. A PR to the @kernelpool fork is coming after that. Final PR to @antirez main repo from kernelpool one.