两份 DeepSeek V4.1 Flash 量化在双 DGX Spark 上对比:质量打平
作者与 Mia 各做一份 TP=2 DGX Spark 量化,同题 356 问得分 316 vs 320(88.8% vs 89.9%)属平手;解码约 86 tok/s,但显存差 3.2GB,KV 缓存 170K vs 2.1M。
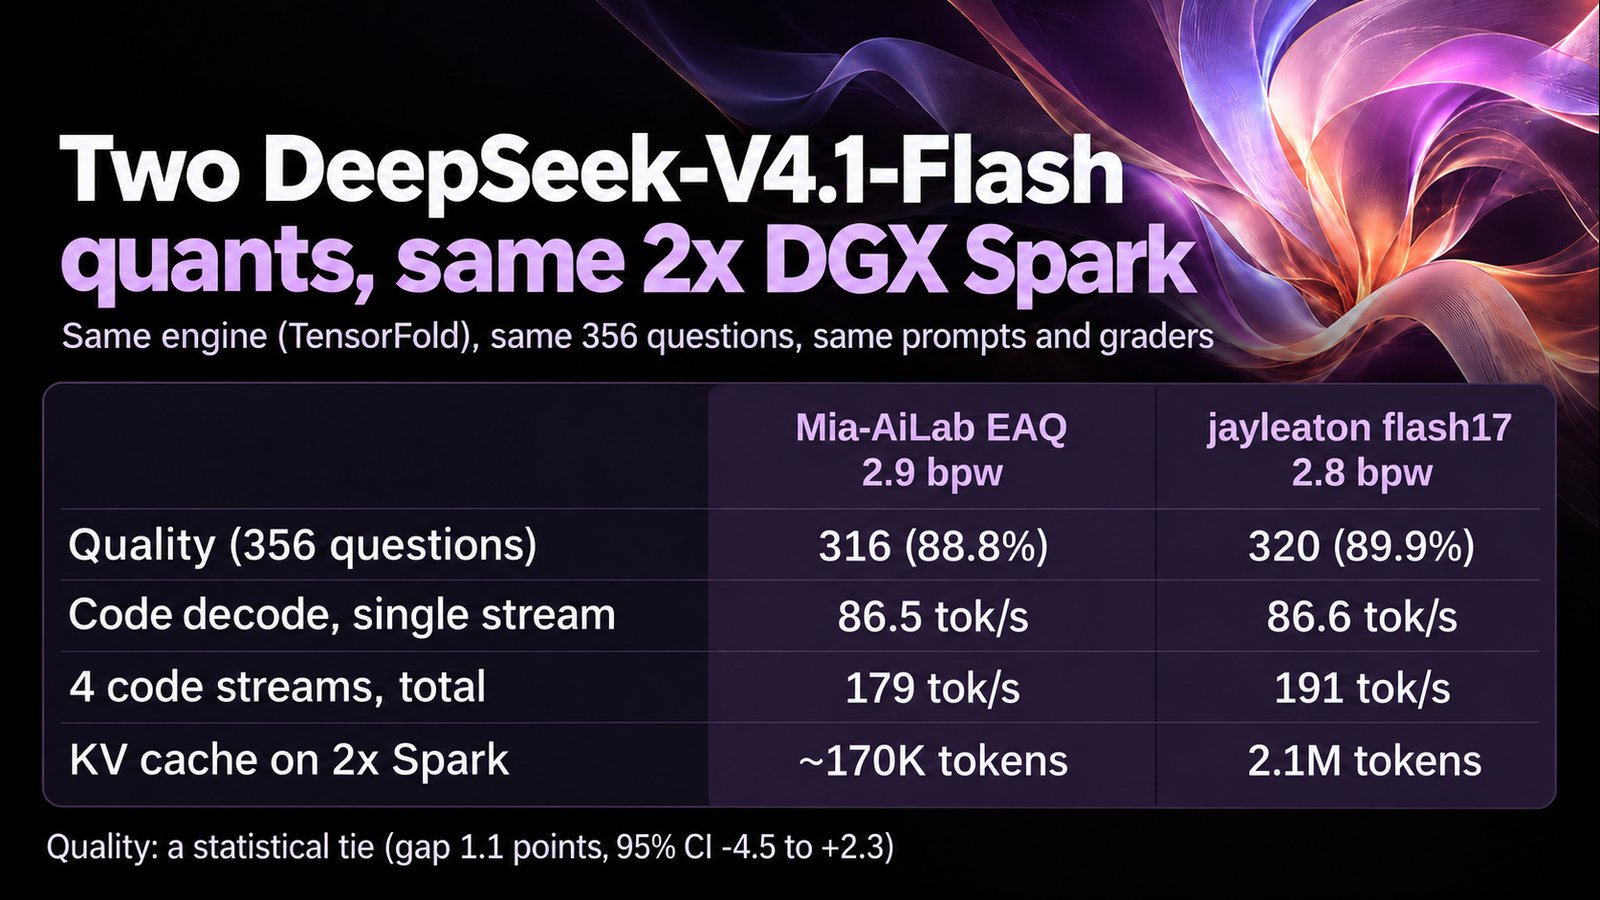
@MiaAI_lab and I both made DeepSeek-V4.1-Flash-1017 quants for TP=2 DGX Sparks, so I ran them side by side. TLDR: Both are really amazing! Here is the full story of where each shines. Her EAQ: 2.9 bpw, 210.6 GB. My flash17: 2.8 bpw, 203.8 GB Same TensorFold engine, same serving profile, same 356 questions with the same prompts and graders. Quality came out 316 vs 320 (88.8% vs 89.9%). The 95% CI on the gap is -4.5 to +2.3 points, so it's a tie. They're level on STEM, maths, multilingual maths and tool calls. Mine's a bit ahead on LiveCodeBench (14 vs 16 of 20) and got one more tool chain. Speed (Quant only, both in my recipe), Mia's / mine: code decode: 86.5 / 86.6 tok/s prose decode: 45.6 / 48.2 tok/s 32K-token prompt: 17.3 / 16.0 s 4 code streams: 179 / 191 tok/s total Memory is where they really differ. EAQ is about 3.2 GB bigger per Spark, so its KV cache fits ~170K tokens. flash17 fits 2.1M. Her pack is clean, standard EXL3. It ran on my engine after one tiny, exact dtype widening. The weights are MIT, and she's added TensorFold to her recipe as a second engine and credited me. Mia's speed results in her own recipe tell a different story, and her Quant in her recipe seems to be 10% faster than mine. This tells us that there is more at play here. There are no shared, agreed benchmarks for speed in any of our tests. Both test on different metrics, so there is really no way to tell which is "faster" I'm adding EAQ to my recipe as an optional pack for those that want to use it, but it takes a small hit in performance. Ultimately, it will most likely come down to personal preference on which one you use. Mia's recipe/quant together or mine together. I would like to discuss setting better guidelines for measuring speeds across these recipes. Yes people can just focus on benchmaxxing, but it would lead to more consistent results. If you're on 2x Spark, which do you want: the extra cache or the extra 0.1 bpw?