DeepSeek 开源推理框架 DeepInfer,面向 V4.1 Flash 生产服务
含 FlashMLA、DeepGEMM、DeepEP 等自研 kernel,支持 DSpark 推测解码与批不变推理,跑在 SM100 GPU 和昇腾 950 上,Apache 2.0。
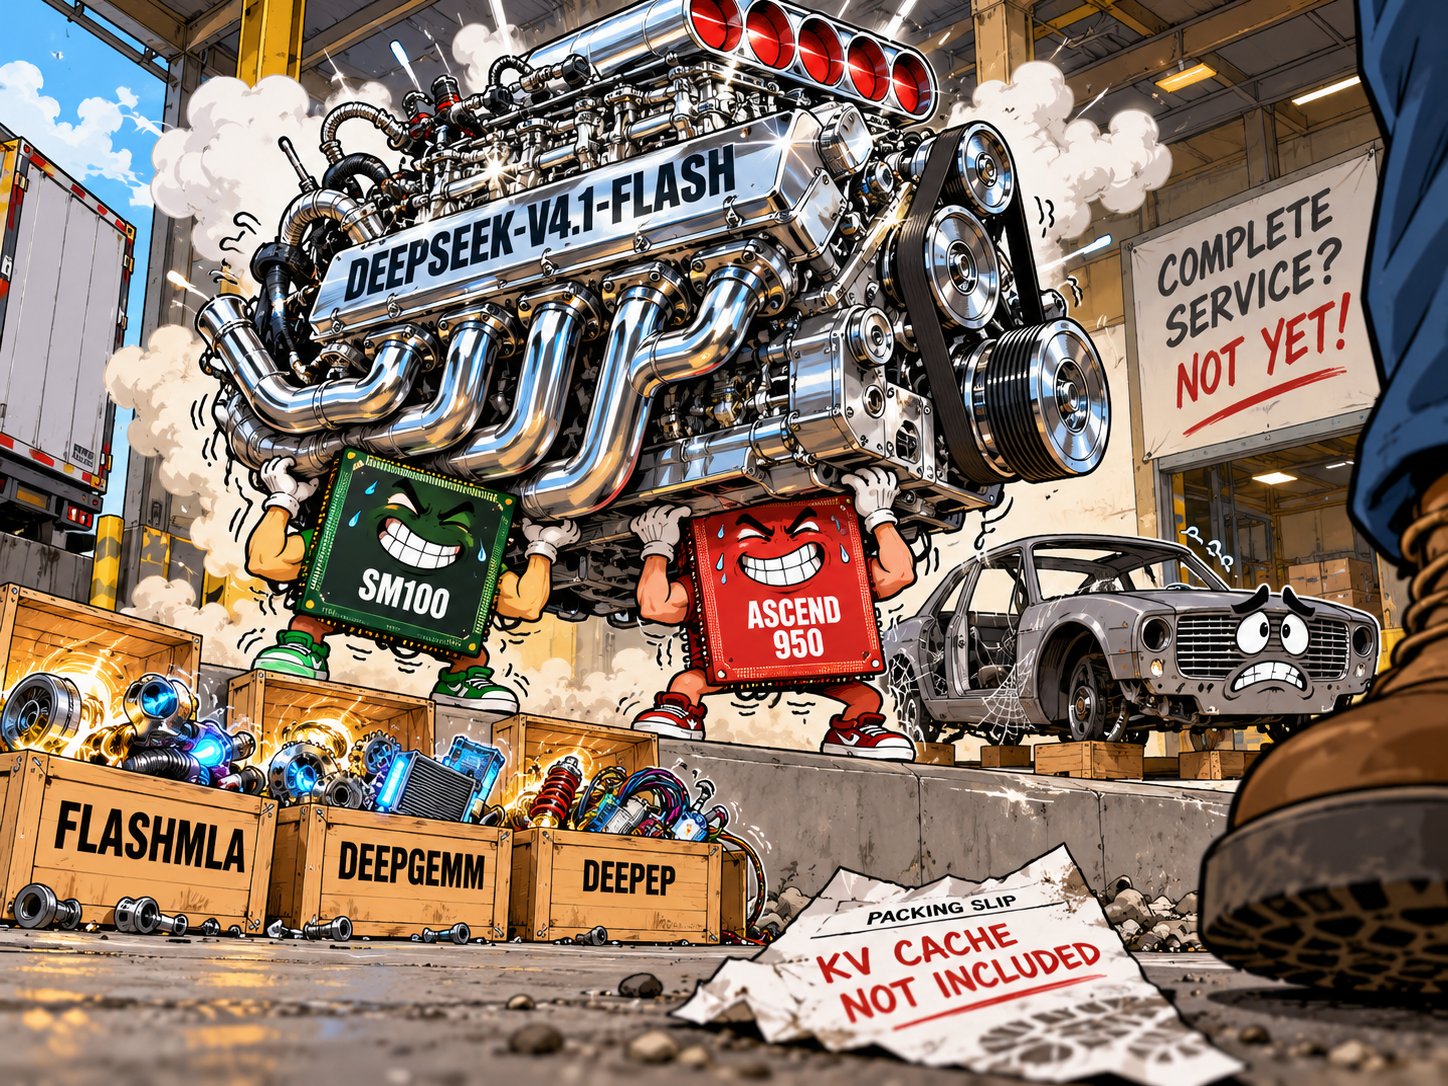
🧠 #DeepSeek has open-sourced #DeepInfer, the high-performance #inference framework that powers its large-scale production services. The release covers offline inference with the core features needed for serving at scale, currently for DeepSeek-V4.1-Flash #opensource #LLM ⚡ Optimized kernels from DeepSeek's own stack: #FlashMLA, #DeepGEMM, #DeepEP, TileKernels, DeepSelect and custom #TileLang kernels, plus an optimized model and sampler runtime 🔀 Parallelism via Attention DP / balanced context parallelism and #MoE expert parallelism with EPLB load balancing. Asynchronous scheduling overlaps CPU batch scheduling with device execution and is on by default 🎯 Faster decoding with DSpark draft tokens and confidence-scheduled verification (default max draft length: 5). SWA bounded replay cuts decoder prefill work by replaying only a bounded suffix 🔒 Batch-invariant inference keeps results identical across batch compositions, deterministic sampling returns identical outputs for identical inputs and seeds (both NVIDIA only). Structured outputs constrain generation to regex, JSON schema or EBNF grammar 🖥️ Hardware: #NVIDIA SM100 GPUs and #Huawei Ascend 950 NPUs. Requires Linux, GCC 13+, #Python 3.12 and #CUDA 13 or CANN 9.2. Benchmarks were measured on 4 SM100 GPUs for prefill and 64 for decode 🧩 Not included: a KV cache system, prefill/decode disaggregation and load balancing across data-parallel replicas. Originally built on #vLLM with inspiration from #SGLang and TensorRT-LLM. Apache 2.0 license 🌐 https://github.com/deepseek-ai/DeepInfer