deepseek-v4.1IMAGE
本地部署 V4.1 Flash:2.9 bit 量化,512K 上下文 126 tok/s
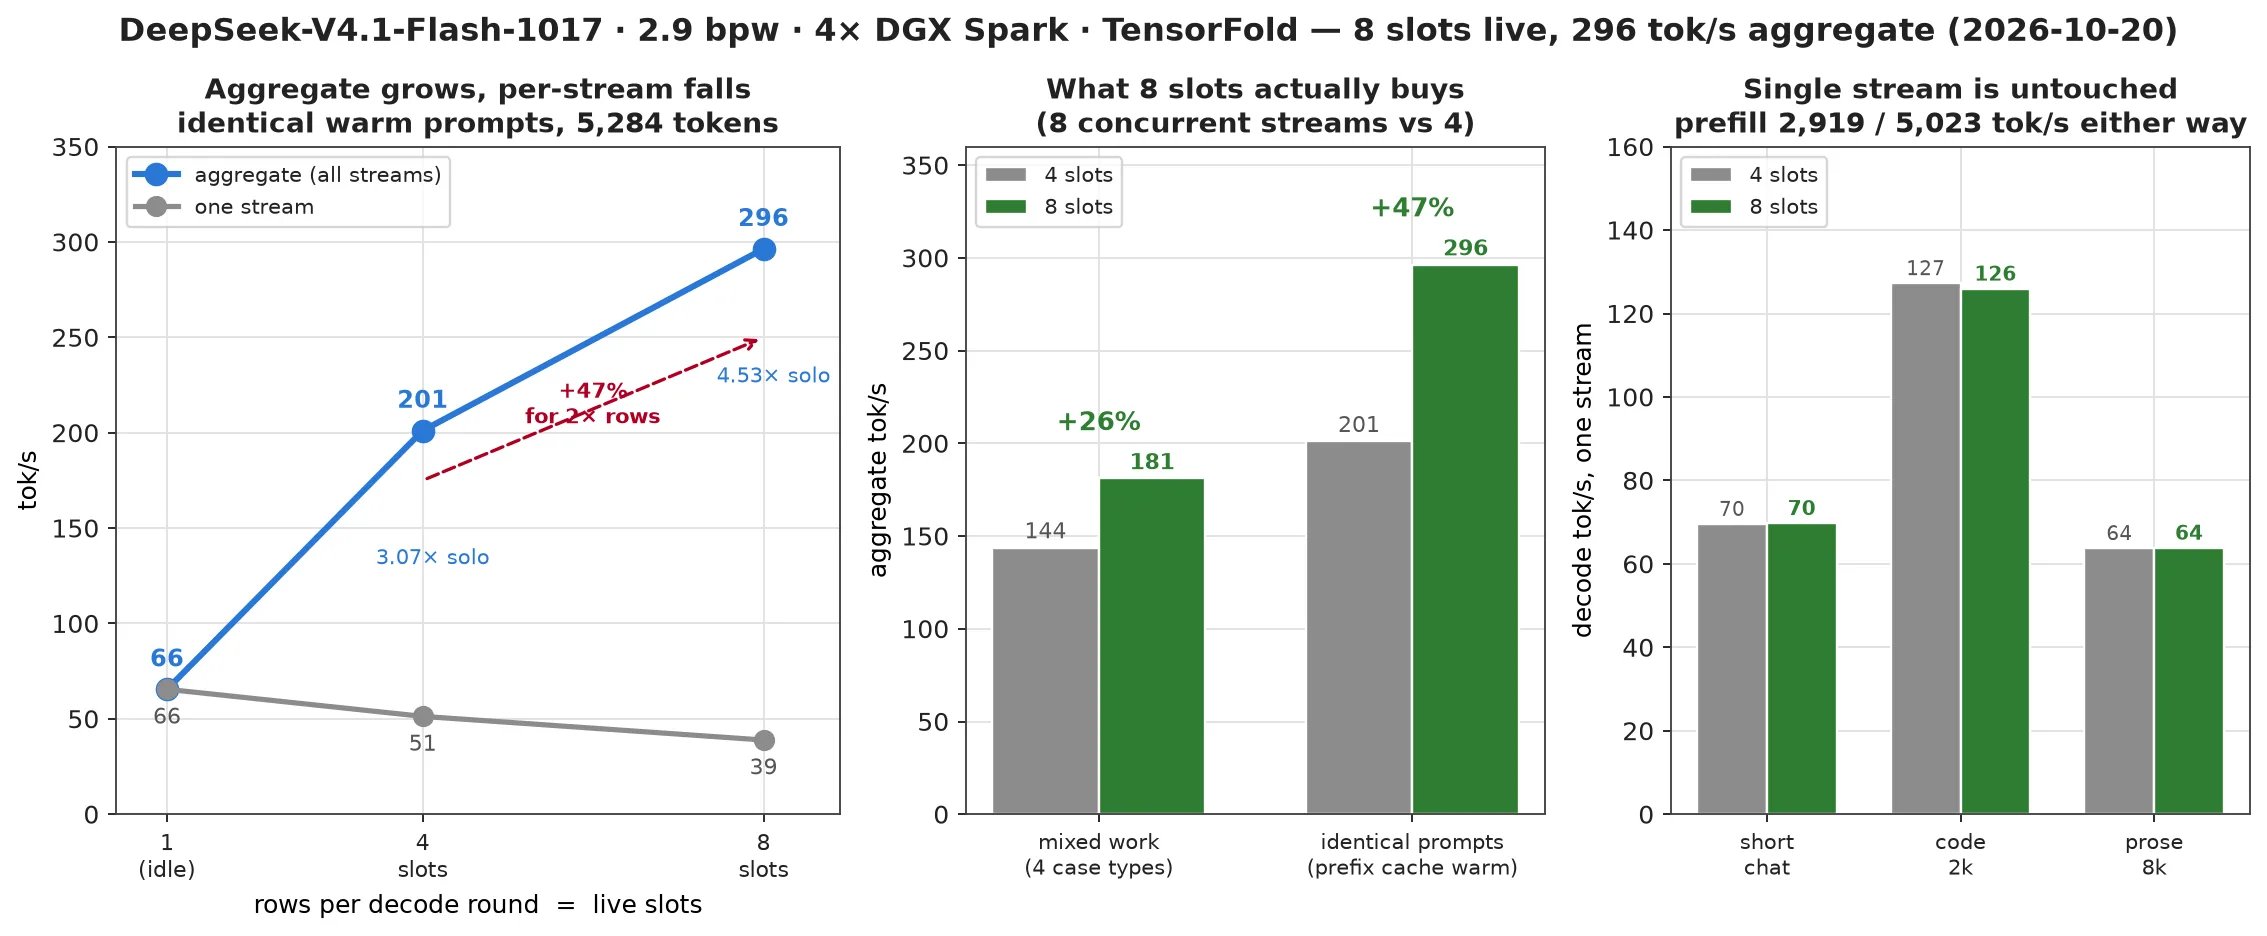
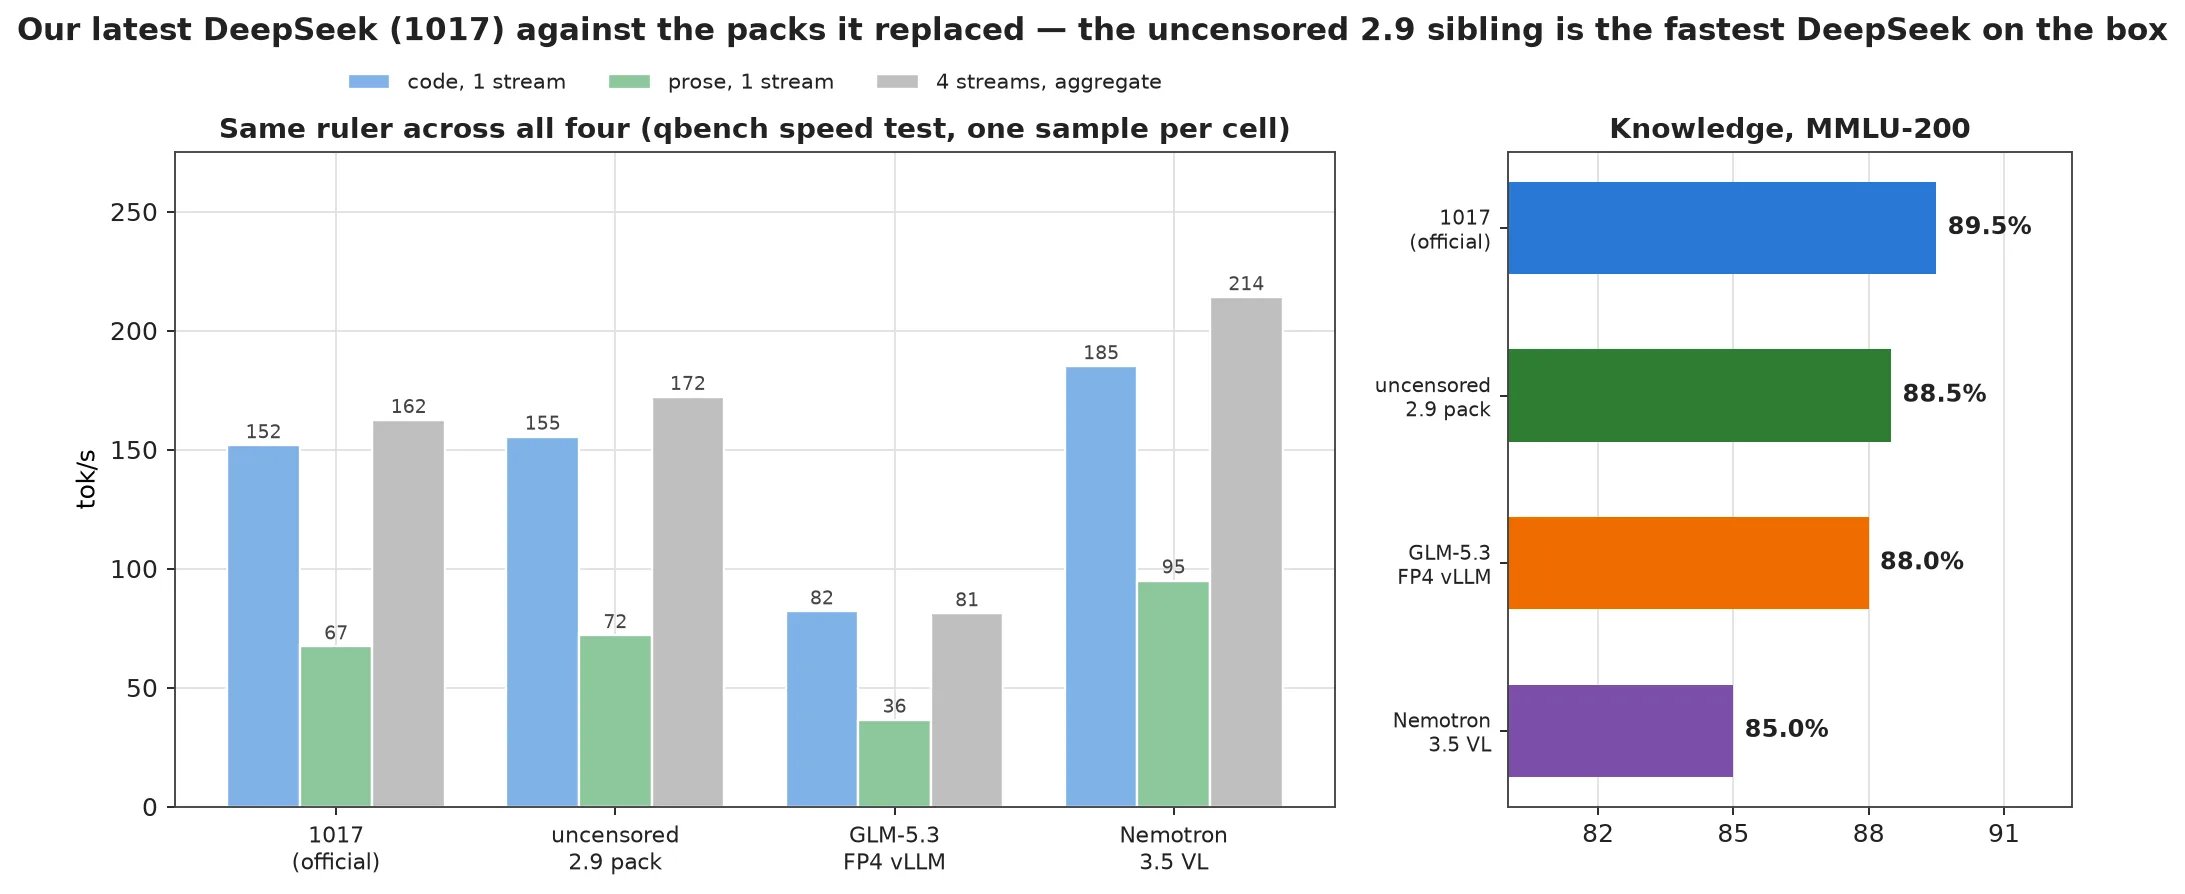
自研推理引擎上跑 2.9 bit 量化的 V4.1 Flash,单流写代码 126 tok/s、八流合计 296 tok/s,读 21K+ token 提示达 5000 tok/s。
Neko Legends
@softpoo10 天前收录原推发布于 2026.10.21
Neko Legends @softpoo原推发布于 2026.10.21
Local now serving DeepSeek-V4.1-Flash at 2.9 bits with 512K of context per request, on our own inference engine. One stream: 126 tok/s writing code. Eight streams: 296 tok/s total. Reading a 21K+-token prompt: 5,000 tok/s Rebased from Tensorfold 1.1.0, will make a PR back in to @ashxhart official repo after a few more extra fixes and improvements due to newly released DeepInfer (not entirely compatible but 4 concepts can be borrowed). .
x.com/softpoo/status/2112620314803024324采集于 2026.10.21 12:10