四张矿卡跑 V4.1 Flash:287 tok/s,快过两台 GX10
四张 CMP 170HX 跑 V4.1 Flash 代码任务单用户 287 tok/s、八并发 728,对比两台 ASUS GX10 的 91 tok/s;但依赖解锁工具和特定量化。
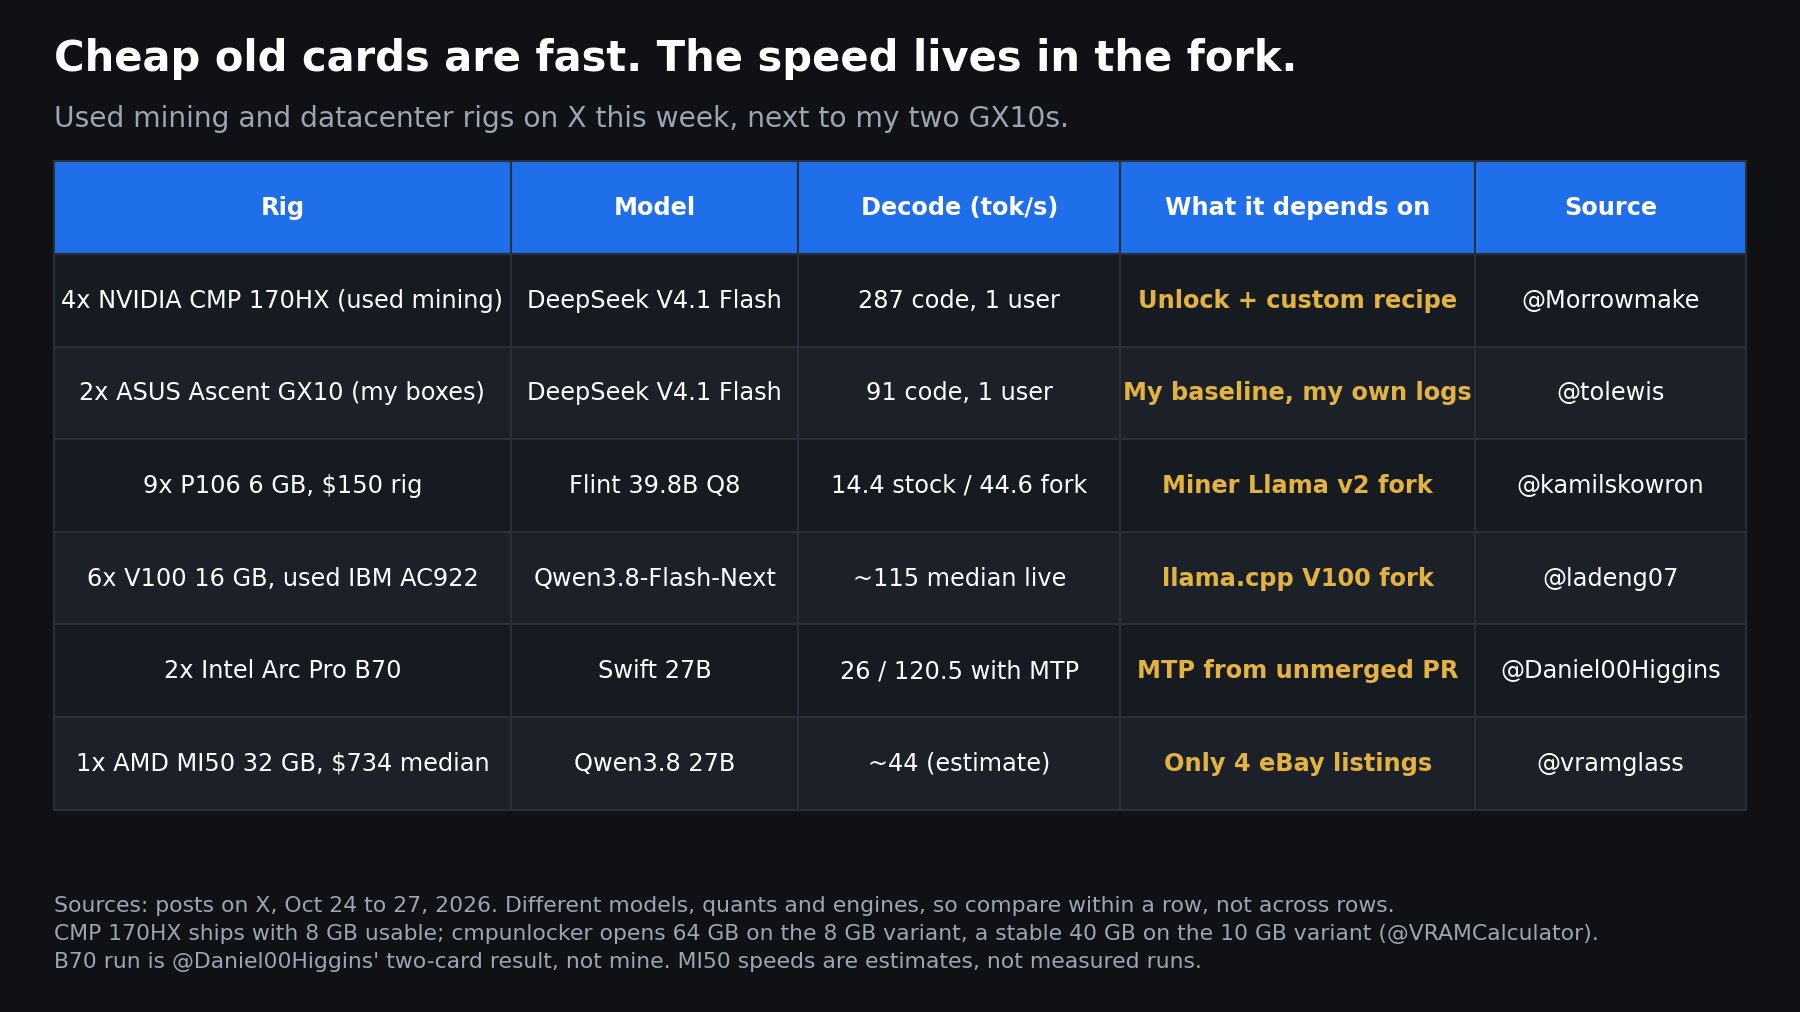
Four used mining cards are running DeepSeek V4.1 Flash 3x faster than my two GX10s. @Morrowmake put it on four NVIDIA CMP 170HX cards. 287 tok/s on code with one user, 728 with eight. My two ASUS GX10s did 91 on code with the same model. He says four 170HXs cost about the same as two DGX Sparks, and the GX10 is ASUS's version of that box. The question in my replies this week is whether a used mining card is worth it for local AI. On speed, yeah. The 170HX is a GA100, the same chip as the A100, with HBM2e at about 1.5 TB/s. The catch is it ships with 8 GB usable. The rest comes from an unlock tool called cmpunlocker. Per @VRAMCalculator the 8 GB version opens to 64 GB and the 10 GB version stops at a stable 40. Used price is $2,300 to $2,700, and the listing won't always tell you which one you're getting. The other cheap rigs on my feed look the same way: Nine 6 GB P106 mining cards, a $150 rig: 14.4 tok/s on stock llama.cpp, 44.6 on @kamilskowron's Miner Llama v2 fork Six V100s in a used IBM AC922: about 115 tok/s median on Qwen3.8-Flash-Next, on a llama.cpp V100 fork (@ladeng07) One AMD MI50, 32 GB of HBM2: $734 eBay median with only 4 listings, and the speeds on that post are estimates (@vramglass) Every fast number there depends on an unlock, a fork or a recipe that one person keeps alive. Morrowmake also says EXL3 cuts the 170HX's speed in half, so you're stuck with the quants that work on it. My B70s have the same problem. The 120.5 tok/s two-B70 run I posted Sunday (@Daniel00Higgins) used MTP from a llama.cpp PR that got closed without merging. Without it, 26. If you like tinkering, the 170HX numbers are hard to ignore. If your agents have to run every day, find out which variant is in the listing and check when the fork last got a commit before you buy.