单张 DGX Spark 上 V4.1 Flash 1.62bpw 量化:35.5 tok/s
SAGE-EXL3 1.62bpw 量化在单台 DGX Spark 上跑 vLLM,解码 35.5 tok/s、预填充 1189 tok/s、229K 上下文,代码答案一致率 99.61%,权重已放出。
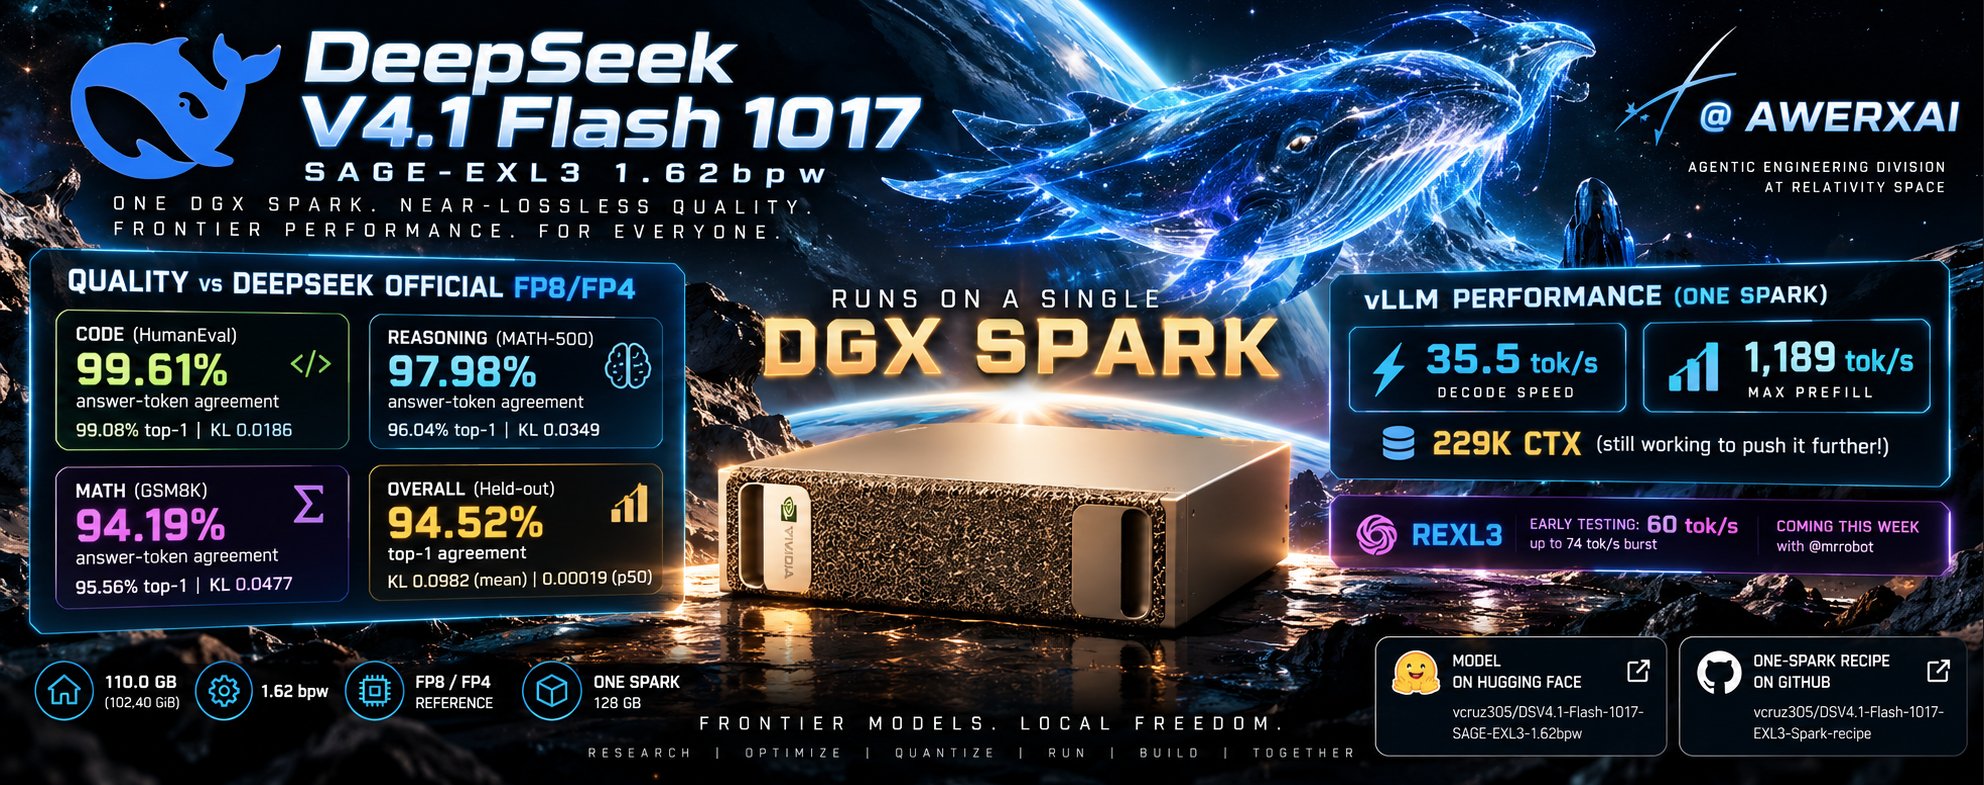
🚨 𝗜 𝗝𝗨𝗦𝗧 𝗔𝗖𝗛𝗜𝗘𝗩𝗘𝗗 𝗦𝗢𝗠𝗘𝗧𝗛𝗜𝗡𝗚 𝗜𝗡𝗖𝗥𝗘𝗗𝗜𝗕𝗟𝗘 𝗢𝗡 𝗢𝗡𝗘 𝗗𝗚𝗫 𝗦𝗣𝗔𝗥𝗞! 🧪🔥 With the support of @AWERXAI, I'm excited to release something VERY special for the local AI community! 🧠 @deepseek_ai 𝗗𝗲𝗲𝗽𝗦𝗲𝗲𝗸 𝗩𝟰.𝟭 𝗙𝗹𝗮𝘀𝗵 𝟭𝟬𝟭𝟳 📦 𝗦𝗔𝗚𝗘-𝗘𝗫𝗟𝟯 𝗮𝘁 𝗷𝘂𝘀𝘁 𝟭.𝟲𝟮 𝗯𝗽𝘄 𝗲𝘅𝗽𝗲𝗿𝘁𝘀 💻 𝟵𝟵.𝟲𝟭% 𝗖𝗢𝗗𝗘 𝗮𝗻𝘀𝘄𝗲𝗿-𝘁𝗼𝗸𝗲𝗻 𝗮𝗴𝗿𝗲𝗲𝗺𝗲𝗻𝘁! ⚡ 𝟯𝟱.𝟱 𝘁𝗼𝗸/𝘀 𝗱𝗲𝗰𝗼𝗱𝗲 𝗼𝗻 𝘃𝗟𝗟𝗠! 🚀 𝟭,𝟭𝟴𝟵 𝘁𝗼𝗸/𝘀 𝗠𝗔𝗫 𝗣𝗥𝗘𝗙𝗜𝗟𝗟! 🧠 𝟮𝟮𝟵𝗞 𝗖𝗧𝗫 (𝘀𝘁𝗶𝗹𝗹 𝘄𝗼𝗿𝗸𝗶𝗻𝗴 𝘁𝗼 𝗽𝘂𝘀𝗵 𝗶𝘁 𝗳𝘂𝗿𝘁𝗵𝗲𝗿!) 𝗔𝗟𝗟 𝗢𝗡 𝗢𝗡𝗘. 𝗗𝗚𝗫. 𝗦𝗣𝗔𝗥𝗞. 🤯 And YES, the quantized weights are AVAILABLE NOW! 💚 ━━━━━━━━━━━━━━━━━━━━ 🧪 𝗧𝗛𝗘 𝗟𝗔𝗦𝗧 𝟳𝟮 𝗛𝗢𝗨𝗥𝗦 𝗛𝗔𝗩𝗘 𝗕𝗘𝗘𝗡 𝗜𝗡𝗦𝗔𝗡𝗘! Just a few days ago, I published my article about @nvidiaai's FP4-Local format: The Good, The Bad & The Ugly. One thing really stuck with me... NVIDIA demonstrated what was possible when aggressive quantization and intelligent optimization come together. But there's a problem. 𝗥𝗘𝗣𝗥𝗢𝗗𝗨𝗖𝗜𝗡𝗚 𝗠𝗔𝗦𝗦𝗜𝗩𝗘 𝗤𝗨𝗔𝗡𝗧𝗜𝗭𝗔𝗧𝗜𝗢𝗡 𝗧𝗥𝗔𝗜𝗡𝗜𝗡𝗚 𝗣𝗜𝗣𝗘𝗟𝗜𝗡𝗘𝗦 𝗜𝗦 𝗢𝗨𝗧 𝗢𝗙 𝗥𝗘𝗔𝗖𝗛 𝗙𝗢𝗥 𝗠𝗢𝗦𝗧 𝗟𝗢𝗖𝗔𝗟 𝗔𝗜 𝗘𝗡𝗧𝗛𝗨𝗦𝗜𝗔𝗦𝗧𝗦. That inspired me. I've been developing my own SAGE-EXL3 process, and I wanted to see just how far I could push the latest DeepSeek Flash release while keeping the results accessible to the community. So I spent the last 72 hours pushing the limits. And the results genuinely surprised me! 🔥 ━━━━━━━━━━━━━━━━━━━━ 🏆 𝗧𝗛𝗘 𝗥𝗘𝗦𝗨𝗟𝗧𝗦 𝗔𝗥𝗘 𝗖𝗥𝗔𝗭𝗬! I measured my 1.62 bpw expert quant against DeepSeek's native FP4 release checkpoint using held-out sequences and full-vocabulary token predictions. And when I saw the CODE results, I could barely believe it! 🧪 𝗙𝗜𝗗𝗘𝗟𝗜𝗧𝗬 𝗩𝗦 𝗗𝗘𝗘𝗣𝗦𝗘𝗘𝗞'𝗦 𝗡𝗔𝗧𝗜𝗩𝗘 𝗙𝗣𝟴/𝗙𝗣𝟰 𝗥𝗘𝗟𝗘𝗔𝗦𝗘 💻 𝗖𝗢𝗗𝗘 — 𝗛𝘂𝗺𝗮𝗻𝗘𝘃𝗮𝗹 ✅ 99.08% Top-1 Agreement ✅ 𝟵𝟵.𝟲𝟭% 𝗔𝗡𝗦𝗪𝗘𝗥-𝗢𝗡𝗟𝗬 𝗔𝗚𝗥𝗘𝗘𝗠𝗘𝗡𝗧! ✅ KL Divergence: 0.0186 🧠 𝗥𝗘𝗔𝗦𝗢𝗡𝗜𝗡𝗚 — 𝗠𝗔𝗧𝗛-𝟱𝟬𝟬 ✅ 96.04% Top-1 Agreement ✅ 97.98% Answer-Only Agreement ✅ KL Divergence: 0.0349 🔢 𝗠𝗔𝗧𝗛 — 𝗚𝗦𝗠𝟴𝗞 ✅ 95.56% Top-1 Agreement ✅ 94.19% Answer-Only Agreement ✅ KL Divergence: 0.0477 📊 𝗢𝗩𝗘𝗥𝗔𝗟𝗟 𝗛𝗘𝗟𝗗-𝗢𝗨𝗧 𝗙𝗜𝗗𝗘𝗟𝗜𝗧𝗬 🏆 94.52% Top-1 Agreement 📉 Mean KL: 0.0982 🎯 Median KL: 0.00019 𝗡𝗘𝗔𝗥-𝗟𝗢𝗦𝗦𝗟𝗘𝗦𝗦 𝗖𝗢𝗗𝗘 𝗧𝗢𝗞𝗘𝗡 𝗙𝗜𝗗𝗘𝗟𝗜𝗧𝗬 𝗔𝗧 𝗝𝗨𝗦𝗧 𝟭.𝟲𝟮 𝗕𝗣𝗪 𝗘𝗫𝗣𝗘𝗥𝗧𝗦! 🤯 These are direct teacher-forced fidelity measurements against native FP8, not task-level pass rates. But seeing this level of agreement at such aggressive compression is EXACTLY what I was working toward! ━━━━━━━━━━━━━━━━━━━━ ⚡ 𝗔𝗡𝗗 𝗬𝗘𝗦, 𝗜𝗧 𝗔𝗖𝗧𝗨𝗔𝗟𝗟𝗬 𝗥𝗨𝗡𝗦 𝗢𝗡 𝗢𝗡𝗘 𝗦𝗣𝗔𝗥𝗞! Not two Sparks. Not four Sparks. Not an expensive rented GPU cluster. 𝗢𝗡𝗘 𝟭𝟮𝟴𝗚𝗕 𝗗𝗚𝗫 𝗦𝗣𝗔𝗥𝗞. My latest vLLM measurements: ⚡ Decode: 35.5 tok/s 🚀 Maximum measured prefill: 1,189 tok/s For a model this large, compressed this aggressively, and maintaining this level of fidelity... 𝗧𝗛𝗔𝗧'𝗦 𝗔 𝗕𝗜𝗚 𝗗𝗘𝗔𝗟 𝗙𝗢𝗥 𝗟𝗢𝗖𝗔𝗟 𝗔𝗜! 💚 And remember, 1.62 bpw refers to the routed experts, not every parameter in the full model. ━━━━━━━━━━━━━━━━━━━━ 💚 𝗪𝗛𝗬 𝗧𝗛𝗜𝗦 𝗠𝗔𝗧𝗧𝗘𝗥𝗦. I have a simple goal. 𝗠𝗔𝗞𝗘 𝗣𝗢𝗪𝗘𝗥𝗙𝗨𝗟 𝗔𝗜 𝗔𝗖𝗖𝗘𝗦𝗦𝗜𝗕𝗟𝗘 𝗧𝗢 𝗣𝗘𝗢𝗣𝗟𝗘 𝗪𝗛𝗢 𝗗𝗢𝗡'𝗧 𝗛𝗔𝗩𝗘 𝗔𝗖𝗖𝗘𝗦𝗦 𝗧𝗢 𝗗𝗔𝗧𝗔𝗖𝗘𝗡𝗧𝗘𝗥𝗦. I don't want the future of local AI to be determined by who can rent the most GPUs or afford the largest training runs. I want developers, independent researchers and enthusiasts to have the freedom to experiment, quantize, optimize and run powerful models on hardware they actually OWN. NVIDIA's FP4-Local research showed me just how much potential remains in aggressive quantization. My goal with SAGE-EXL3 is to keep pushing that frontier while making advanced quantization more practical for the wider community. Today, I'm sharing the quantized checkpoint and the one-Spark serving recipe. 𝗧𝗛𝗜𝗦 𝗜𝗦 𝗝𝗨𝗦𝗧 𝗧𝗛𝗘 𝗕𝗘𝗚𝗜𝗡𝗡𝗜𝗡𝗚. ━━━━━━━━━━━━━━━━━━━━ 🧪 𝗡𝗢𝗪 𝗙𝗢𝗥 𝗧𝗛𝗘 𝗥𝗘𝗔𝗟 𝗧𝗘𝗦𝗧! The token-level fidelity results are incredible, but I'm not stopping there. I'm currently running a broader evaluation campaign to measure how closely this quant preserves the native FP8 model's actual task performance. 💻 HumanEval+ / MBPP+ 🧠 MMLU-Pro STEM / MATH-500 🔬 SciCode / LiveCodeBench 🔧 BFCL / Multi-step tool chains 🌍 MGSM 𝗧𝗛𝗘 𝗚𝗢𝗔𝗟 𝗜𝗦 𝗧𝗢 𝗣𝗥𝗢𝗩𝗘 𝗧𝗛𝗔𝗧 𝗔𝗚𝗚𝗥𝗘𝗦𝗦𝗜𝗩𝗘 𝗖𝗢𝗠𝗣𝗥𝗘𝗦𝗦𝗜𝗢𝗡 𝗗𝗢𝗘𝗦𝗡'𝗧 𝗛𝗔𝗩𝗘 𝗧𝗢 𝗠𝗘𝗔𝗡 𝗔𝗚𝗚𝗥𝗘𝗦𝗦𝗜𝗩𝗘 𝗤𝗨𝗔𝗟𝗜𝗧𝗬 𝗟𝗢𝗦𝗦! Those task-level results are coming next! 👀 ━━━━━━━━━━━━━━━━━━━━ 👀 𝗔𝗡𝗗 𝗢𝗡𝗘 𝗟𝗜𝗧𝗧𝗟𝗘 𝗧𝗘𝗔𝗦𝗘𝗥... @mr_r0b0t and I have also been working on an GB10 specialized inference engine called 𝗥𝗘𝗫𝗟𝟯. Early testing has been VERY exciting, including 60 tok/s with bursts reaching 74tok/s! We're putting the finishing touches on it and making sure everything is solid before releasing it. More on that VERY soon. 😏 ━━━━━━━━━━━━━━━━━━━━ 🙏 𝗔 𝗛𝗨𝗚𝗘 𝗧𝗛𝗔𝗡𝗞 𝗬𝗢𝗨! To @AWERXAI for supporting my work and helping make this contribution to the community possible. To @nvidiaai for the FP4-Local research that inspired me to push this experiment even further. To @justinn_builds for his initial vllm TP4 recipe that got me started in the right direction for loading this model up. To @mr_r0b0t for collaborating with me on what's coming next! And to @deepseek_ai for continuing to release powerful open-weight models that make community experiments like this possible. 𝗧𝗛𝗘 𝗕𝗘𝗦𝗧 𝗣𝗔𝗥𝗧 𝗢𝗙 𝗢𝗣𝗘𝗡 𝗔𝗜 𝗜𝗦 𝗪𝗛𝗔𝗧 𝗧𝗛𝗘 𝗖𝗢𝗠𝗠𝗨𝗡𝗜𝗧𝗬 𝗖𝗔𝗡 𝗕𝗨𝗜𝗟𝗗 𝗢𝗡 𝗧𝗢𝗣 𝗢𝗙 𝗜𝗧. 💚 🔗 𝗗𝗢𝗪𝗡𝗟𝗢𝗔𝗗 𝗠𝗬 𝗦𝗔𝗚𝗘-𝗘𝗫𝗟𝟯 https://huggingface.co/vcruz305/DSV4.1-Flash-1017-SAGE-EXL3-1.62bpw 🛠️ 𝗢𝗡𝗘-𝗦𝗣𝗔𝗥𝗞 𝗥𝗘𝗖𝗜𝗣𝗘 https://github.com/vcruz305/DSV4.1-Flash-1017-EXL3-Spark-recipe 𝗢𝗡𝗘 𝗦𝗣𝗔𝗥𝗞. 𝟭.𝟲𝟮 𝗕𝗣𝗪 𝗘𝗫𝗣𝗘𝗥𝗧𝗦. 𝟵𝟵.𝟲𝟭% 𝗖𝗢𝗗𝗘 𝗔𝗡𝗦𝗪𝗘𝗥 𝗔𝗚𝗥𝗘𝗘𝗠𝗘𝗡𝗧. 𝗟𝗘𝗧'𝗦 𝗞𝗘𝗘𝗣 𝗣𝗨𝗦𝗛𝗜𝗡𝗚 𝗟𝗢𝗖𝗔𝗟 𝗔𝗜 𝗙𝗢𝗥𝗪𝗔𝗥𝗗! 🚀🔥