GPT-6.1 Terra 在 AA 指数压过 Gemini 4 Argon 的五点原因
作者拆解 AA Intelligence Index v5.0:Terra 靠 FrontierCode 2.0 得分、Terminal-Bench 提升、幻觉率下降,加上 v5 换题和对手评测条件不利而排到 Argon 之上。
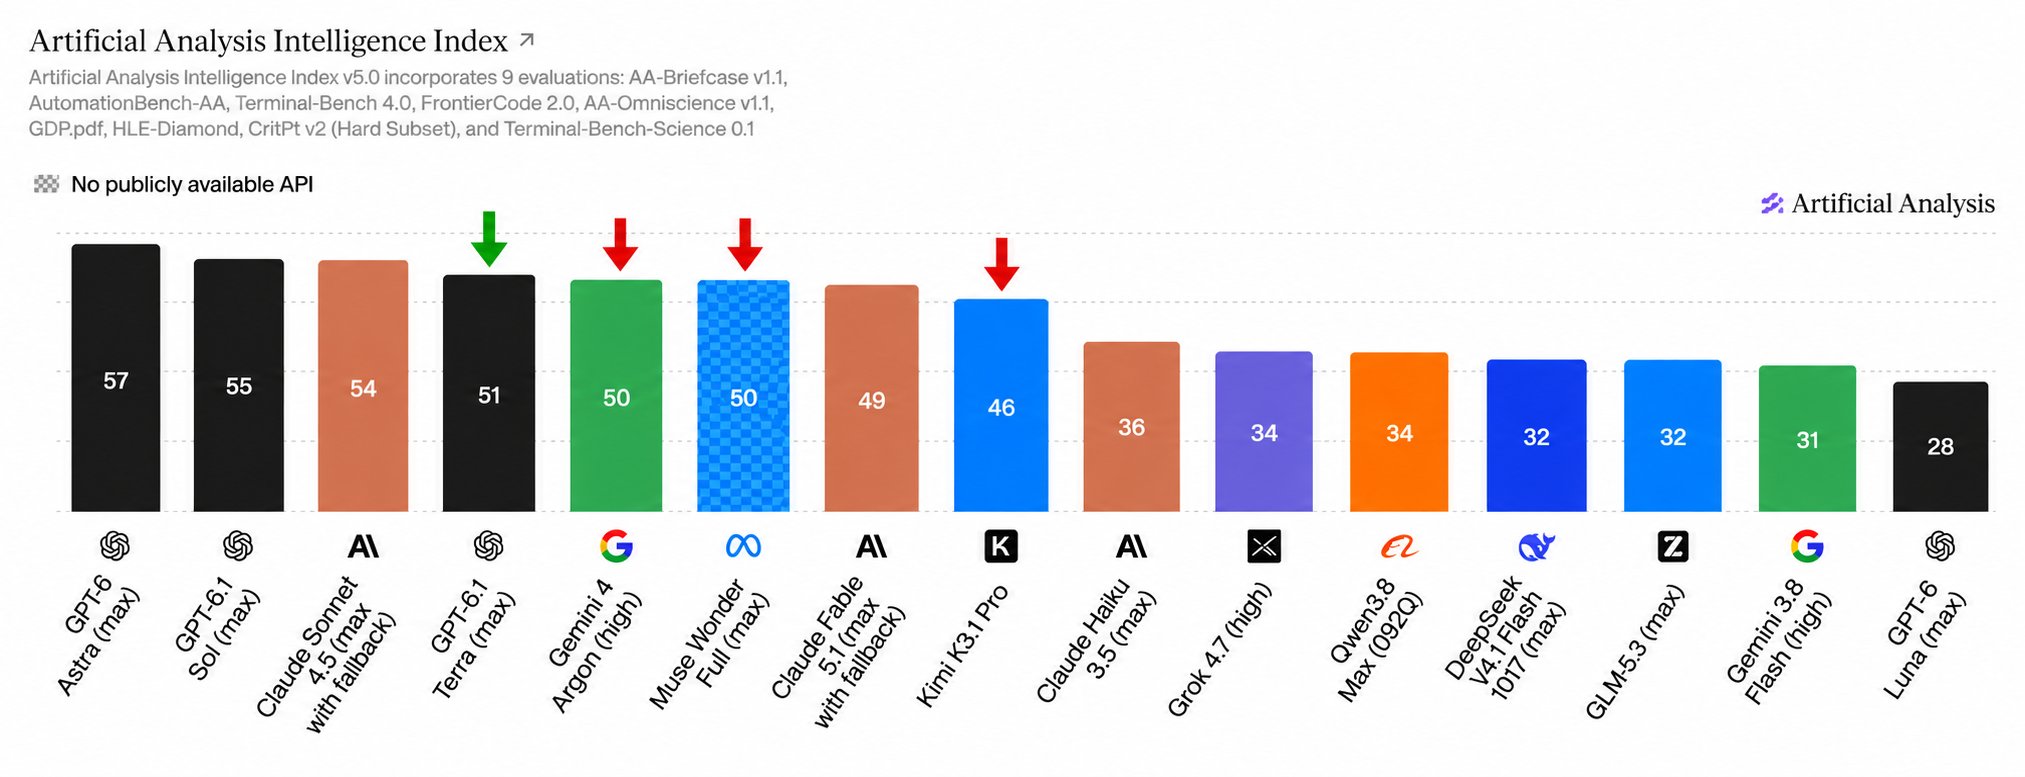
According to the Artificial Analysis Intelligence Index v5.0, GPT-6.1 Terra ranks above Gemini 4 Argon, Muse Wonder, and Claude Fable 5.1. At first glance, that sounds pretty absurd considering the difference in calibre between these models. Argon was reportedly matching Opus 5.5 on several benchmarks few weeks back, while Fable 5.1 is currently Anthropic’s best model in the Fable family. So I did some digging and found five reasons why GPT-6.1 Terra is rated so highly: 1. Coding quality: Terra scored 42.3% on FrontierCode 2.0. Since its release on Monday, the cognitive backend tests I’ve run have also tripled in size, with Terra outperforming the other three models. 2. Terminal skills: It jumped by roughly 20 points on Terminal-Bench 4.0. 3. Lower hallucination rate: Several claims suggest its hallucination rate dropped from around 88% to 38%, which would put it well ahead of Fable 5.1 in that area. 4. New scoring system: v5.0 removed three older tests and cut the weighting of GDP.pdf in half, a benchmark where Muse Wonder Full performs particularly well. 5. Weak spots from rivals: Kimi scored poorly on the new science tests, while Fable 5.1 is evaluated with its safety fallback enabled. Terra, meanwhile, is unrestricted for that particular use case. So while the ranking looks ridiculous at first, the changes to the benchmark mix and Terra’s gains in coding, terminal use, and reliability help explain why it ended up so high.
这条是引用着另一条写的:「Artificial Analysis 发布 Intelligence Index v5,GPT-6 Astra 排第二」