DeepInfer 跨机复用 KV 缓存机制拆解
作者拆解 DeepInfer 如何用约 100 PiB 的 3FS SSD 集群存 KV 块、按 128 token 哈希链匹配前缀,实现无粘性路由的跨机缓存复用。
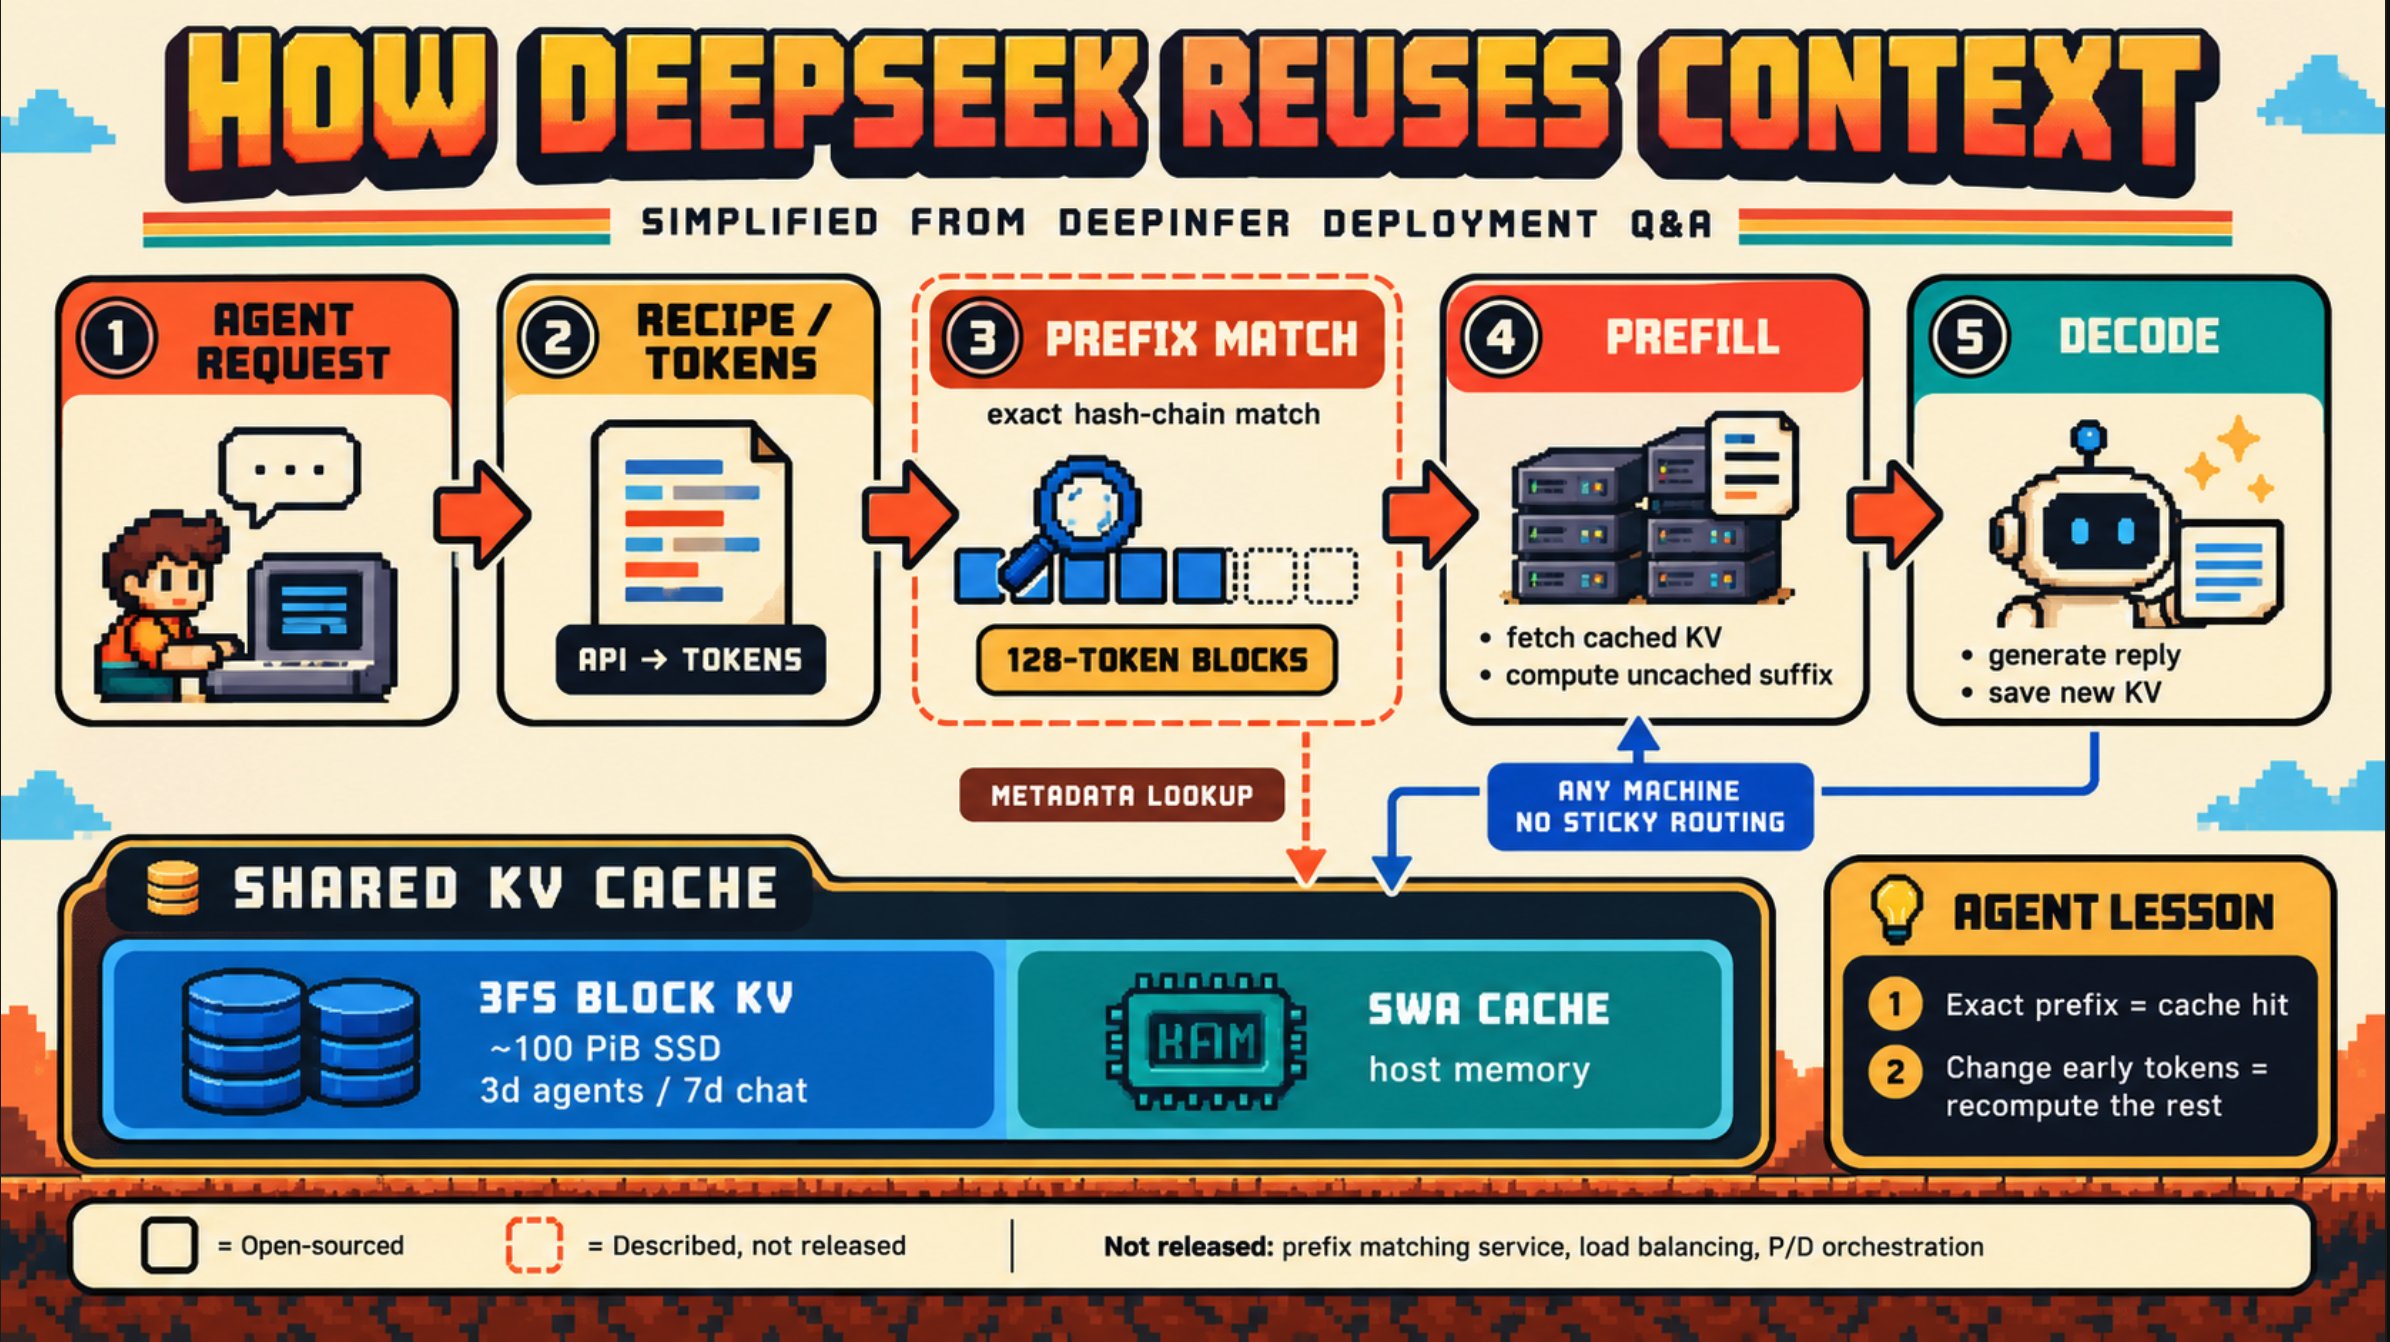
DeepSeek just open-sourced DeepInfer, the inference engine behind V4.1-Flash. One thing caught my eye: how DeepSeek reuses context across machines. They built a dedicated ~100 PiB SSD cluster (3FS) for block KV cache, retaining it for 3 days for agent traffic and 7 days for chat. But how does it work? Before routing a request, the entrypoint checks for cached prefixes using hash-chain matching in 128-token blocks. On a hit, any prefill machine can retrieve the cached KV blocks from shared storage. Data moves asynchronously into host memory, then into GPU memory layer by layer, overlapping computation. No sticky routing. No need to recompute the matched prefix. Interestingly, DeepInfer open-sources the inference engine, but the distributed KV cache service, prefill/decode orchestration, and load balancers are documented rather than included in the release. I put together a simplified architecture diagram below. And this has a direct implication for how we design AI agents. ↓
这条是引用着另一条写的:「DeepSeek 开源推理框架 DeepInfer,支撑 V4.1 Flash 生产服务」