vLLM 与 SGLang 称在 V4.1 Flash 上追平 DeepInfer
DeepSeek 10 月 20 日以 Apache 2.0 开源 V4.1 Flash 背后的推理引擎 DeepInfer;vLLM 称在 batch 8–256 的解码上追平,SGLang 称 prefill 最高 1.04 倍、解码多 7.4%,并指出 DeepInfer 缺 KV cache 等组件。
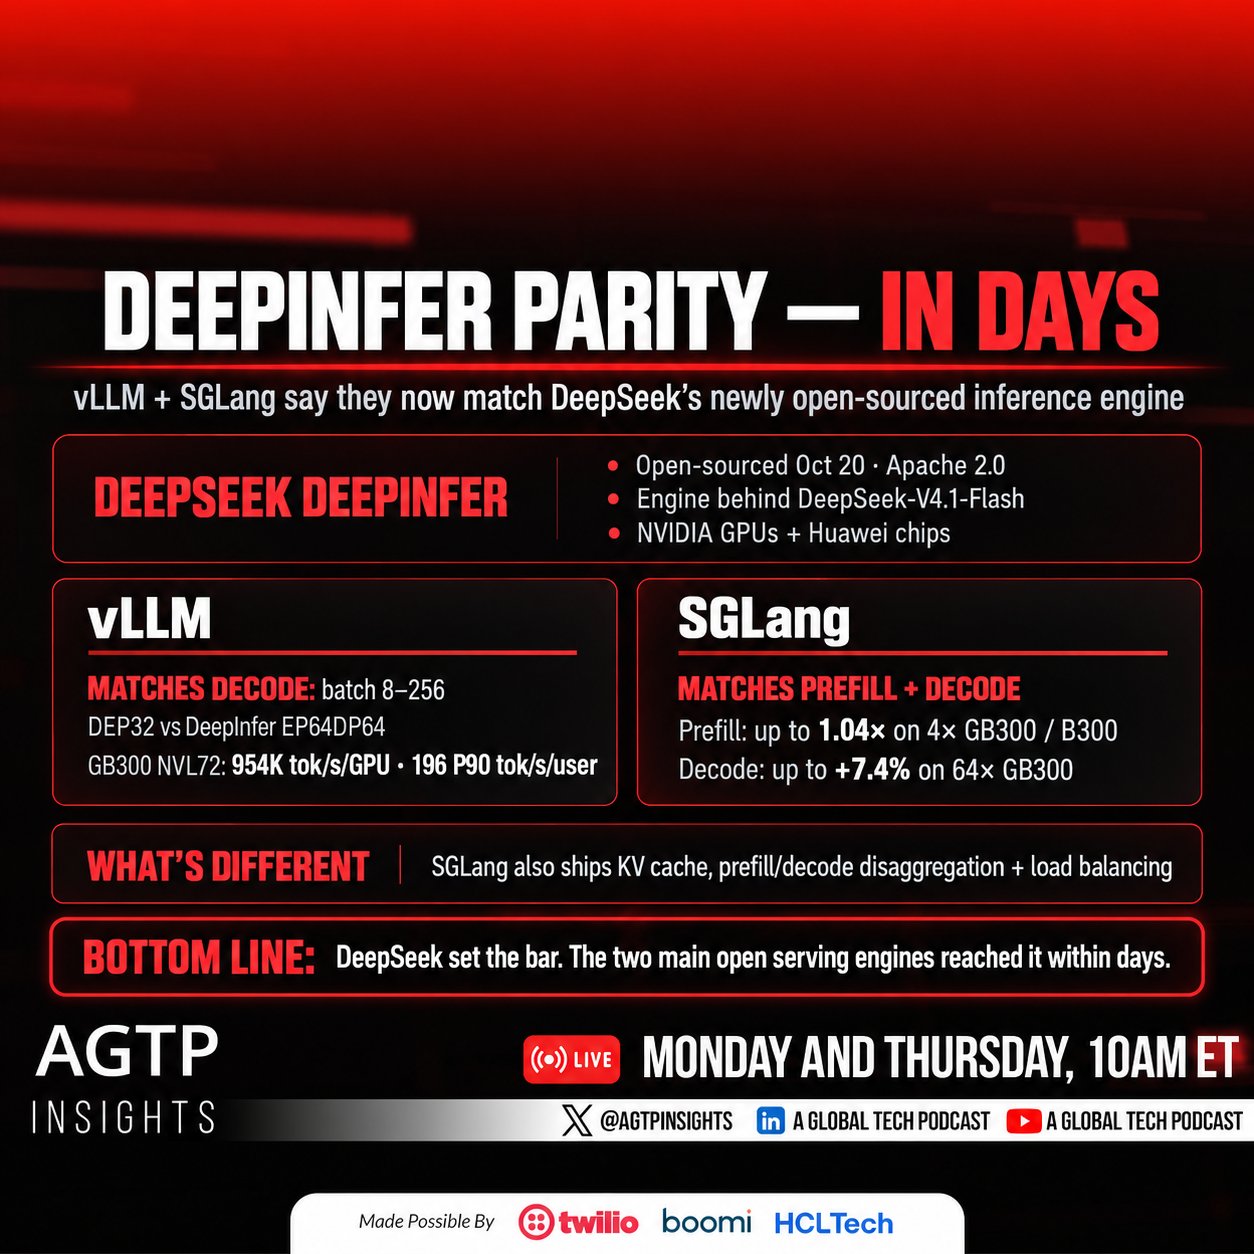
VLLM and SGLang both just said they match DeepSeek's new DeepInfer engine. Here's what you need to know. DeepSeek open-sourced DeepInfer on Oct 20 under Apache 2.0. It is the in-house inference engine behind DeepSeek-V4.1-Flash, and it supports NVIDIA GPUs and Huawei chips. It was originally built on vLLM. Now the two big open serving engines are claiming parity with it. vLLM posted first on Oct 25. It says it matches DeepInfer on DeepSeek's decode configuration across batch sizes 8 to 256. It does that at DEP32, against DeepInfer's EP64DP64. vLLM did it by integrating DeepSeek's open-source kernels and heavily optimizing prefill and decode. The work was led by the Inferact team, with help from NVIDIA and SemiAnalysis' AgentX benchmark. SGLang says it matches DeepInfer on both prefill and decode. It first brought in DeepSeek's Mega kernels (MegaMoE, MegaAttention, Mega-mHC, MegaGate), SWA bounded replay and Engram optimizations. Then it added more kernel fusions and breakable CUDA graphs for prefill. Everything is in SGLang main, with an end-to-end reproduction guide. SGLang also points out gaps in DeepInfer's release. It leaves out a KV cache system, prefill/decode disaggregation and load balancing. SGLang ships all three. Its team also says some prefill comparisons mix GB300 results with DeepInfer's published B300 numbers, and argues that makes a fair comparison hard. Key numbers: - vLLM decode: matches DeepInfer at batch sizes 8 to 256, using DEP32 vs EP64DP64 - vLLM on a GB300 NVL72 rack: 954K tokens/s per GPU, 196 tokens/s P90 per user, 7.9x its single-node result - SGLang prefill: up to 1.04x throughput on 4x GB300 and 4x B300 - SGLang decode: up to 7.4% more throughput on 64x GB300 The result is that DeepSeek's release set a performance bar, and the two main open engines reached it within days.
这条是引用着另一条写的:x.com/vllm_project/status/2114054277379641770