中美 token 产量与单位价值对比:DeepInfer 开源后 Ascend 950 或带来 190T 日输出
文章对比中美 token 总量、输出量和每 token 收入,指出 DeepSeek 输出价 0.60 美元对 Opus 的 25 美元,并估算 150 万张 Ascend 950 跑 DeepInfer 可日产约 190T 输出 token。
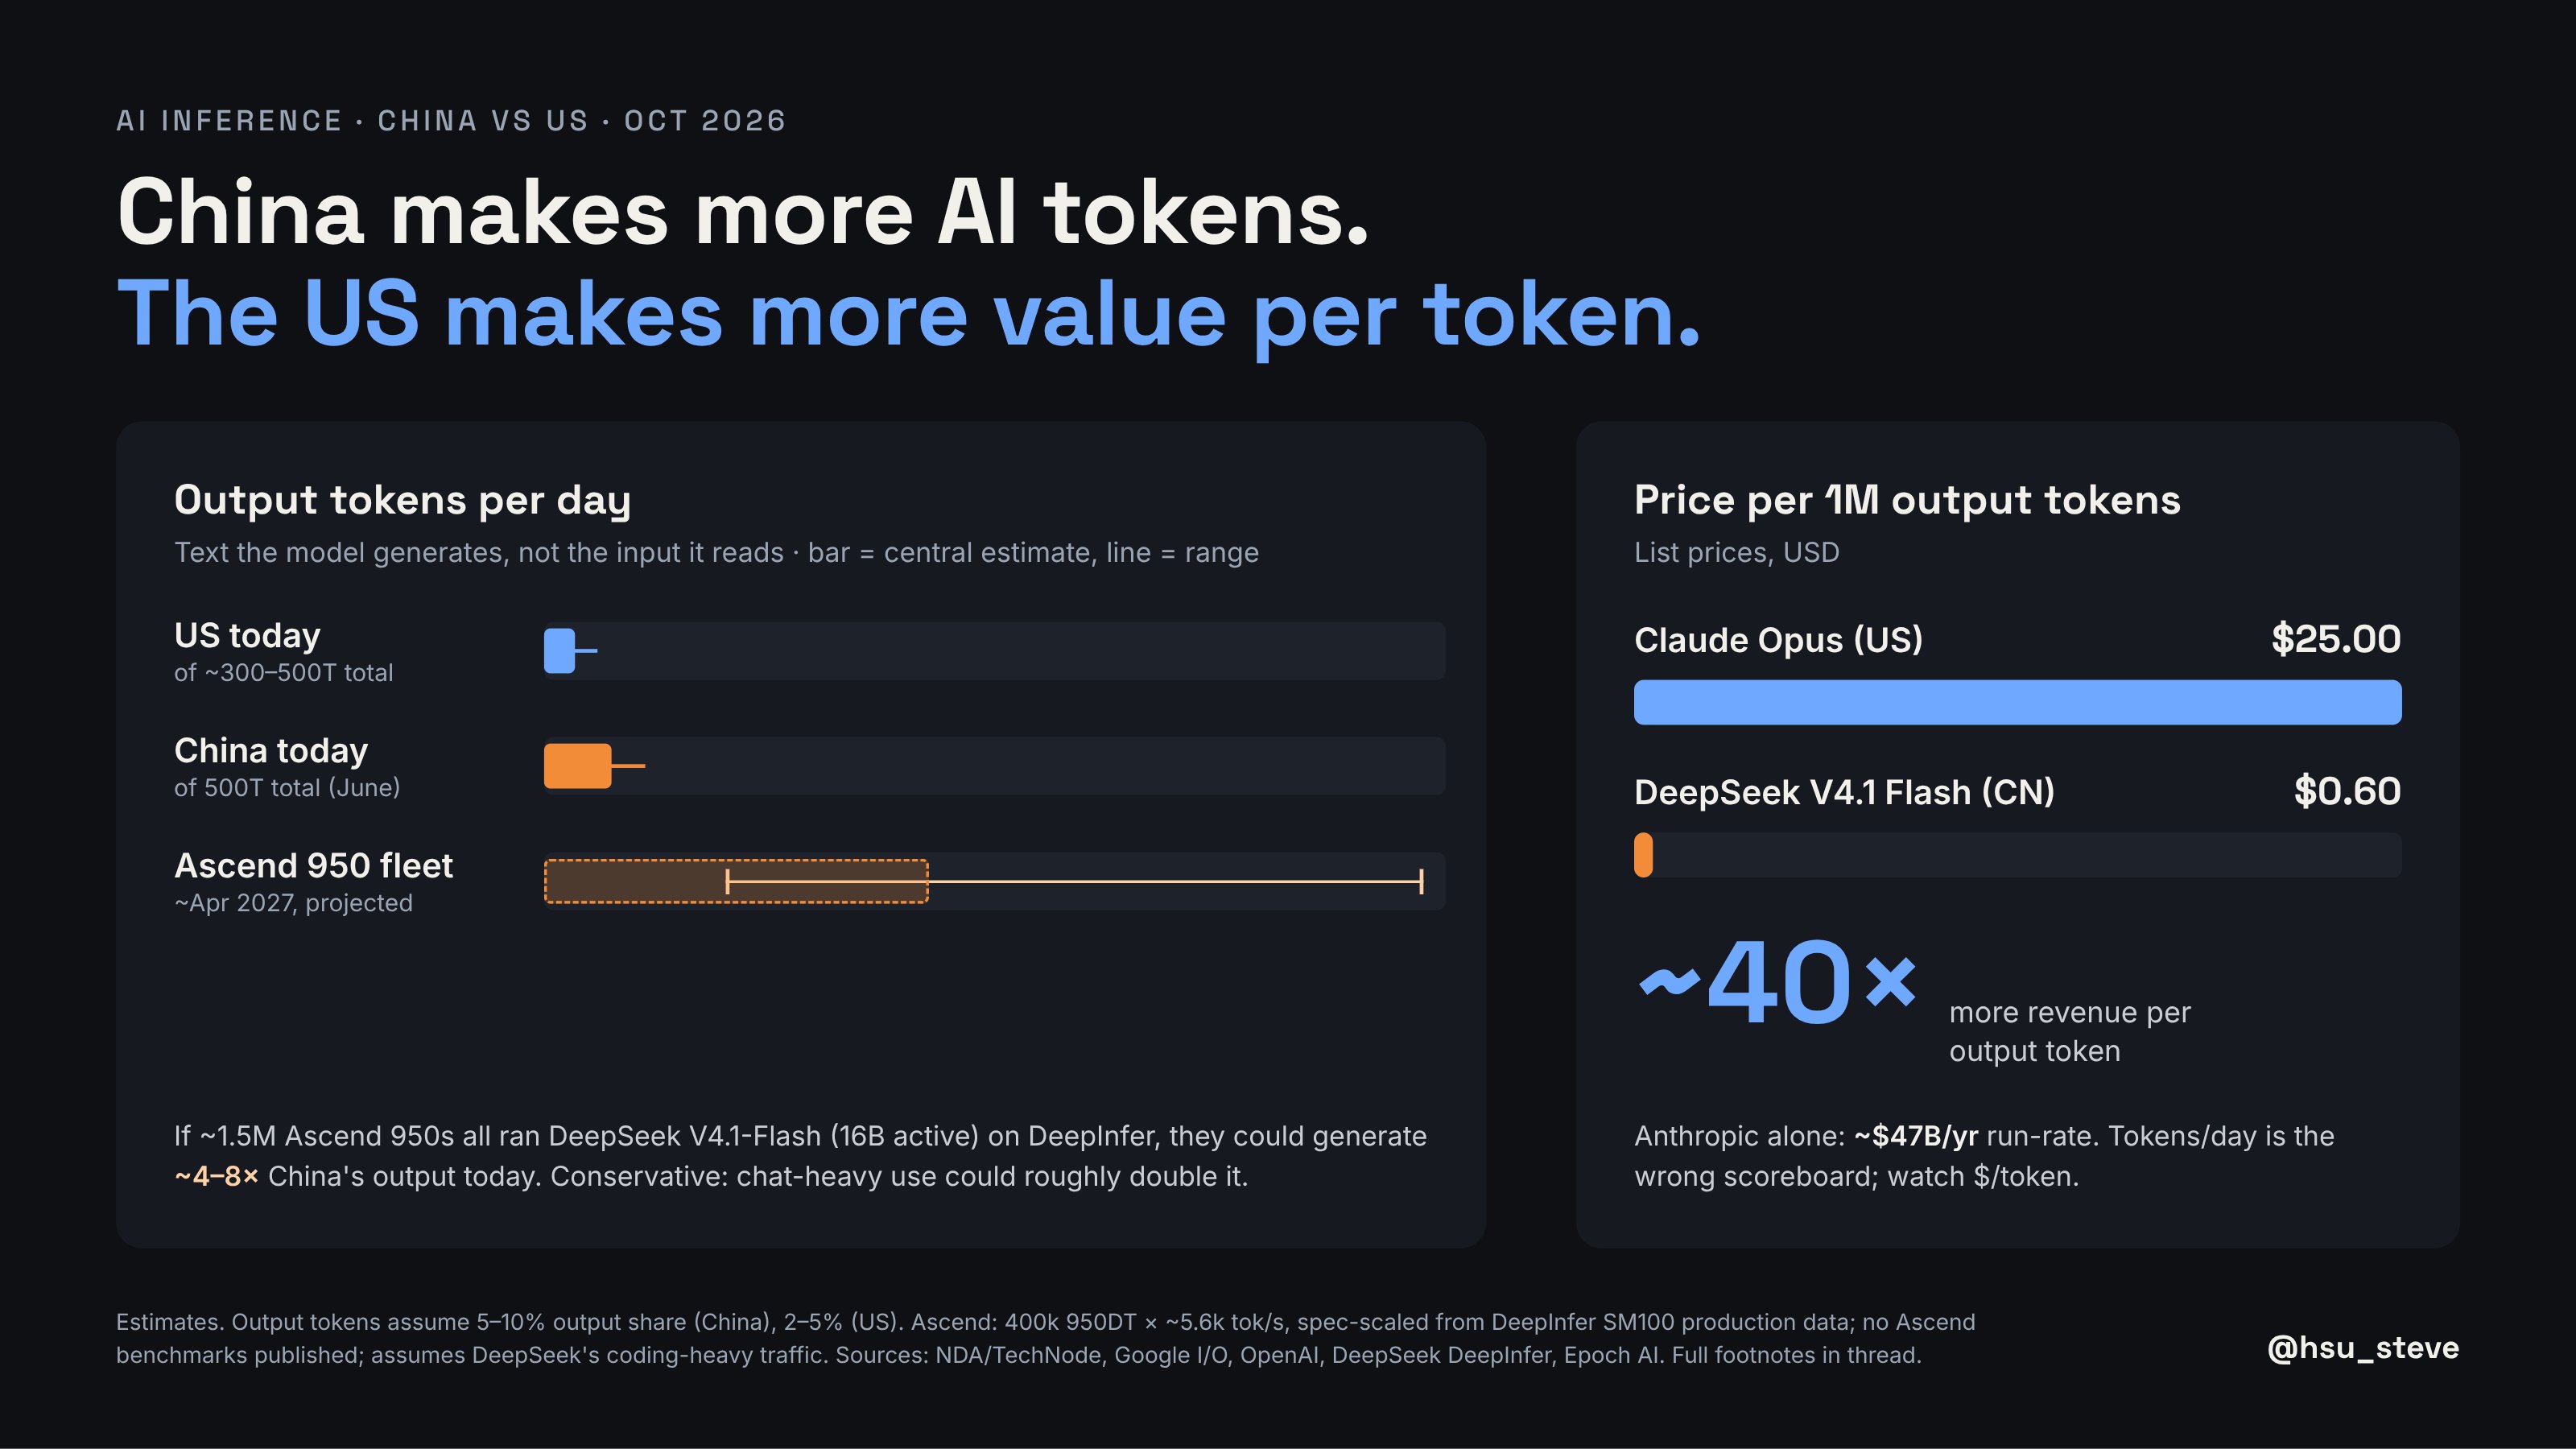
China produces more AI tokens. The US produces more AI value per token. Ascend stack significant in 2027. [ Research using Claude ] Two numbers get mixed up in token debates. Total tokens count everything a model processes, mostly input: prompts, documents and long agent contexts it reads. Output tokens are the text it actually generates, a small fraction of the total and the part that costs the most compute. Total tokens. China reported ~500T/day in June [1], mostly ByteDance's Doubao consumer chat [2]. The US has no national figure. Google (~107T/day) [3] plus OpenAI's API (~22T/day) [4] are the biggest disclosed pieces, and the full US total is probably in the same range as China's.¹ Output tokens. China's chat-heavy mix plausibly yields ~25–50T of output per day out of that 500T. US traffic is dominated by agentic coding, which reads huge contexts and writes relatively little, so US output is likely ~6–25T/day.² On both measures, China is plausibly ahead. Value per token. Here the US is far ahead. DeepSeek charges ~$0.60 per million output tokens; Claude Opus charges $25 [5][6]. Anthropic alone runs at ~$47B/yr [7]. The US spends far more compute and earns ~10× the revenue per token.³ What's coming. DeepSeek just open-sourced DeepInfer, the engine serving its V4.1-Flash model [8]. One ~2,400-GPU cluster handles 155T total tokens/day [9], and the engine officially supports Huawei's Ascend 950. Huawei could have ~1.5M Ascend 950s deployed by spring 2027 [10][11]. If they all ran V4.1-Flash on DeepInfer, they could generate roughly 190T output tokens/day, 4–8× China's output today. That estimate is conservative, based on DeepSeek's coding-heavy traffic; chat-heavy use could roughly double it. It's possible because V4.1-Flash uses only 16B active parameters per output token, so each chip generates tokens cheaply [12].⁴ Notes ¹ US total tokens. Google reported 3.2 quadrillion tokens/month in May 2026; 3.2Q ÷ 30 ≈ 107T/day. OpenAI reported 15B tokens/min on its API in March; 15B × 1,440 ≈ 21.6T/day, or roughly 25–60T/day with ChatGPT included. Anthropic, Meta, xAI and most of Microsoft don't disclose. The disclosed sum is ~150–250T/day. Applying Google's ~7×/yr growth since those dates gives a plausible current US total of ~300–500T/day, comparable to China's June figure. Both are self-reported, and they likely count tokens differently. ² Output share. Neither country publishes its input/output split, so these are assumptions. DeepSeek's production traffic is ~97% cache-hit input, ~2% uncached input and ~1% output [13]. Epoch models general chat at 8k in / 1k out (~11% output) and agentic use at 25k–128k in / 1k out (~1–4%) [14]. China at 5–10% output: 500T × 0.05–0.10 ≈ 25–50T output/day. US at 2–5%: ~300–500T × 0.02–0.05 ≈ 6–25T output/day. ³ Value per token. $25 ÷ $0.60 ≈ 40× on list output prices (Opus vs DeepSeek V4.1-Flash off-peak). Chinese state media itself puts domestic API prices at 1/3 to 1/20 of international competitors [15]. "~10× the revenue" is a rough judgment, not a measured ratio. Anthropic alone ($47B run-rate) plus OpenAI ($25B+) is far larger than any disclosed Chinese token revenue. ⁴ Ascend capacity calculation. Nvidia baseline (DeepSeek production, self-reported): 155T total tokens/day on ~2,400 SM100 GPUs. Per decode GPU, ~14k output tokens/s [13]. Scaling to Ascend: The 950DT has 4 TB/s memory bandwidth vs ~8 TB/s for B200 [16], and ~1 PFLOPS FP8 vs ~4.5 dense [17]. Decode at DeepSeek's ~230 tok/s per user is mostly bandwidth-bound. Assume 0.4× SM100 after a software haircut, so ~5.6k output tokens/s per 950DT. Fleet by ~April 2027: ~1.1M 950PR (prefill) + ~400k 950DT (decode), extrapolated from Epoch's 2026 estimate of ~750k 950PR and ~320k 950DT [10] plus the 2027 run rate. HBM supply caps the DT count [11]. Output: 400k × 5.6k tokens/s × 86,400 s ≈ 194T output tokens/day. Range: low ~90T (250k DT at 0.3×); high ~420T (700k DT at 0.5×). Against China today: 190T ÷ 25–50T ≈ 4–8×. Traffic mix: The 5.6k figure reflects DeepSeek's coding-heavy traffic (long contexts, ~1% output). Chat-heavy traffic raises decode throughput per chip and frees most 950PRs from prefill; they could decode at ~2–3k tok/s each. That gives a plausible ~350–450T output/day. Total tokens: In the coding-heavy case, total ≈ output × 100 ≈ 20 quadrillion/day. In the chat-heavy case, total ≈ output × 10 ≈ 3–5 quadrillion/day. Assumptions: The whole fleet runs this model at DeepSeek's utilization. No Ascend benchmarks have been published; these are spec-scaled estimates. References [1] TechNode, "China's daily AI token usage tops 500 trillion" (Aug 2026): https://technode.com/2026/08/28/chinas-daily-ai-token-usage-tops-500-trillion-as-compute-demand-grows/ [2] Pebblous, "China's 140 Trillion Daily Tokens as an Economic Metric": https://blog.pebblous.ai/report/china-token-economy-metric-2026-07/en/ [3] Shacknews, Google I/O 2026, 3.2 quadrillion tokens/month: https://www.shacknews.com/article/149205/google-3-2-quadrillion-monthly-ai-tokens [4] Panto, OpenAI statistics 2026: https://www.getpanto.ai/blog/openai-statistics [5] Fewer Better Faster, "Token Prices, Chip Scarcity" (DeepSeek off-peak pricing): https://fewerbetterfaster.substack.com/p/token-prices-chip-scarcity [6] Panto, Anthropic statistics 2026 (Opus pricing): https://www.getpanto.ai/blog/anthropic-ai-statistics [7] http://Gradually.ai, Claude statistics 2026: https://www.gradually.ai/en/claude-statistics/ [8] MarkTechPost, "DeepSeek Open-Sources DeepInfer": https://www.marktechpost.com/2026/10/20/deepseek-deepinfer-open-source-inference-framework/ [9] Latent Space AINews, DeepInfer production figures: https://www.latent.space/p/ainews-deepseek-deepinfer-open-source [10] Traders Agency, Epoch AI 2026 Ascend breakdown: https://tradersagency.com/blog/huawei-pulls-ascend-960dt-forward-to-q1-2027-says-ai-chip-demand-outstrips-its-capacity [11] SemiconductorX, Huawei/HiSilicon HBM constraints: https://semiconductorx.com/spotlight-huawei-hisilicon.html [12] Let's Data Science, V4.1-Flash architecture: https://letsdatascience.com/news/deepseek-updates-flash-model-with-leaner-serving-1cf96356 [13] BigGo Finance, DeepInfer revenue and traffic mix: https://finance.biggo.com/news/538ddce1-7259-43f0-9763-fa6d8949e475 [14] Epoch AI, "Is a compute crunch coming?": https://epoch.ai/gradient-updates/is-a-compute-crunch-coming [15] C114 / Kuai Keji, Chinese API pricing: https://m.c114.com.cn/w16-1307667.html [16] Huawei Central, Ascend 950DT specs: https://www.huaweicentral.com/huawei-ai-chip-three-years-three-major-ai-chip-development/amp/ [17] TechRadar, Ascend 950 vs H200 vs MI300: https://www.techradar.com/pro/huawei-ascend-950-vs-nvidia-h200-vs-amd-mi300-instinct-how-do-they-compare