1.62bpw 量化实测:单台 DGX Spark 跑 V4.1 Flash 1017 通过 332/353
作者用 1.62bpw SAGE-EXL3 量化在单台 DGX Spark 上跑 9 套共 353 题,通过 332 题(94.1%),高于 2.8bpw 和 2.9bpw 双 Spark 方案,并称 vLLM 配方已支持 524K 上下文。
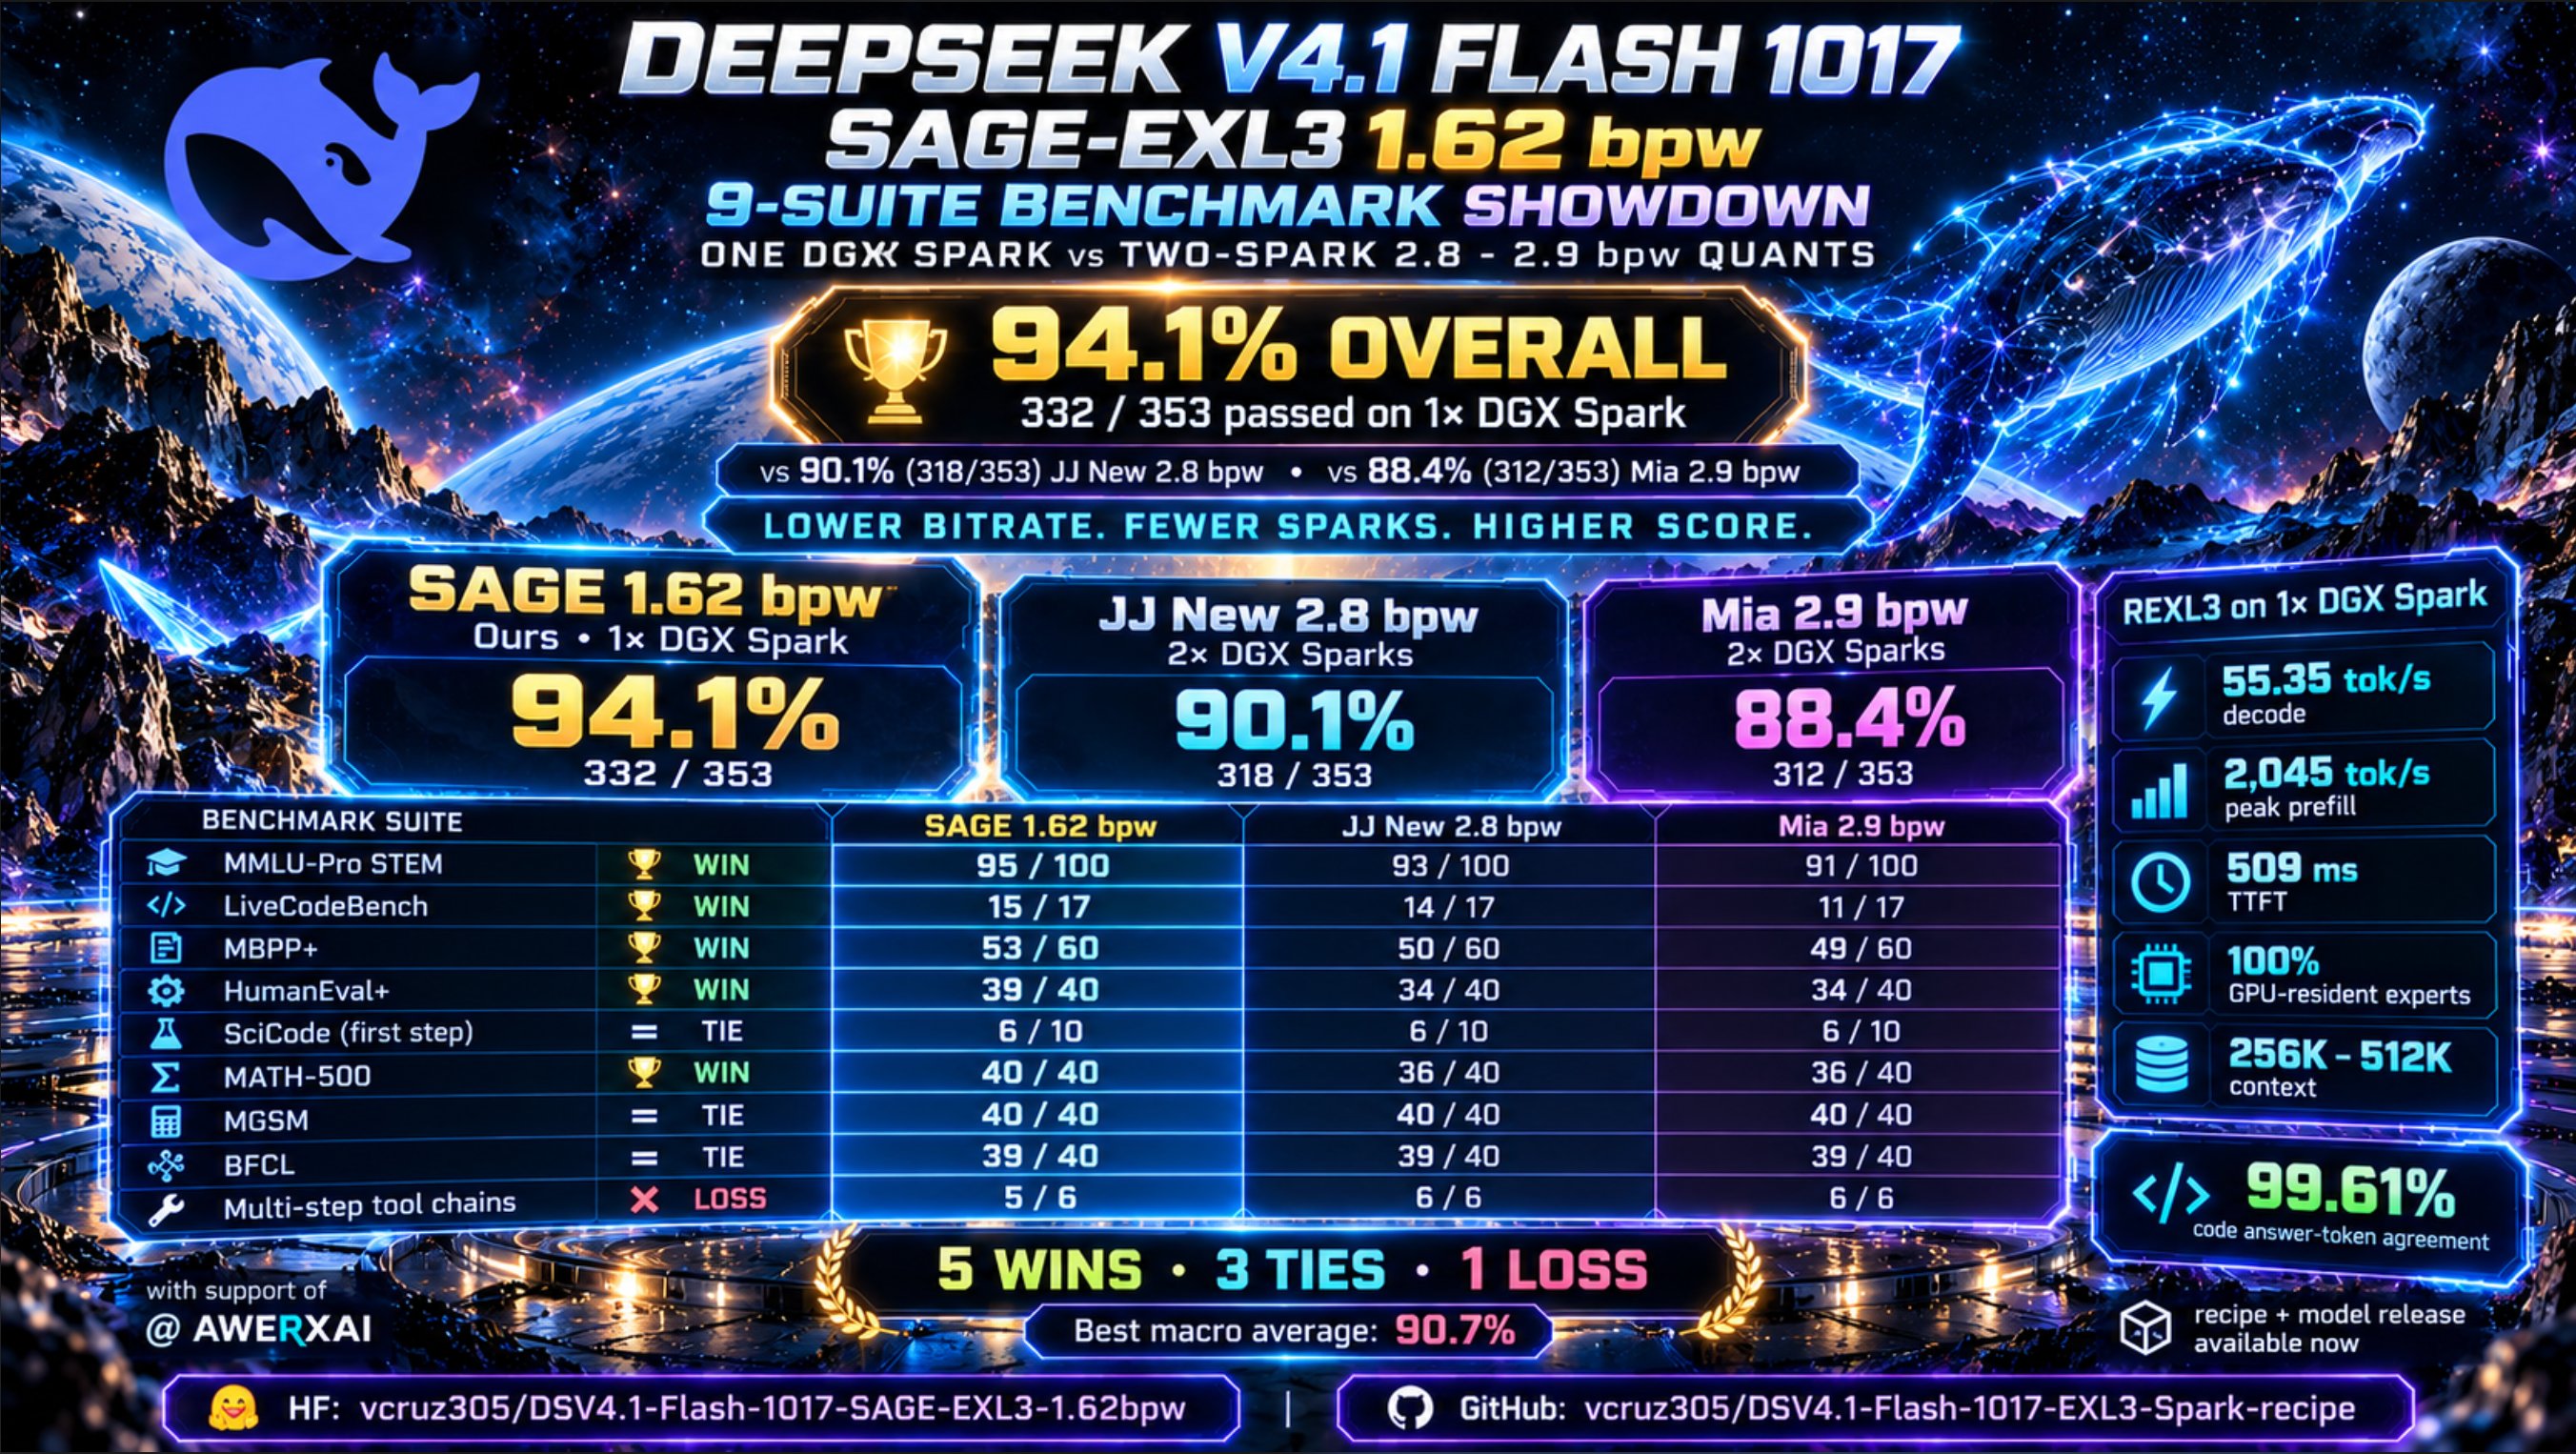
🚨 𝗠𝗬 𝟭.𝟲𝟮 𝗕𝗣𝗪 𝗗𝗘𝗘𝗣𝗦𝗘𝗘𝗞 𝗤𝗨𝗔𝗡𝗧 𝗝𝗨𝗦𝗧 𝗕𝗘𝗔𝗧 𝗧𝗪𝗢 𝗛𝗜𝗚𝗛𝗘𝗥-𝗣𝗥𝗘𝗖𝗜𝗦𝗜𝗢𝗡, 𝗧𝗪𝗢-𝗦𝗣𝗔𝗥𝗞 𝗤𝗨𝗔𝗡𝗧𝗦! 🧪🔥 And I have the REAL benchmark results to prove it! 🤯 Remember my DeepSeek V4.1 Flash 1017 SAGE-EXL3 release from YESTERDAY? 📦 1.62 bpw routed experts 💻 99.61% code answer-token agreement 🖥️ ONE DGX Spark @nvidiaai Well, I promised to go beyond KL divergence and token agreement and test ACTUAL coding, mathematics, reasoning and tool execution. 𝗧𝗛𝗘 𝗥𝗘𝗦𝗨𝗟𝗧𝗦 𝗔𝗥𝗘 𝗜𝗡! ━━━━━━━━━━━━━━━━━━━━ 🏆 𝗗𝗘𝗘𝗣𝗦𝗘𝗘𝗞 𝗩𝟰.𝟭 𝗙𝗟𝗔𝗦𝗛 𝟭𝟬𝟭𝟳 — 𝗡𝗜𝗡𝗘-𝗦𝗨𝗜𝗧𝗘 𝗦𝗛𝗢𝗪𝗗𝗢𝗪𝗡 353 matched benchmark questions. 9 evaluation suites. Strict pass@1 scoring. Temperature 0. 🟢 𝗠𝗬 𝗦𝗔𝗚𝗘-𝗘𝗫𝗟𝟯 — 𝟭.𝟲𝟮 𝗕𝗣𝗪 🖥️ 1× DGX Spark 🏆 𝟵𝟰.𝟭% — 𝟯𝟯𝟮/𝟯𝟱𝟯 𝗣𝗔𝗦𝗦𝗘𝗗! 🔵 𝗝𝗝 𝗡𝗘𝗪 — 𝟮.𝟴 𝗕𝗣𝗪 🖥️ 2× DGX Sparks 📊 90.1% — 318/353 🟣 𝗠𝗜𝗔𝗟𝗔𝗕 — 𝟮.𝟵 𝗕𝗣𝗪 🖥️ 2× DGX Sparks 📊 88.4% — 312/353 𝗜'𝗠 𝗨𝗦𝗜𝗡𝗚 𝟰𝟮–𝟰𝟰% 𝗙𝗘𝗪𝗘𝗥 𝗕𝗜𝗧𝗦 𝗣𝗘𝗥 𝗥𝗢𝗨𝗧𝗘𝗗 𝗘𝗫𝗣𝗘𝗥𝗧 𝗣𝗔𝗥𝗔𝗠𝗘𝗧𝗘𝗥... 𝗔𝗡𝗗 𝗦𝗖𝗢𝗥𝗜𝗡𝗚 𝗛𝗜𝗚𝗛𝗘𝗥 𝗢𝗡 𝗢𝗡𝗘 𝗦𝗣𝗔𝗥𝗞! 🤯 ━━━━━━━━━━━━━━━━━━━━ 💻 𝗧𝗛𝗘 𝗖𝗢𝗗𝗜𝗡𝗚 𝗥𝗘𝗦𝗨𝗟𝗧𝗦 𝗔𝗥𝗘 𝗜𝗡𝗖𝗥𝗘𝗗𝗜𝗕𝗟𝗘! Scores shown as SAGE / JJ / Mia: 🏆 HumanEval+ 39/40 vs 34/40 vs 34/40 🏆 MBPP+ 53/60 vs 50/60 vs 49/60 🏆 LiveCodeBench 15/17 vs 14/17 vs 11/17 🧠 𝗥𝗘𝗔𝗦𝗢𝗡𝗜𝗡𝗚 & 𝗠𝗔𝗧𝗛 🏆 MMLU-Pro STEM 95/100 vs 93/100 vs 91/100 🏆 MATH-500 40/40 vs 36/40 vs 36/40 𝗙𝗜𝗩𝗘 𝗢𝗨𝗧𝗥𝗜𝗚𝗛𝗧 𝗪𝗜𝗡𝗦! 🔥 I also tied both models on: ✅ MGSM: 40/40 ✅ BFCL: 39/40 ✅ SciCode first-step: 6/10 For full transparency, both JJ and Mia won the multi-step tool-chain test, scoring 6/6 against my 5/6. 𝗦𝗢 𝗧𝗛𝗔𝗧'𝗦 𝟱 𝗪𝗜𝗡𝗦, 𝟯 𝗧𝗜𝗘𝗦, 𝗔𝗡𝗗 𝟭 𝗟𝗢𝗦𝗦. All while using a substantially lower expert bitrate! ━━━━━━━━━━━━━━━━━━━━ 🚀 𝗕𝗜𝗚 𝗨𝗣𝗗𝗔𝗧𝗘: 𝗠𝗬 𝗣𝗨𝗕𝗟𝗜𝗖 𝘃𝗟𝗟𝗠 𝗥𝗘𝗖𝗜𝗣𝗘 𝗜𝗦 𝗡𝗢𝗪 𝗣𝗨𝗦𝗛𝗜𝗡𝗚 𝟱𝟮𝟰𝗞 𝗖𝗢𝗡𝗧𝗘𝗫𝗧! YES. ON ONE DGX SPARK! 🤯 With the latest W2 kernel, updated expert set and KV-cache configuration, I just completed an actual long-context retrieval test! 📚 𝗙𝗨𝗟𝗟-𝗟𝗘𝗡𝗚𝗧𝗛 𝗣𝗥𝗢𝗠𝗣𝗧 𝗧𝗘𝗦𝗧 🧠 518,103 INPUT TOKENS! 🎯 Fact planted HALFWAY through the context ✅ THE MODEL FOUND THE FACT! ⏱️ Time to first token: 470 seconds (~7.8 minutes) 🚀 Prefill: ~1,100 tok/s ⚡ Decode at that context depth: 25.6 tok/s 💾 Minimum available memory: 2.19 GiB 🛡️ Memory safety floor: 0.5 GiB And on SHORTER prompts? ⚡ ~36 TOK/S DECODE! 🔧 ~130.5 ms per speculative step 🎯 ~4.7 accepted tokens per step 𝗪𝗘'𝗥𝗘 𝗧𝗔𝗟𝗞𝗜𝗡𝗚 𝗔𝗕𝗢𝗨𝗧 𝗢𝗩𝗘𝗥 𝗛𝗔𝗟𝗙 𝗔 𝗠𝗜𝗟𝗟𝗜𝗢𝗡 𝗜𝗡𝗣𝗨𝗧 𝗧𝗢𝗞𝗘𝗡𝗦 𝗣𝗥𝗢𝗖𝗘𝗦𝗦𝗘𝗗 𝗢𝗡 𝗔 𝗦𝗜𝗡𝗚𝗟𝗘 𝗦𝗣𝗔𝗥𝗞! 🔥 To be clear, this was a successful full-length retrieval test, not a claim of perfect accuracy across every possible long-context task. And the 7.8-minute prefill is a real trade-off at that depth. But seeing a model this large, with this level of compression, successfully retrieve information buried inside 518K tokens on ONE 128GB machine is an exciting milestone for local AI! ━━━━━━━━━━━━━━━━━━━━ ⚡ 𝗔𝗡𝗗 𝗧𝗛𝗘 𝗢𝗡𝗘-𝗦𝗣𝗔𝗥𝗞 𝗣𝗘𝗥𝗙𝗢𝗥𝗠𝗔𝗡𝗖𝗘 𝗞𝗘𝗘𝗣𝗦 𝗜𝗠𝗣𝗥𝗢𝗩𝗜𝗡𝗚! Separately, my latest REXL3 development measurements at a 256K context configuration: ⚡ 55.35 tok/s single-stream decode 🚀 2,045 tok/s peak prefill ⏱️ 509 ms TTFT on a 512-token prompt Those REXL3 numbers come from a different engine and workload than the new public vLLM 518K-token test. And here's something else I'm particularly excited about... 𝗔𝗟𝗟 𝟭𝟱,𝟯𝟲𝟬 𝗥𝗢𝗨𝗧𝗘𝗗 𝗘𝗫𝗣𝗘𝗥𝗧𝗦 + 𝟯𝟴𝟰 𝗗𝗥𝗔𝗙𝗧 𝗘𝗫𝗣𝗘𝗥𝗧𝗦 𝗔𝗥𝗘 𝟭𝟬𝟬% 𝗚𝗣𝗨-𝗥𝗘𝗦𝗜𝗗𝗘𝗡𝗧 𝗜𝗡 𝗠𝗬 𝗧𝗘𝗦𝗧𝗘𝗗 𝗥𝗘𝗫𝗟𝟯 𝗖𝗢𝗡𝗙𝗜𝗚𝗨𝗥𝗔𝗧𝗜𝗢𝗡! ZERO streamed experts. 𝗢𝗡𝗘. 𝟭𝟮𝟴𝗚𝗕. 𝗗𝗚𝗫. 𝗦𝗣𝗔𝗥𝗞. 💚 @mr_r0b0t and I are continuing to refine REXL3 before its release. More on that soon! 👀 ━━━━━━━━━━━━━━━━━━━━ 💚 𝗧𝗛𝗜𝗦 𝗜𝗦 𝗪𝗛𝗬 𝗜 𝗕𝗨𝗜𝗟𝗗 𝗙𝗢𝗥 𝗟𝗢𝗖𝗔𝗟 𝗔𝗜. Just YESTERDAY, I shared my goal of bringing extremely aggressive, high-quality quantization to people who don't have access to massive compute clusters. With the support of @AWERXAI, I've been working tirelessly to push that vision forward. And now we're seeing a 1.62 bpw expert quant outperform higher-bitrate alternatives on actual tasks, not just token-level fidelity measurements. This doesn't establish mathematical losslessness or superiority on every possible workload. These are matched subsets of nine benchmark suites, not full public leaderboard scores. But it demonstrates something IMPORTANT: 𝗠𝗢𝗥𝗘 𝗕𝗜𝗧𝗦 𝗗𝗢𝗡'𝗧 𝗔𝗨𝗧𝗢𝗠𝗔𝗧𝗜𝗖𝗔𝗟𝗟𝗬 𝗠𝗘𝗔𝗡 𝗕𝗘𝗧𝗧𝗘𝗥 𝗥𝗘𝗦𝗨𝗟𝗧𝗦. And more hardware doesn't automatically mean you need it! Huge respect to @jayleaton for his contributions and for giving the community more ways to run these incredible models. And thank you @AWERXAI for supporting this work. 🙏 🔗 𝗠𝗬 𝗦𝗔𝗚𝗘-𝗘𝗫𝗟𝟯 𝗤𝗨𝗔𝗡𝗧 https://huggingface.co/vcruz305/DSV4.1-Flash-1017-SAGE-EXL3-1.62bpw 🛠️ 𝗢𝗡𝗘-𝗦𝗣𝗔𝗥𝗞 𝘃𝗟𝗟𝗠 𝗥𝗘𝗖𝗜𝗣𝗘 https://github.com/vcruz305/DSV4.1-Flash-1017-EXL3-Spark-recipe 𝗙𝗥𝗢𝗡𝗧𝗜𝗘𝗥 𝗠𝗢𝗗𝗘𝗟𝗦. 𝗟𝗢𝗖𝗔𝗟 𝗛𝗔𝗥𝗗𝗪𝗔𝗥𝗘. 𝗥𝗘𝗔𝗟 𝗥𝗘𝗦𝗨𝗟𝗧𝗦. 𝗟𝗘𝗧'𝗦 𝗞𝗘𝗘𝗣 𝗣𝗨𝗦𝗛𝗜𝗡𝗚! 🚀🔥
这条是引用着另一条写的:「单张 DGX Spark 上 V4.1 Flash 1.62bpw 量化:35.5 tok/s」