deepseek-v4.1IMAGE
vLLM 在 AgentX 上跑 DeepSeek V4.1 Flash:954K tok/s/GPU
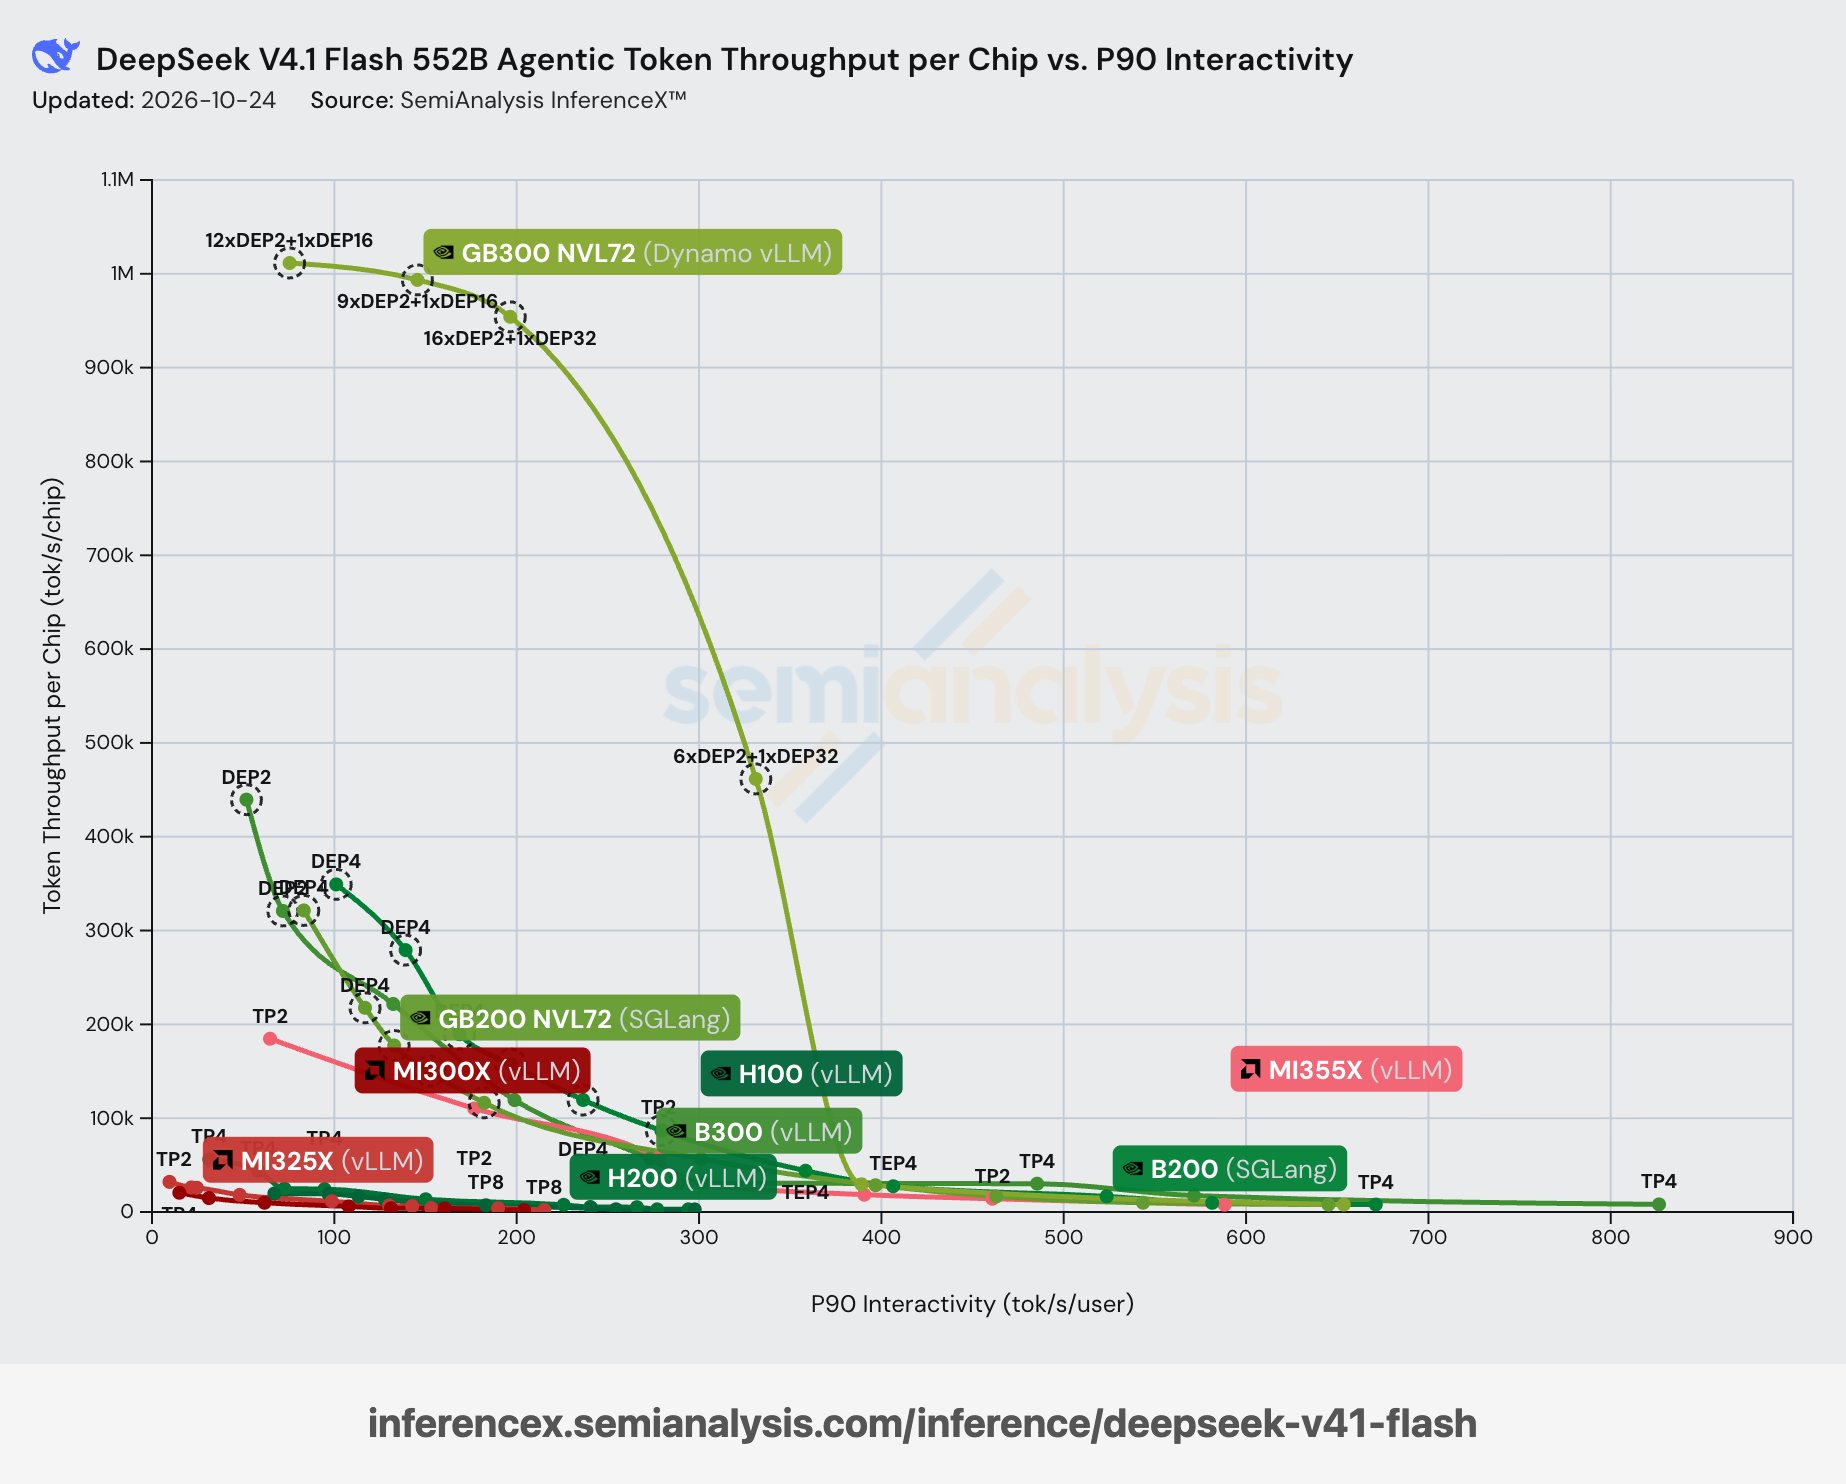
vLLM 官方称在 SemiAnalysis AgentX 真实 agent 负载下,DeepSeek V4.1 Flash 达到 954K tokens/s/GPU 总吞吐、P90 每用户 196 tok/s,按 DeepSeek 闲时定价折合 $38.96/GPU 小时收入。
vLLM
@vllm_project5 天前收录原推发布于 2026.10.25
vLLM @vllm_project原推发布于 2026.10.25
Beyond matching DeepInfer's performance, we also put vLLM to the test on @SemiAnalysis_ AgentX with real-world agentic workloads. At DeepSeek's off-peak pricing, vLLM delivers $38.96/GPU-hour revenue, with 954K tokens/s/GPU total throughput (cached+input+output) at 196 tokens/s P90 per user. This is the best DeepSeek-V4.1-Flash result on AgentX ever, powered by recent advancement in vLLM! Check out our blog for the full optimization story and how to reproduce the results 👇 Enjoy the read.
这条是引用着另一条写的:「vLLM 在 GB300 NVL72 上服务 V4.1 Flash:单 GPU 954K tok/s」
x.com/vllm_project/status/2114135647040778667采集于 2026.10.25 12:00